AA-3D: Interactive 3D Experience Benchmark

AA-3D
AA-3D 리더보드
범위 | 모델 | Elo | |
|---|---|---|---|
| 1 | 1-2 |  Claude Sonnet 5.5 (Max, Default Fallback) | 1199±3395% 구간 1166~1231 |
| 2 | 1-3 | Claude Opus 5.5 (Max, Default Fallback) | 1196±3395% 구간 1164~1229 |
| 3 | 3-5 |  GPT-6 Astra (Max) | 1164±3295% 구간 1132~1196 |
| 4 | 3-6 |  Gemini 4 Argon (High) | 1153±3395% 구간 1120~1186 |
| 5 | 3-8 | Claude Fable 5.1 (Max, Default Fallback) | 1135±3295% 구간 1103~1167 |
| 6 | 4-8 | GPT-6 Sol (Max) | 1121±3295% 구간 1089~1153 |
| 7 | 5-8 | GPT-6.1 Sol (Max) | 1119±3295% 구간 1088~1151 |
| 8 | 5-8 |  Kimi K3.1 Pro | 1110±3395% 구간 1078~1143 |
| 9 | 9 |  Muse Spark 1.3 (Max) | 1033±3195% 구간 1003~1064 |
| 10 | 10 | GPT-6 Luna (Max) | 1000기준이 리더보드 Elo 척도의 기준점으로 1000에 고정되어 있습니다. |
| 11 | 10-14 | Claude Haiku 5.5 (Max) | 998±3195% 구간 967~1028 |
| 12 | 10-15 |  Grok 4.7 (Xhigh) | 995±3195% 구간 964~1025 |
| 13 | 10-15 |  MiMo-V2.6-Pro | 983±3195% 구간 952~1014 |
| 14 | 10-15 | Kimi K3 (Max) | 982±3195% 구간 951~1013 |
| 15 | 12-17 | Gemini 3.8 Flash (High) | 966±3195% 구간 935~997 |
| 16 | 15-17 |  Qwen3.8 Max (0902) | 945±3195% 구간 914~976 |
| 17 | 15-17 |  GLM-5.3-Flash | 937±3195% 구간 906~967 |
| 18 | 18-19 |  Mistral Large 4 Preview | 870±3195% 구간 839~901 |
| 19 | 18-19 |  Step 5 Preview | 854±3295% 구간 821~886 |
| 20 | 20 | GLM-5.3 (Max) | 783±3495% 구간 749~817 |
| 21 | 21 |  MiniMax-M3 | 740±3395% 구간 707~773 |
| 22 | 22-23 |  Inkling (Xhigh) | 583±4095% 구간 543~623 |
| 23 | 22-23 |  Nemotron 3 Ultra 550B A55B (Reasoning) | 573±4395% 구간 529~616 |
AA-3D Elo
AA-3D Elo
AA-3D: Elo vs. 작업당 비용
분야, 작업, 모델을 선택하면 해당 모델이 구축한 장면을 불러옵니다.
작업
모델
Create an interactive adult man performing weightlifting exercises, with views that expose his muscles, skeleton and organs in anatomically accurate form.
블라인드 투표에는 23개 모델 중 23개 모델이 만든 이 작업의 장면이 있습니다.
Elo vs. Intelligence Index
AA-3D Elo vs. Intelligence Index
분야별 승률
각 셀은 현재 리더보드의 기반이 되는 투표 중 모델이 한 작업 분야에서 이긴 투표의 비율을 보여 줍니다. 상대 균등 보기는 분야에서 만난 각 상대에 대한 모델의 승률을 평균하므로 모든 상대가 같은 비중으로 계산됩니다.
AA-3D 분야별 승률
비용
AA-3D: 작업당 비용
토큰 사용량
AA-3D: 작업당 출력 토큰
장면당 턴 수
AA-3D 장면당 턴 수
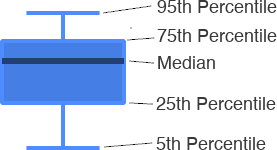
도구 사용
AA-3D 장면당 도구 호출
AA-3D 작동 방식
각 모델은 오프라인 샌드박스에서 에이전트로 작업합니다. 하나의 인터랙티브 장면에 대한 서면 작업 설명과 모든 작업에 공통으로 적용되는 납품 규격을 받습니다. 모델은 코드를 작성하고, 장면을 렌더링하고, 자체 스크린샷을 확인한 뒤 수정합니다. Blender, Rapier 물리 엔진, Python, 헤드리스 브라우저, CC0 에셋 라이브러리를 사용할 수 있습니다. 실행은 3시간 또는 250턴이 지나면 종료됩니다. 결과물은 브라우저에서 장면을 실행하는 index.html 페이지입니다.
에이전트 실행 들여다보기
이 리플레이는 AA-3D 출시 시점의 데이터를 사용합니다. 작업을 선택하면 각 모델의 실행을 공통 시계로 재생합니다. 레인에 마우스를 올리면 각 동작을 볼 수 있고, 클릭하면 시간 사용 내역을 볼 수 있습니다.
장면이 구축되는 과정 보기
점수 vs. 출시일
AA-3D: 점수 vs. 출시일
자주 묻는 질문
AA-3D v1.0은 AI 모델이 인터랙티브 3D 경험을 얼마나 잘 구축하는지 측정합니다. 각 모델은 서면 작업 설명을 받고, 오프라인 샌드박스에서 three.js로 단일 웹 페이지를 구축합니다. 이 벤치마크는 7개 분야에 걸친 55개 작업으로 구성됩니다. AA-3D 방법론 읽기
모델은 당사가 모집한 인간 평가자 패널의 블라인드 비교로 산출한 Elo 평점 시스템으로 순위가 매겨집니다. 패널 참가자는 동일한 작업을 위해 구축된 두 장면을 직접 조작해 보고, 어떤 모델이 어느 장면을 만들었는지 모른 채 선호하는 장면을 선택합니다. Elo 점수가 높을수록 해당 모델이 더 자주 선호된다는 뜻입니다. AA-3D 투표에 참여하기
평가 살펴보기
 Artificial Analysis Intelligence Index v5.0
A composite benchmark aggregating nine challenging evaluations to provide a holistic measure of AI capabilities across knowledge work, coding, science, and general knowledge.
AA-Briefcase v1.1: Agentic Knowledge Work BenchmarkA private evaluation developed by Artificial Analysis for frontier agentic capability in long-horizon knowledge work, testing agents on realistic business workflows that require deliverables such as spreadsheets, presentations, and memos.
AA-3D: Interactive 3D Experience BenchmarkA benchmark developed by Artificial Analysis for how well AI models build interactive 3D experiences. Models work as agents in an offline sandbox via Stirrup to turn a written brief into a three.js scene, with Elo ratings derived from blind pairwise votes.
 APEX-Agents-AA Benchmark
Artificial Analysis' implementation of the APEX-Agents benchmark, testing AI agents on long-horizon, cross-application tasks in professional-services environments with realistic application tooling.
AA-AnalystAgent BenchmarkArtificial Analysis' data analysis benchmark, testing AI agents on their ability to work with spreadsheets and documents to answer quantitative questions a Business Analyst or Data Analyst would face day-to-day.
 AutomationBench-AA: Agentic SaaS Workflow Benchmark
A benchmark measuring agentic task completion across simulated SaaS application environments, scoring the share of each task's objectives completed without guardrail violations.
 Harvey LAB-AA v1.1 Benchmark
Artificial Analysis' implementation of Harvey's Legal Agent Benchmark (LAB), testing AI agents on real-world legal work from Harvey's dataset of 120 private tasks spanning 24 legal practice areas. v1.1, built in collaboration with Harvey, checks every deliverable against the task's source documents for hallucinations, so work that passes every rubric criterion but contains a material hallucination receives no credit. A panel of three judges grades each deliverable criterion-by-criterion.
 GDP.pdf Benchmark
Artificial Analysis' implementation of Surge AI's GDP.pdf benchmark, testing whether language models can reason over long, real-world professional documents and satisfy detailed task-specific criteria.
 EnterpriseOps-Gym-AA Benchmark
Artificial Analysis' independent implementation of ServiceNow's EnterpriseOps-Gym, an agentic benchmark testing whether LLM agents can complete stateful, multi-step enterprise workflows across eight business domains via live tool use, graded on the final state of the underlying databases.
 Terminal-Bench 4.0 Benchmark
A harder 66-task benchmark of complex terminal work across software, machine learning, science, operations, security, hardware, and media, with recalibrated compute and time allowances and improved instructions, environments, and verifiers.
 Terminal-Bench-Science 0.1 Benchmark
A 70-task benchmark of research workflows authored and reviewed by domain experts across the life, physical, earth, mathematical, and engineering sciences, each completed in a terminal and checked by its own set of tests.
 FrontierCode 2.0 Benchmark
Artificial Analysis' implementation of Cognition's FrontierCode 2.0, a private agentic coding benchmark of 132 tasks in real open-source repositories, graded on whether a maintainer would merge the agent's change.
 HLE-Diamond Benchmark
A refined and updated 1,000-question set of Humanity's Last Exam, split evenly between reasoning and knowledge questions, with 272 questions that include an image.
AA-PersonalityBench: AI Personality & Communication Style BenchmarkMeasures how models communicate rather than whether they are correct: 30 judged personality traits rolled up into 8 indexes, plus 21 measured communication characteristics.
AA-Omniscience v1.1: Knowledge and Hallucination BenchmarkA benchmark measuring factual recall and hallucination across various economically relevant domains.
The most challenging 198 questions from GPQA, where PhD experts achieve 65% accuracy but skilled non-experts only reach 34% despite web access.
 ITBench-AA Benchmark
Artificial Analysis' implementation of IBM's ITBench benchmark, testing AI agents on Kubernetes incident root-cause analysis from offline incident snapshots. The agent inspects alerts, events, traces, and topology and identifies the contributing-factor entities (deployments, pods, namespaces, network policies, etc.) responsible for the failure.
 MMMU-Pro Benchmark
An enhanced MMMU benchmark that eliminates shortcuts and guessing strategies to more rigorously test multimodal models across 30 academic disciplines.
 IFBench Benchmark
A benchmark evaluating precise instruction-following generalization on 58 diverse, verifiable out-of-domain constraints that test models' ability to follow specific output requirements.
 MLCR-AA: Medical Long Context Reasoning Benchmark
An open benchmark from Wisedocs measuring how well models reason over long, fragmented medical records, performing the multi-document synthesis claims professionals rely on when reviewing insurance and healthcare cases.
 Code2Video-AA Benchmark
Artificial Analysis' implementation of HeyGen's Code2Video Bench, evaluating how well models create short product and brand videos from 114 design briefs using HyperFrames HTML.
HealthBench BenchmarkOpenAI's HealthBench: 5,000 health conversations graded against physician-written rubrics, from emergency referrals to global health.
 CritPt v2 Benchmark
CritPt v2 is the revised version of CritPt, a benchmark designed to test LLMs on research-level physics reasoning tasks, featuring 70 composite research challenges. Models solve problems with a code-execution tool in an offline Linux sandbox.
GDPval-AA v2.1 BenchmarkGDPval-AA v2.1 is Artificial Analysis' evaluation framework for OpenAI's GDPval dataset. It tests AI models on real-world tasks across 44 occupations and 9 major industries. Models are given shell access and web browsing capabilities in an agentic loop via Stirrup to solve tasks, with Elo ratings derived from blind pairwise comparisons.
 𝜏³-Banking Benchmark
A fintech customer-support benchmark from the 𝜏-Knowledge framework that tests whether agents can navigate a large unstructured knowledge base and execute multi-step tool calls to resolve realistic banking workflows.
Terminal-Bench 2.1 BenchmarkA verified refresh of Terminal-Bench 2.0: 89 curated tasks across software engineering, system administration, data processing, model training, and security, with environment and instruction fixes so scores reflect agent capability rather than environment gaps.
FrontierCode 1.1 BenchmarkArtificial Analysis' implementation of Cognition's FrontierCode 1.1, a private agentic coding benchmark that tests models on completing coding tasks in a way that would actually get merged by maintainers of real-world repositories.
AA-LCR v1.1: Long Context Reasoning BenchmarkA challenging benchmark measuring language models' ability to extract, reason about, and synthesize information from long-form documents ranging from 10k to 100k tokens (measured using the cl100k_base tokenizer).
 SciCode Benchmark
A scientist-curated coding benchmark featuring 288 test set subproblems from 80 laboratory problems across 16 scientific disciplines.
Humanity's Last Exam BenchmarkA frontier-level benchmark with 2,500 expert-vetted questions across mathematics, sciences, and humanities, designed to be the final closed-ended academic evaluation.
CritPt BenchmarkA benchmark designed to test LLMs on research-level physics reasoning tasks, featuring 71 composite research challenges.
Terminal-Bench Hard BenchmarkAn agentic benchmark evaluating AI capabilities in terminal environments through software engineering, system administration, and data processing tasks.
𝜏²-Bench Telecom BenchmarkA dual-control conversational AI benchmark simulating technical support scenarios where both agent and user must coordinate actions to resolve telecom service issues.
 MMLU-Pro Benchmark
An enhanced version of MMLU with 12,000 graduate-level questions across 14 subject areas, featuring ten answer options and deeper reasoning requirements.
 LiveCodeBench Benchmark
A contamination-free coding benchmark that continuously harvests fresh competitive programming problems from LeetCode, AtCoder, and CodeForces, evaluating code generation, self-repair, and execution.
MATH-500 BenchmarkA 500-problem subset from the MATH dataset, featuring competition-level mathematics across six domains including algebra, geometry, and number theory.
 AIME 2025 Benchmark
All 30 problems from the 2025 American Invitational Mathematics Examination, testing olympiad-level mathematical reasoning with integer answers from 000-999.
 Global-MMLU-Lite Benchmark
A lightweight, multilingual version of MMLU, designed to evaluate knowledge and reasoning skills across a diverse range of languages and cultural contexts.