Vision Models: LLMs with Image Input Capabilities
Compare multimodal LLMs that support image and text input with the Artificial Analysis Visual Reasoning Index. Compare performance, pricing, and latency across providers to choose the best image-capable LLM for vision workloads. For further details, see the methodology page.
Highlights
Summary Analysis
Visual Reasoning vs. Image Input Price
Visual reasoning intelligence: MMMU Pro evaluation · Image input price: USD per 1k images at 1MP (1024x1024)
Most attractive quadrant
Visual Reasoning vs. Latency (Single Image & 1,000 Language Tokens Input)
Visual reasoning intelligence: MMMU Pro evaluation · Seconds to first token received
Most attractive quadrant
Intelligence
Visual Reasoning Intelligence (MMMU Pro evaluation)
Visual reasoning intelligence: MMMU Pro evaluation
Pricing
Pricing: Image Input Pricing
Image input price: USD per 1k images at 1MP (1024x1024)
Pricing: Language Input, Image Input and Language Output
Price (USD per M Tokens) · Image input price: USD per 1k images at 1MP (1024x1024) · Lower is better
Latency & Speed
Latency (Single Image & 1,000 Language Tokens Input)
Seconds to first token received · Lower is better
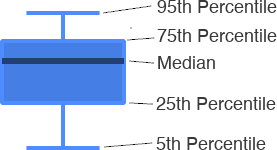
Latency Variance (Single Image & 1,000 Language Tokens Input)
Seconds to first token received · Results by percentile · Lower is better
Output Speed (Single Image & 1,000 Language Tokens Input)
Output tokens per second · Higher is better