MicroEvals
Run your prompts across multiple models to compare their performance.
Public evaluations
Showing 12021-12040 of 13036
👍0
How to prompt LLM agents properly
👍0
what is the best free ai for research
👍0
You are an administrative operations lead in a government de...
👍0
Jsi expertní vědecký, medicínský a Evidence-Based Medicine a...
👍0
Introduce yourself
👍0
Make a roadmap with the best resources to learn PHILOSOPHY o...
👍0
Project Blackbox
👍0
Jsi nezávislý red-team evaluátor řídicího promptu LLM. Odpov...
👍0
botanicula

👍0
สวัสดี
👍0
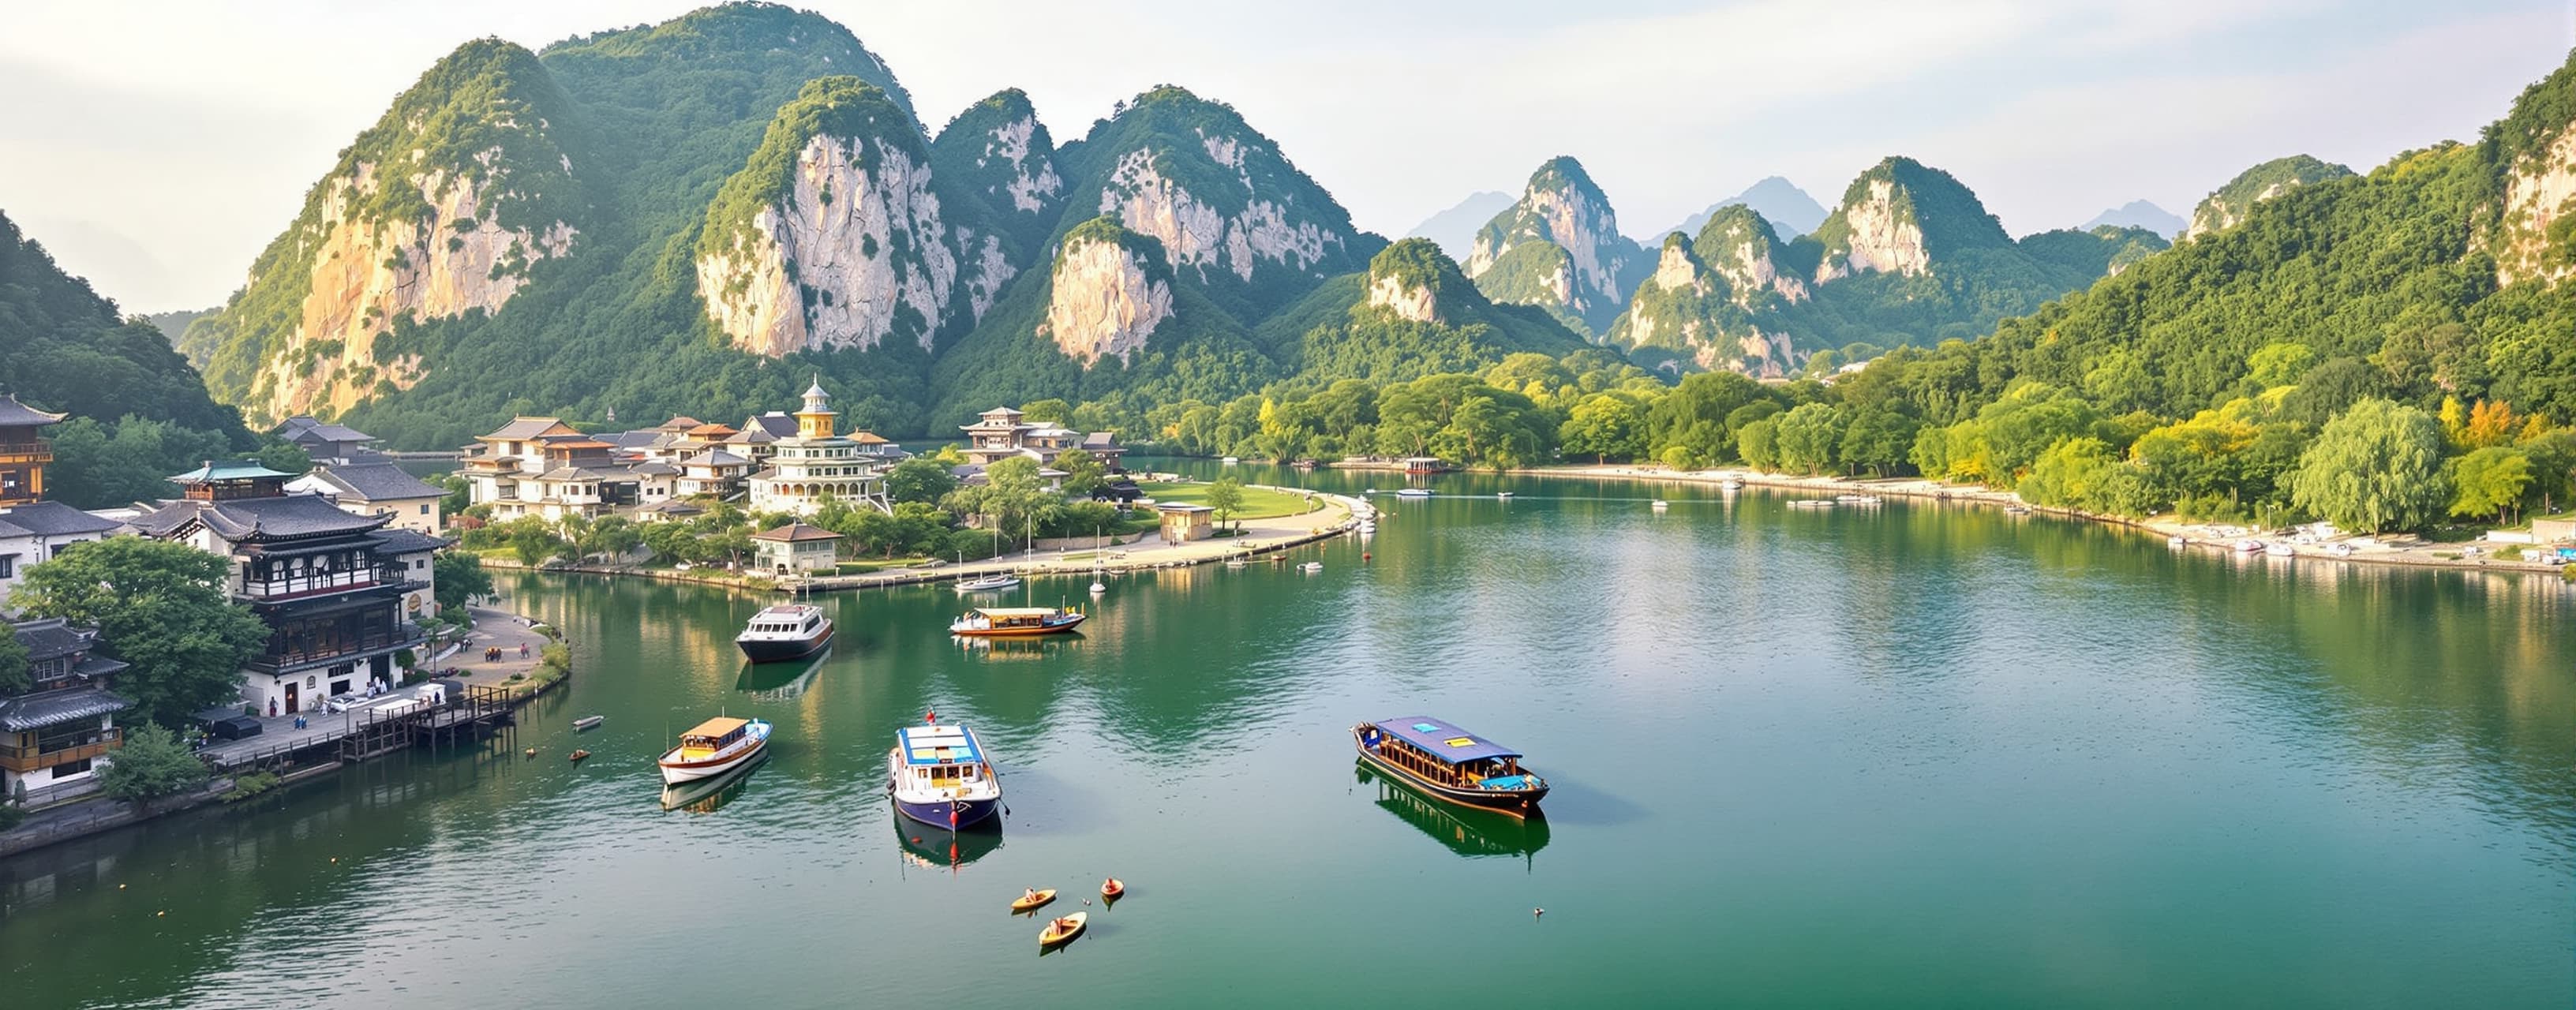
I am planning a trip to Hangzhou province, and I would like ...
👍0
# CLAUDE.md
Behavioral guidelines to reduce common LLM codi...
👍0
test comparaison intelligence model
comparaison intelligence model
👍0
Berätta om barnboken "Pippi och spöket på Jönköpings central...
👍0
Code Eval
👍0
你好 你是什么模型
👍0
Act as a professional buy-side equity research analyst worki...
👍0
What's initContainer in kubernetes
👍0
AI Predvidjanje izbora Srbija
👍0
You are an expert in HTML, CSS, and JavaScript development. ...