Artículos
Mostrando 61-72 de 128 artículos

Announcing Harvey LAB-AA: evaluating AI agents on real-world legal work
7 de julio de 2026
Announcing AutomationBench-AA
6 de julio de 2026

Claude Sonnet 5: strong agentic performance at a higher cost per task
30 de junio de 2026

Measuring time per task in AA-Briefcase
24 de junio de 2026

Announcing the Artificial Analysis Speech to Speech Index
23 de junio de 2026

Announcing AA-Briefcase: a frontier knowledge work evaluation
18 de junio de 2026
GLM-5.2 is the new leading open weights model on the Artificial Analysis Intelligence Index
16 de junio de 2026
Artificial Analysis Intelligence Index v4.1: a shift toward agentic workloads
15 de junio de 2026
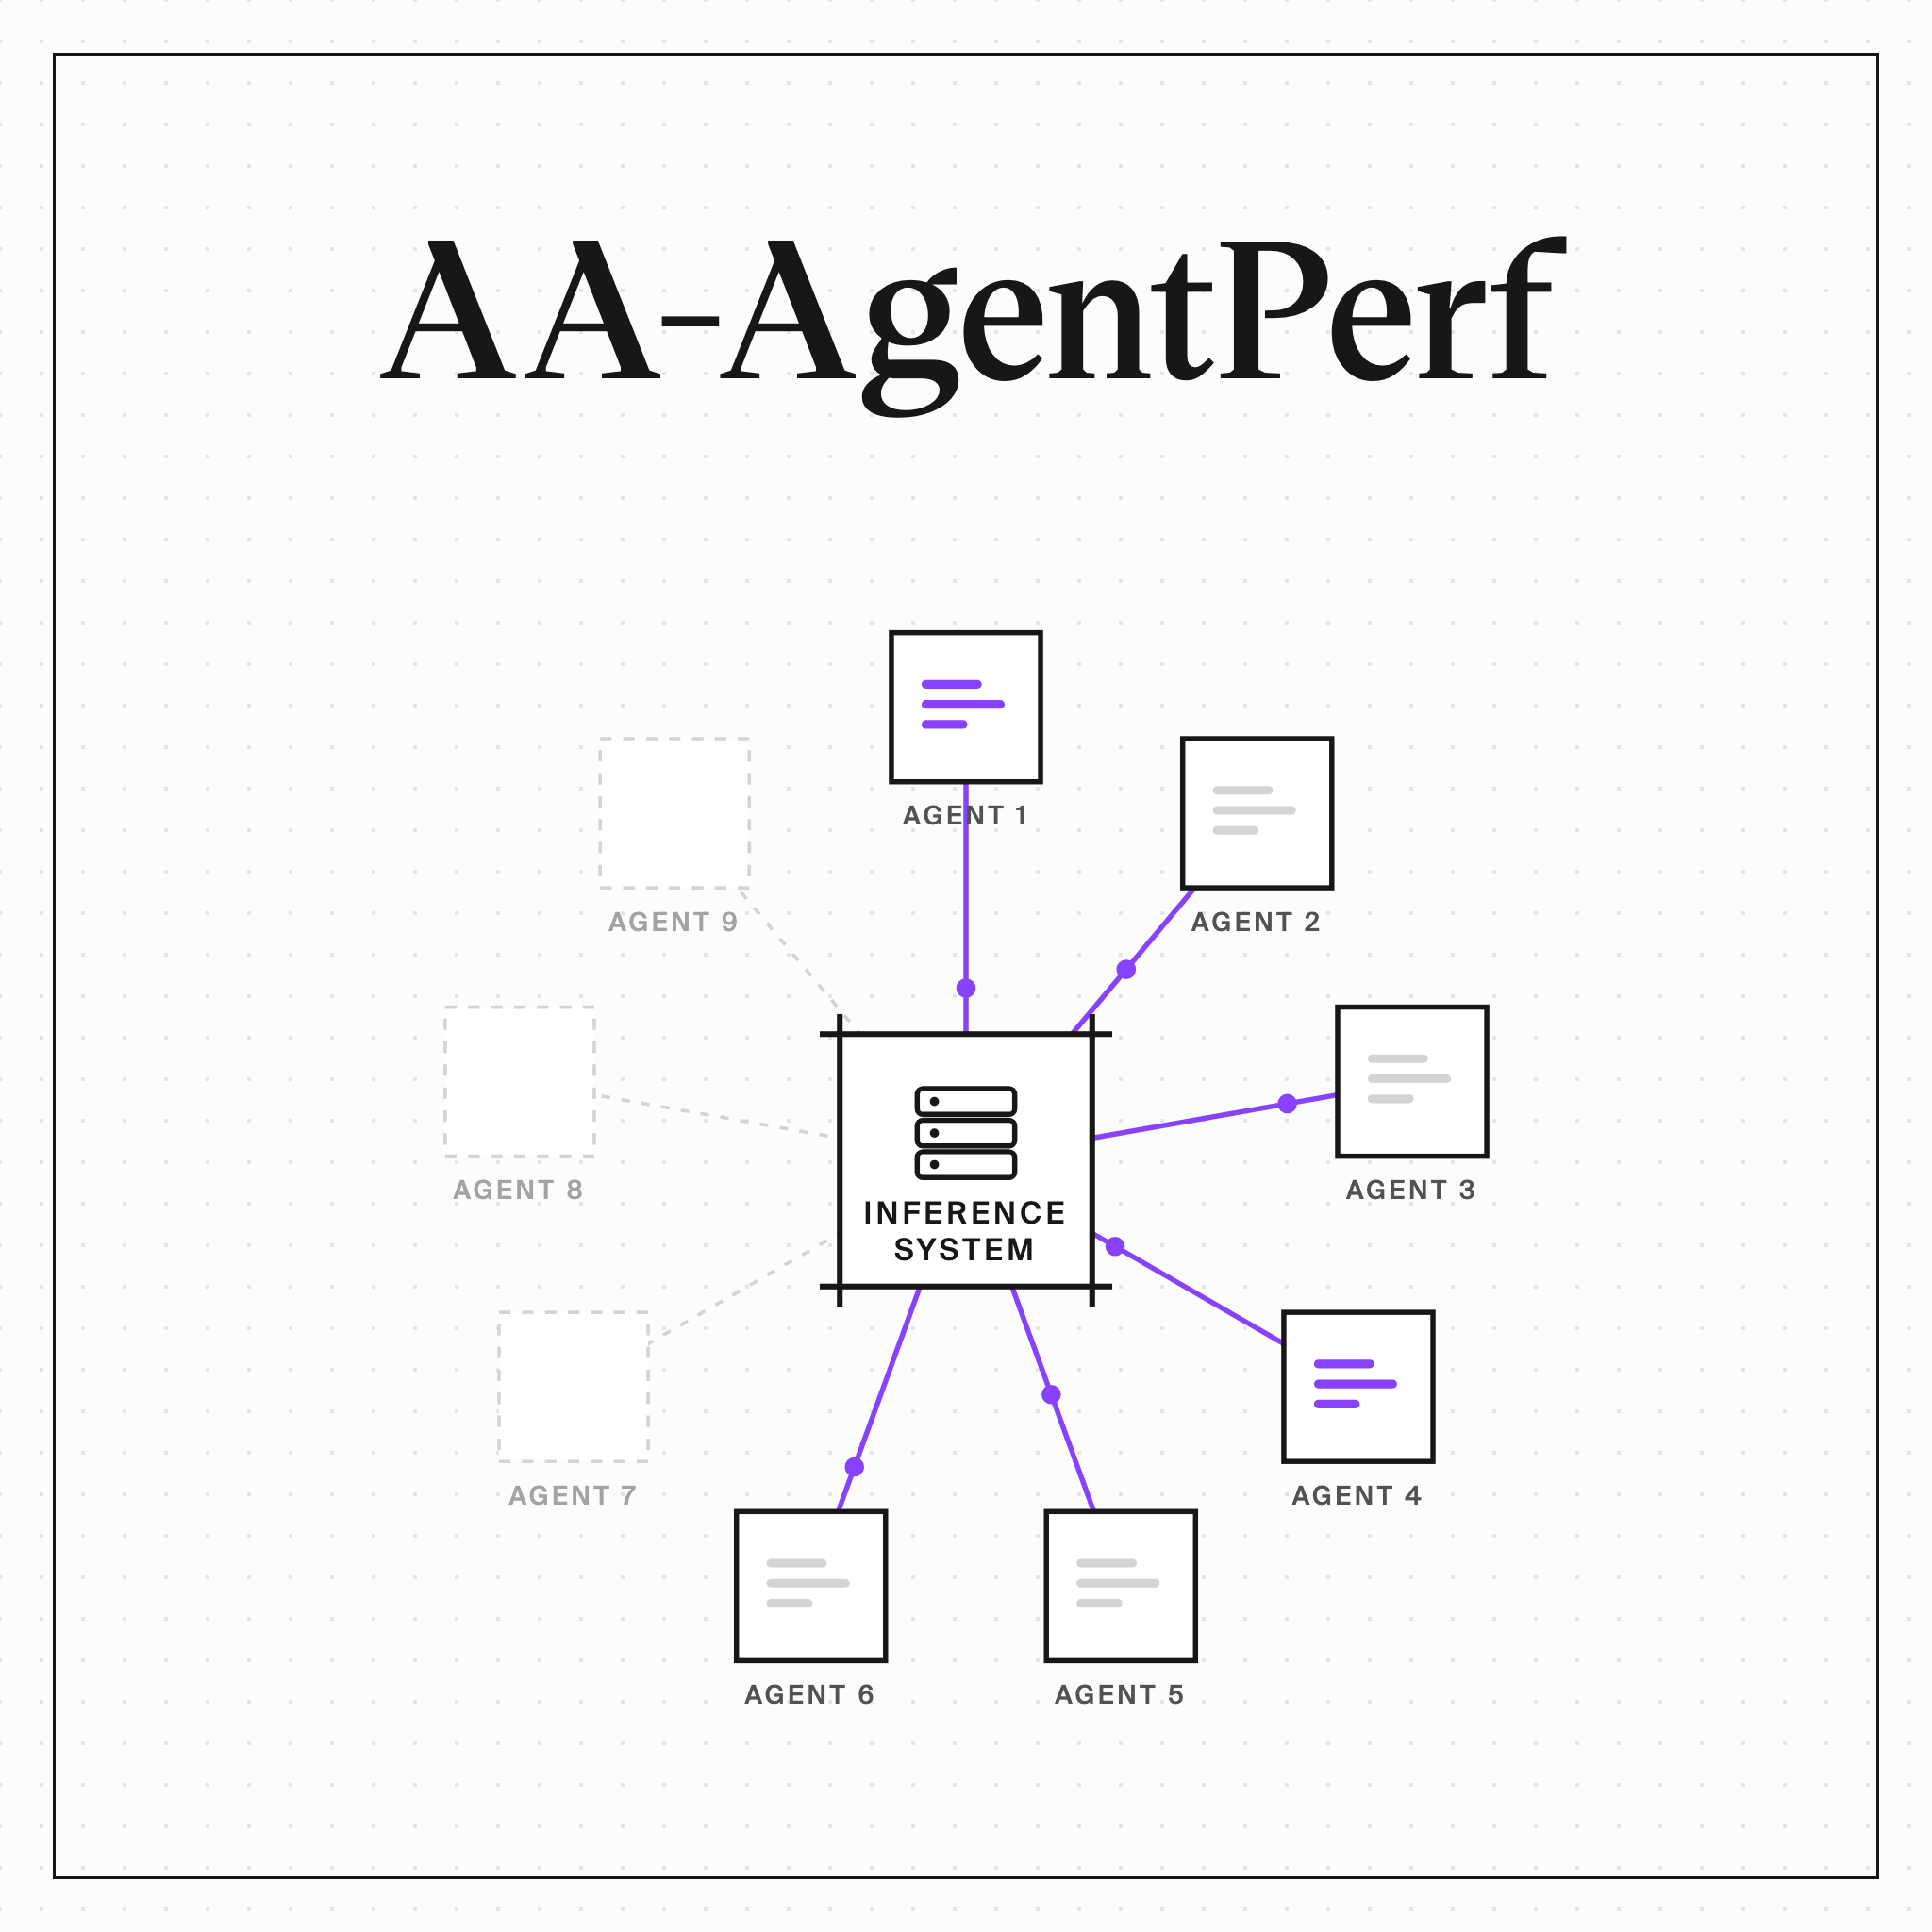
First results from AA-AgentPerf: the hardware benchmark for the agent era
12 de junio de 2026

Benchmarking guardrail models for safety, refusal, and latency
11 de junio de 2026

Claude Fable 5 Launches at #1 on the Artificial Analysis Intelligence Index
9 de junio de 2026

Claude Fable 5: the first public Mythos-class model
9 de junio de 2026