June 23, 2026
Announcing the Artificial Analysis Speech to Speech Index
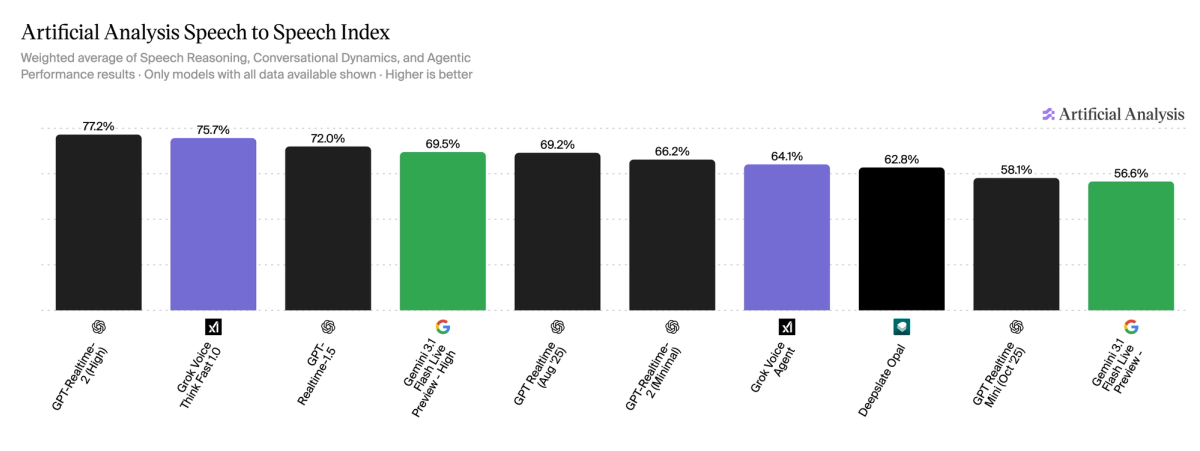
Announcing the Artificial Analysis Speech to Speech Index, our new synthesis metric for native Speech to Speech model quality, comprising of Big Bench Audio, Full Duplex Bench, and 𝜏-Voice
The index provides a single measure of how well native Speech to Speech models perform, assessing Speech Reasoning (Big Bench Audio), Conversational Dynamics (Full Duplex Bench subset), and Agentic Performance (𝜏-Voice). Weighting is equal across all three datasets, and models must have valid results for all three to be included.
Key takeaways ➤ Model performance: OpenAI GPT-Realtime-2 (High) leads at 77.2%, followed by @xAI Grok Voice Think Fast 1.0 at 75.7%, GPT-Realtime-1.5 at 72.0%, and @GoogleAI Gemini 3.1 Flash Live Preview (High) at 69.5%. Conversational Dynamics and Agentic Performance are key differentiators of frontier models, with GPT-Realtime-2 leading in Conversational Dynamics, and Grok Voice Think Fast 1.0 leading in Agentic Performance. ➤ Speed: Deepslate Opal is the fastest model in the index with a TTFA of 0.44s, followed by GPT-Realtime-1.5 at 0.82s and Grok Voice Think Fast 1.0 at 1.25s. GPT-Realtime-2 (High) records 2.33s, with Gemini 3.1 Flash Live Preview (High) recording 2.98s. ➤ Cost: Gemini 3.1 Flash Live Preview (Minimal) is the lowest cost model in the index at $1.50, then Gemini 3.1 Flash Live Preview (High) at $1.75, Grok Voice Think Fast 1.0 at $3.00, GPT-Realtime-2 (High) at $4.14. ➤ Datasets incorporated: Big Bench Audio - 1,000 reasoning questions across Formal Fallacies, Navigate, Object Counting, and Web of Lies; Full Duplex Bench - pause handling, turn taking, interruption and backchannel handling; 𝜏-Voice - end-to-end customer service task completion across Airline, Retail, and Telecom situations.
As always, we will continue to iterate on these benchmarks and plan to add more models.
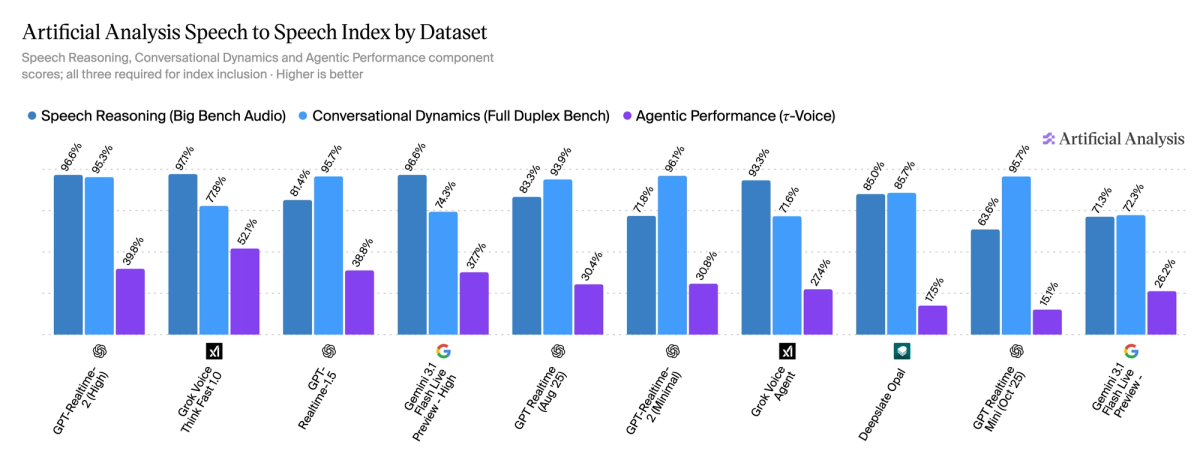
Conversational Dynamics and Agentic Performance are the key differentiators of frontier native audio models, with GPT-Realtime-2 leading in Conversational Dynamics and Grok Voice Think Fast 1.0 leading in Agentic Performance. GPT-Realtime-2 (Minimal) tops Conversational Dynamics (Full Duplex Bench) at 96.1%. Agentic Performance (𝜏-Voice) is the hardest dimension by a wide margin - Grok Voice Think Fast 1.0 leads at 52.1%, ahead of GPT-Realtime-2 (High) at 39.8%, with every model below 53%. Speech Reasoning (Big Bench Audio) is tightly clustered at the top, led by Grok Voice Think Fast 1.0 at 97.1%.
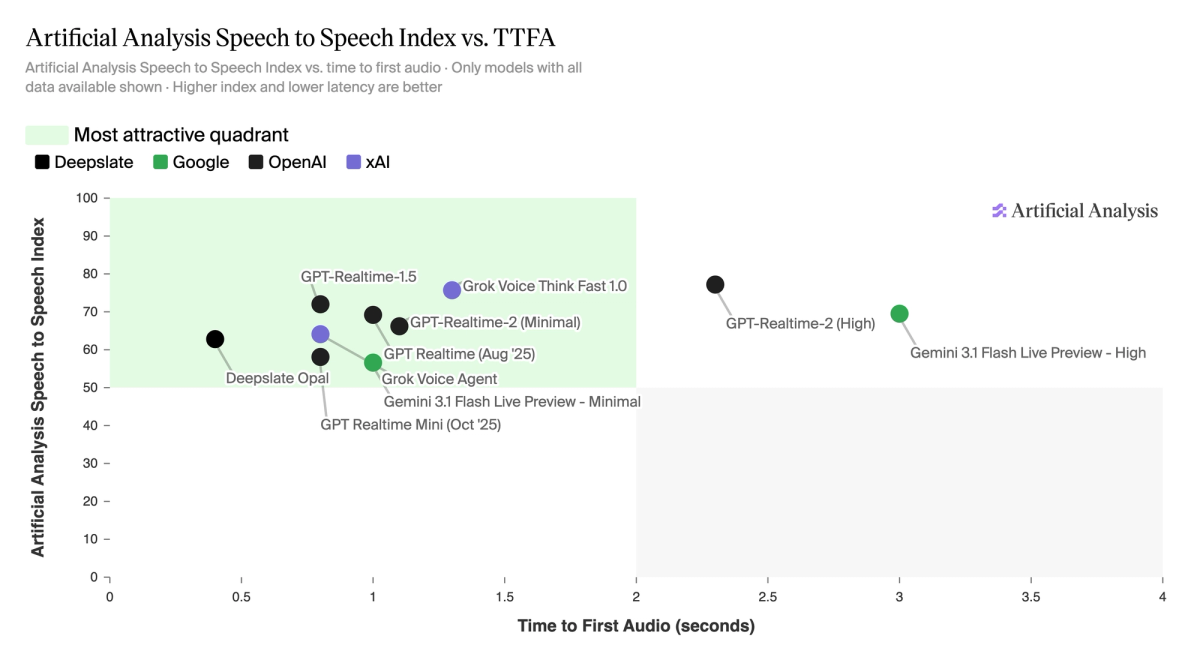
Deepslate Opal has the fastest average time to first audio (TTFA) in the index at 0.44s, scoring 62.1%. GPT-Realtime-1.5 records 0.82s at a 72.0% index score, and Grok Voice Think Fast 1.0 records 1.25s at 75.7%. GPT-Realtime-2 (High) records 2.33s at 77.2%, with Gemini 3.1 Flash Live Preview (High) recording 2.98s at 69.5%.
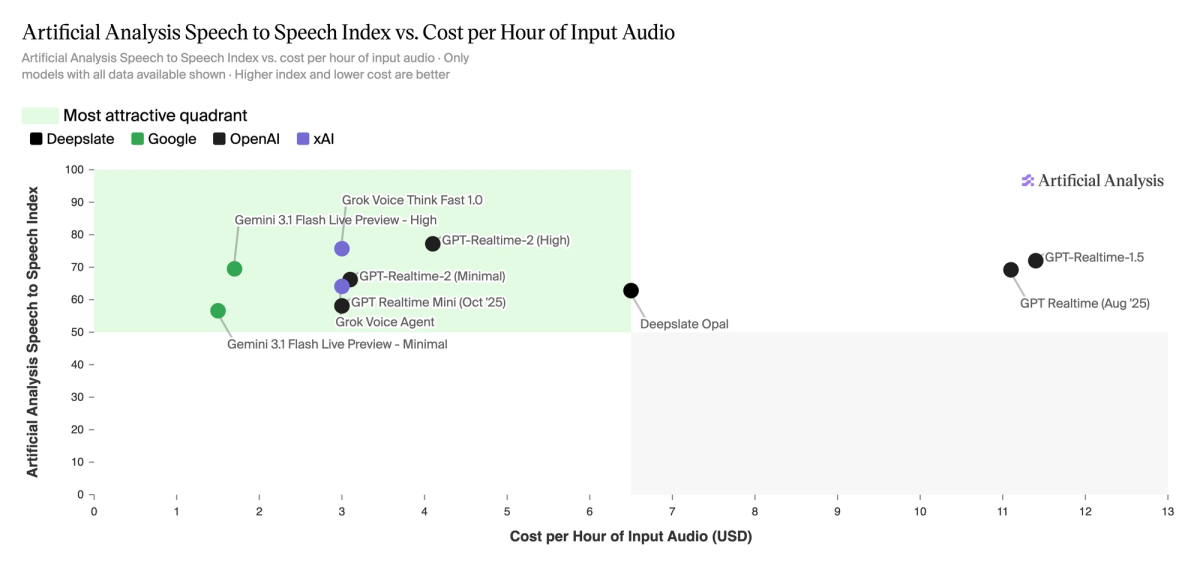
Gemini 3.1 Flash Live Preview (Minimal) has the lowest cost per hour of input audio in the index at $1.50, scoring 56.6%. Gemini 3.1 Flash Live Preview (High) costs $1.75 at 69.5%, Grok Voice Think Fast 1.0 costs $3.00 at 75.7%, and GPT-Realtime-2 (High) costs $4.14 at 77.2%.
Full breakdown: https://artificialanalysis.ai/speech-to-speech
Methodology: https://artificialanalysis.ai/methodology/speech-to-speech-benchmarking
Read the latest
First AA-AgentPerf results for NVIDIA Vera Rubin NVL72
NVIDIA Vera Rubin NVL72 serves up to ~5.7x the total throughput per megawatt of GB300 NVL72 on AA-AgentPerf, with first results on DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
October 15, 2026
First AA-AgentPerf-Local results for an NVIDIA RTX Spark N1X laptop
An NVIDIA RTX Spark N1X laptop completes our local agent workload on Qwen3.8 27B in 18.7 minutes.
October 15, 2026
NVIDIA Releases Nemotron 3.5 Super VL and Nemotron 3.5 Bolt 74B A9B
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
October 15, 2026