June 30, 2026
Claude Sonnet 5: strong agentic performance at a higher cost per task
See model pageClaude Sonnet 5 achieves 53 on the Artificial Analysis Intelligence Index, but without promotional pricing will cost more per task than Opus 4.8
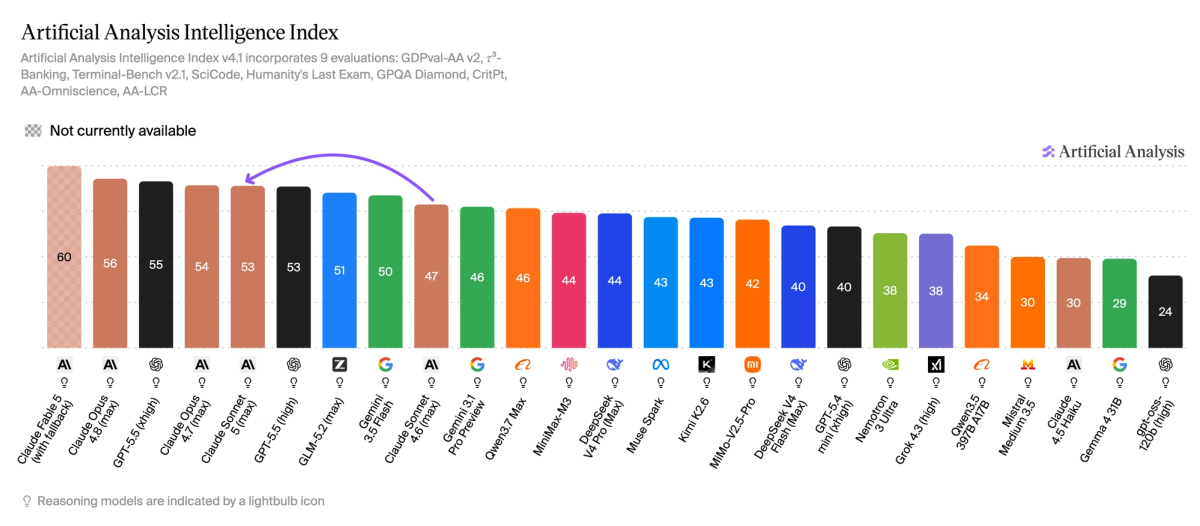
We supported Anthropic to evaluate Claude Sonnet 5 ahead of release: with max effort it improves 6 points over Sonnet 4.6 to achieve the same Intelligence Index as GPT-5.5 with high reasoning, but remains behind Opus 4.7 and 4.8
Key takeaways:
➤ Claude Sonnet 5 is the #5 model on the Artificial Analysis Intelligence Index, only 2-3 points behind GPT-5.5 (xhigh) and Opus 4.8 (max)
➤ With max effort, Sonnet 5 works harder than previous Anthropic models: it used ~40% more output tokens per Intelligence Index task than Sonnet 4.6, and ~3x the agentic turns for our knowledge work evaluations AA-Briefcase and GDPval-AA. This behavior scales well with the ‘effort’ setting, with the max effort using around 6x more turns than low effort on GDPval-AA
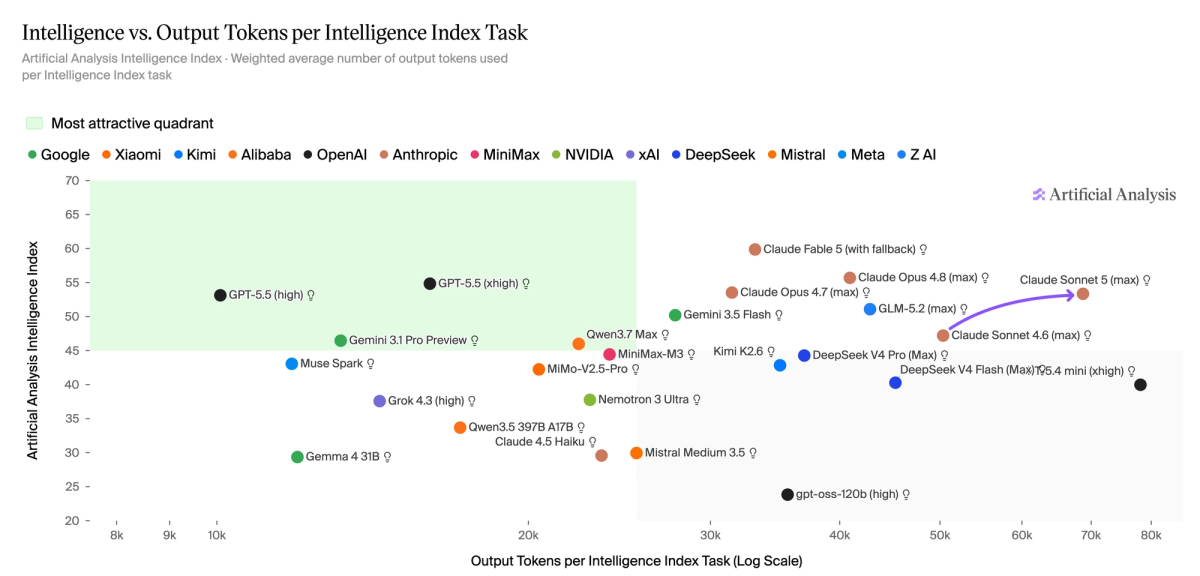
➤ Claude Sonnet 5 costs more per task than Opus 4.8 before accounting for promotional pricing: Claude Sonnet 5 costs $2.29 per task on the Intelligence Index, a ~2x increase compared to Sonnet 4.6 and ~15% more than Claude Opus 4.8. This is driven entirely by increased token usage. Sonnet 5 retains the same $3/$15 per 1M input/output token pricing as Sonnet 4.6 (compared to $5/$25 for Opus 4.8), however Anthropic is offering a one-third reduction to $2/$10 until September 1. Our results use standard $3/$15 pricing
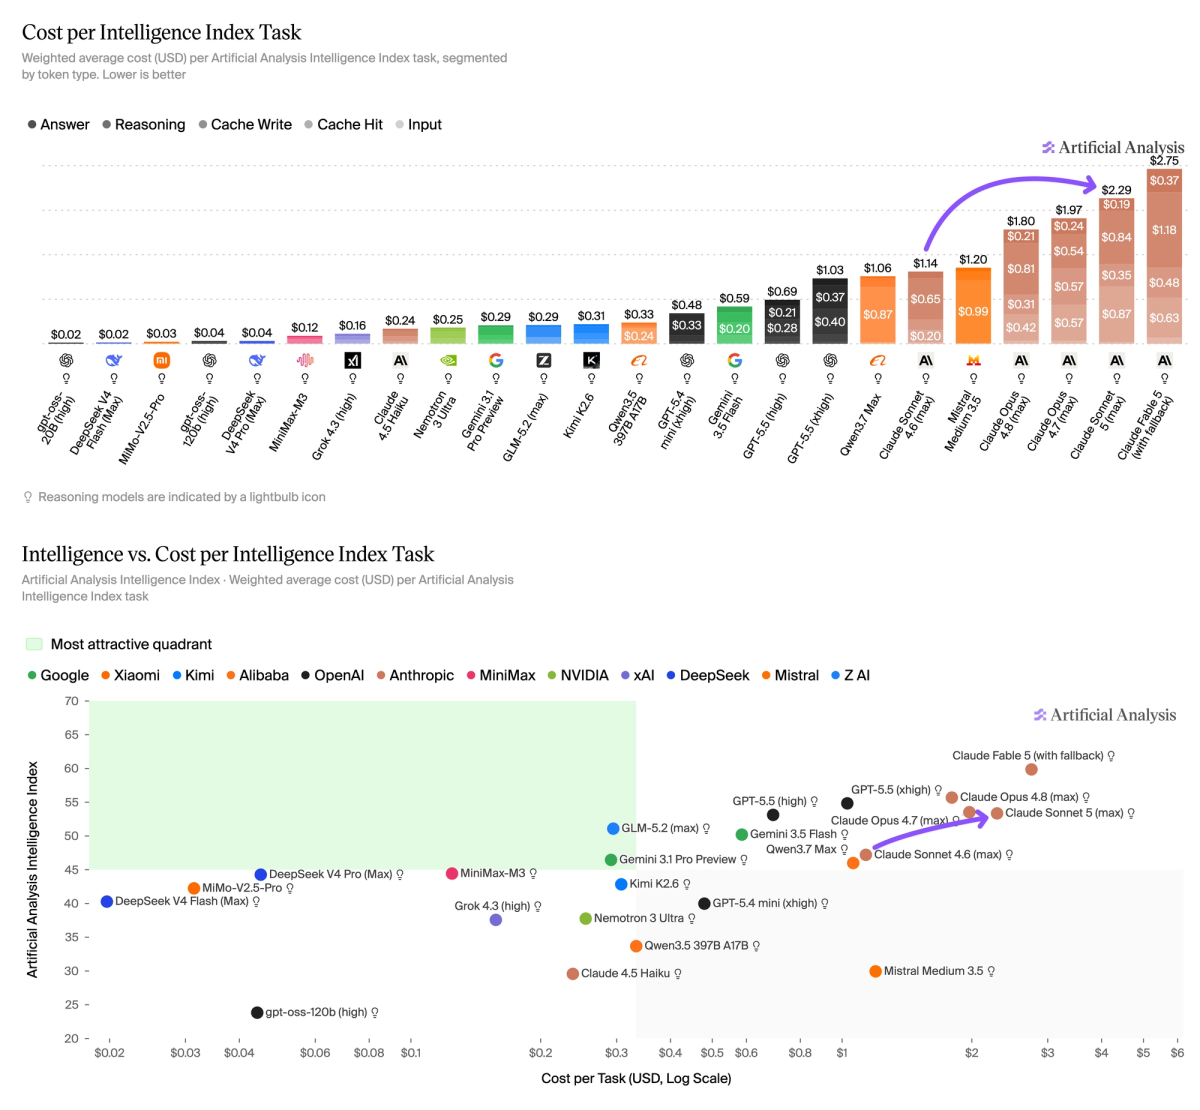
➤ Sonnet 5 matches or outperforms Opus 4.8 on agentic knowledge work tasks: on both AA-Briefcase and GDPval-AA, Claude Sonnet 5 sits just ahead of Opus 4.8, trailing only Claude Fable 5 (which is not currently generally available). These benchmarks test the ability of models to produce accurate and well-presented professional outputs using our open source reference agent harness, Stirrup
➤ For reasoning and knowledge-heavy tasks, Sonnet still sits behind its larger siblings: despite substantial gains across many evaluations, heavy reasoning and knowledge benchmarks still show Opus 4.8 ahead of Sonnet 5. On CritPt, a frontier physics reasoning benchmark developed by researchers at Argonne and UIUC, Sonnet 5 scores 17% - this is 14 points higher than its predecessor, but behind GLM-5.2, Claude Opus and Fable, and GPT-5.5 (xhigh and Pro)
➤ Sonnet 5 also showed significant improvements over Sonnet 4.6 on Terminal-Bench v2.1 (+9 points), Humanity’s Last Exam (+10 points), and SciCode (+7 points), with relatively flat scores elsewhere
Other key model details:
➤ Context window of 1 million tokens (equivalent to Sonnet 4.6)
➤ Pricing of $3/$15 per 1M tokens of input/output (reduced to $2/$10 until September 1); cache pricing remains at a 25% premium for cache writes ($3.75 per million tokens) with 5-minute time to live, and 90% discount for cache hits ($0.3 per million tokens)
➤ Effort remains the recommended way of configuring model performance and latency. Sonnet 5 adds an additional ‘xhigh’ effort setting relative to Sonnet 4.6, matching the 5 effort levels available on Opus 4.8 (max, xhigh, high, medium, low)
Compare Claude Sonnet 5 with other leading models at: https://artificialanalysis.ai/models/claude-sonnet-5
Read the latest
First AA-AgentPerf results for NVIDIA Vera Rubin NVL72
NVIDIA Vera Rubin NVL72 serves up to ~5.7x the total throughput per megawatt of GB300 NVL72 on AA-AgentPerf, with first results on DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
October 15, 2026
First AA-AgentPerf-Local results for an NVIDIA RTX Spark N1X laptop
An NVIDIA RTX Spark N1X laptop completes our local agent workload on Qwen3.8 27B in 18.7 minutes.
October 15, 2026
NVIDIA Releases Nemotron 3.5 Super VL and Nemotron 3.5 Bolt 74B A9B
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
October 15, 2026