MicroEvals
Public evaluations
Showing 6421-6440 of 7017



001



A single-turn comparison of Claude Opus 4.8, GPT-5.6 Luna, GPT-5.6 Sol, Gemini 3.1 Pro Preview, and Gemini 3.6 Flash across practical assistant capabilities: tool honesty, quantitative reasoning, scheduling, Bayesian inference, evidence synthesis, coding, infrastructure design, constrained writing, ambiguity handling, optimization, policy interpretation, and multilingual grounding. Prompt 1 is a web-access diagnostic and should be scored separately. Prompts 2–12 are self-contained and should not require browsing. The comparison evaluates each model at the reasoning setting shown by Artificial Analysis, so results represent best-configured endpoint quality rather than equalized compute, latency, or cost.


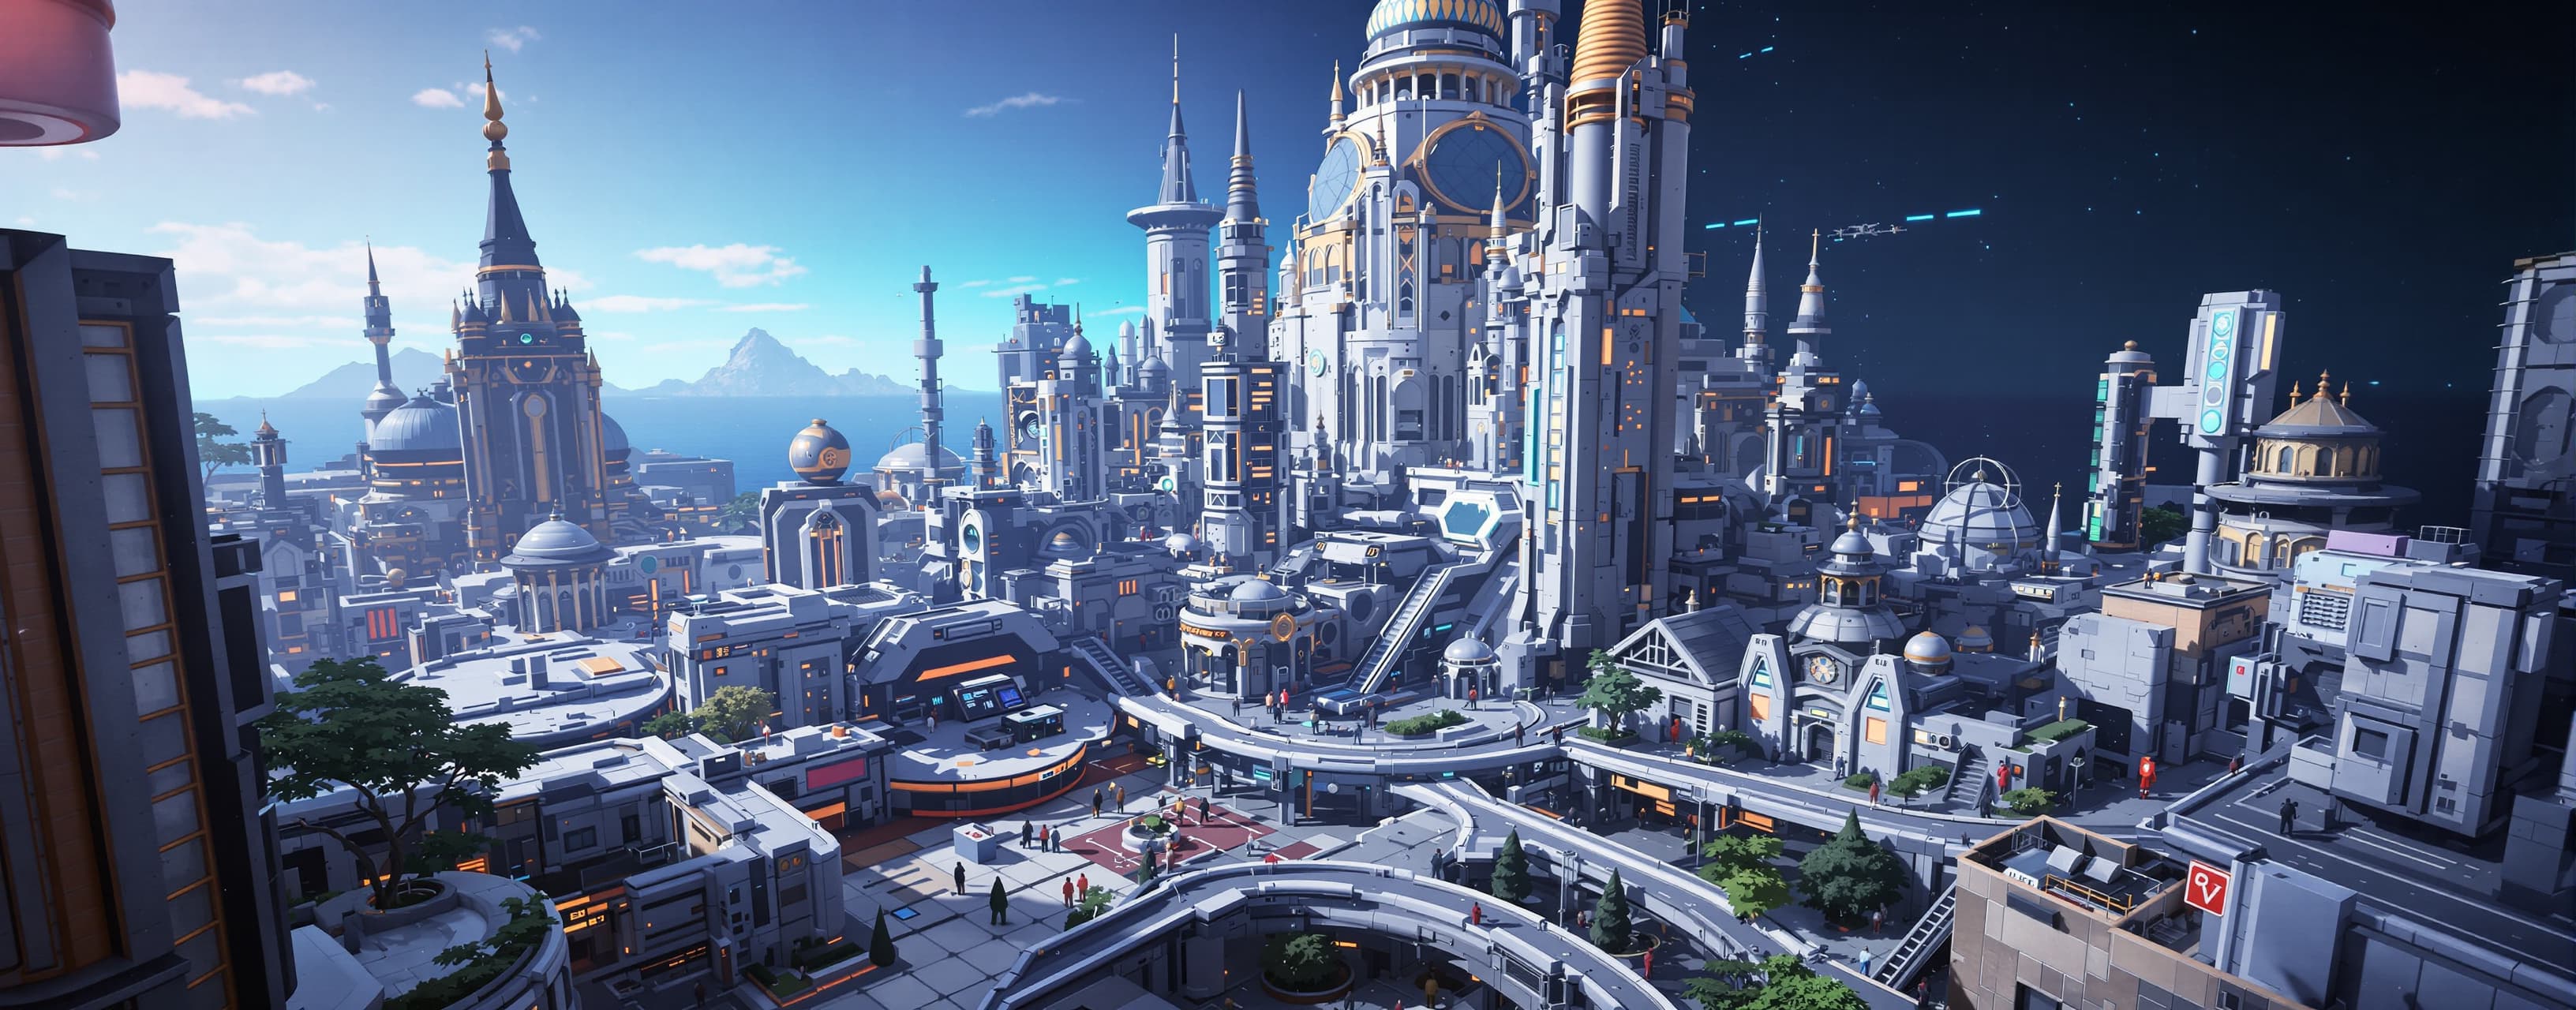
A benchmark comparing three frontier AI coding models by having them independently build the same highly detailed, interactive 3D HTML web experience. Models are evaluated on visual quality, interactivity, performance, responsiveness, code quality, optimization, and overall polish.

Redmi note 10 5G

da j

workout plan