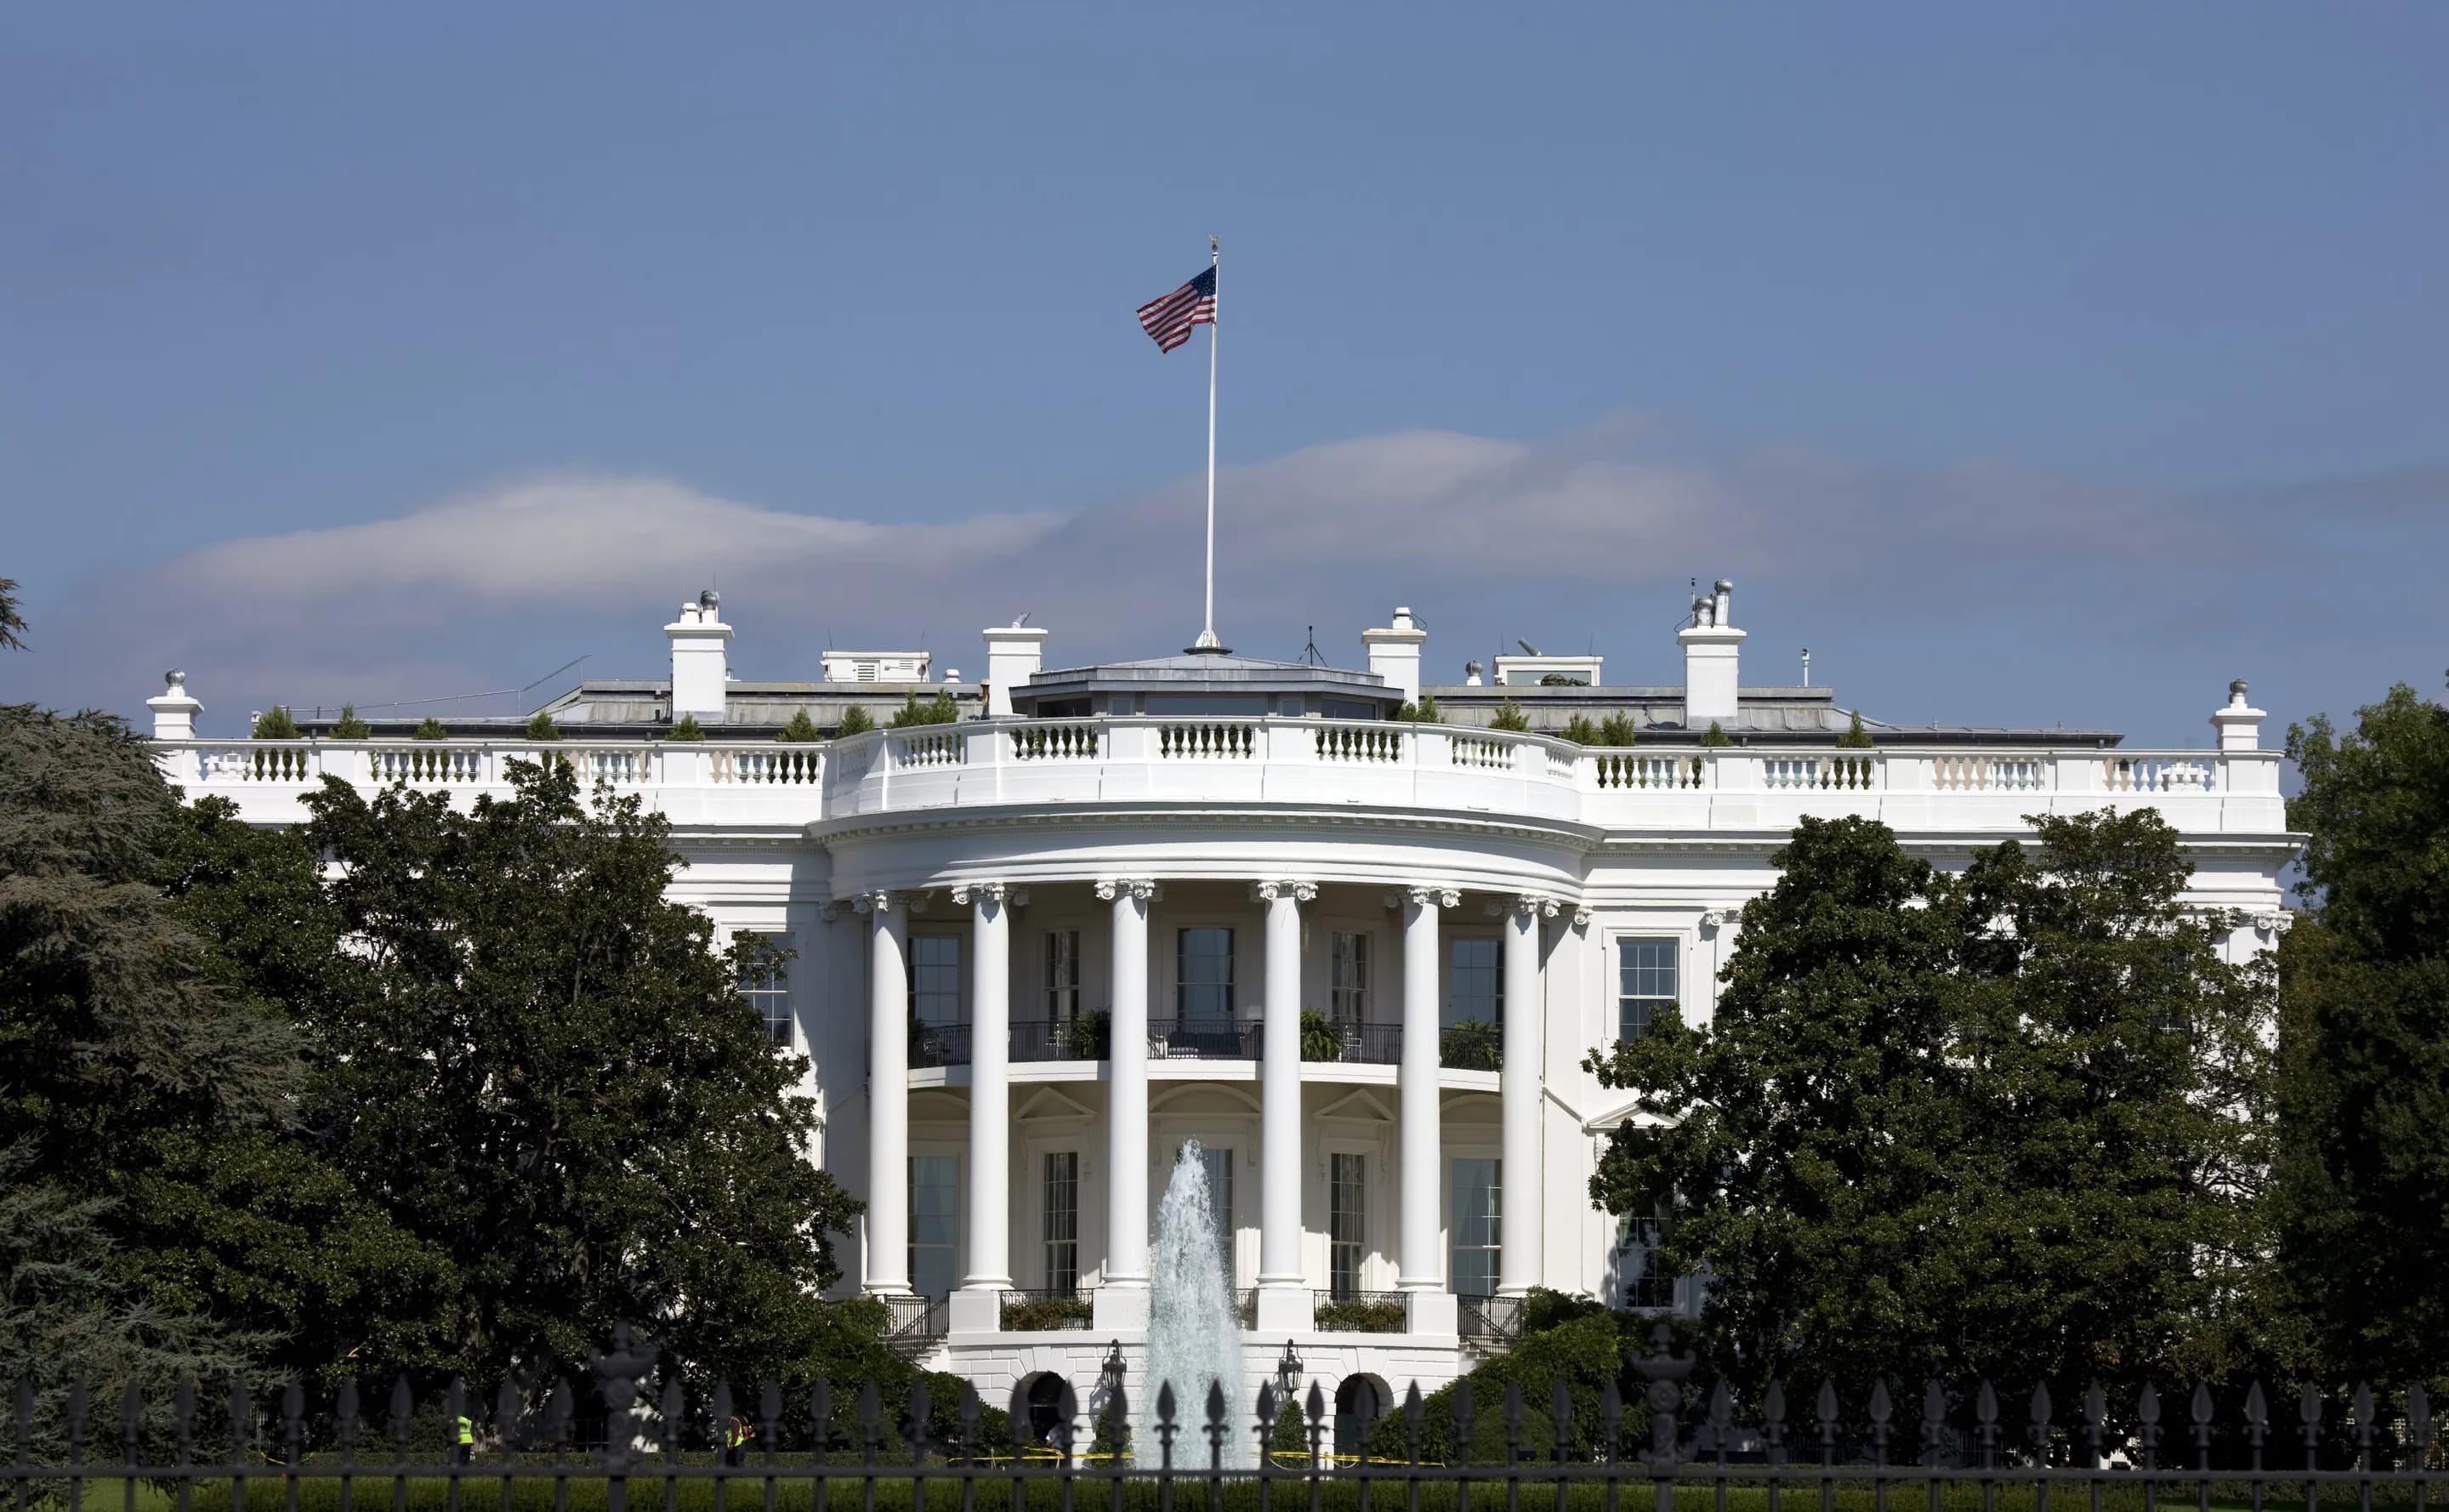
Benchmarking
for Government
Artificial Analysis is the leading independent benchmarking company across AI agents, models, inference and hardware. We measure risk, safety, cybersecurity, capability, cost, and performance to help the public sector make decisions on AI.
How we support government
Artificial Analysis provides benchmarking, advisory, and data to help public sector clients design AI policy and select AI technologies.
Design AI policy and support decision-making
AI progress has critical policy and regulatory implications for governments, administrations and the public sector:
- Which models are safe, and how can we secure critical systems and infrastructure?
- What effect will AI knowledge work have on jobs and the economy?
- How can governments balance national priorities including innovation, competition, national security, and data center construction?
As the leading independent benchmarking company, we bring deep expertise to inform these urgent questions.
Select AI technologies
AI capability and cost are both rapidly increasing. We support the public sector in understanding, measuring, and selecting AI technologies:
- How to responsibly deploy the most capable models at the lowest cost?
- How to empower workers with effective agents?
- Which public sector use cases will AI solve in the next year?
Our benchmarking services, data, and expertise can support public sector clients to safely maximize AI performance at the lowest cost.
Publicly referenced by the leading AI labs, publications, and institutions


Our topic expertise
Cybersecurity and safety
We can support federal, state and local governments, as well as industry clients, to audit models across:
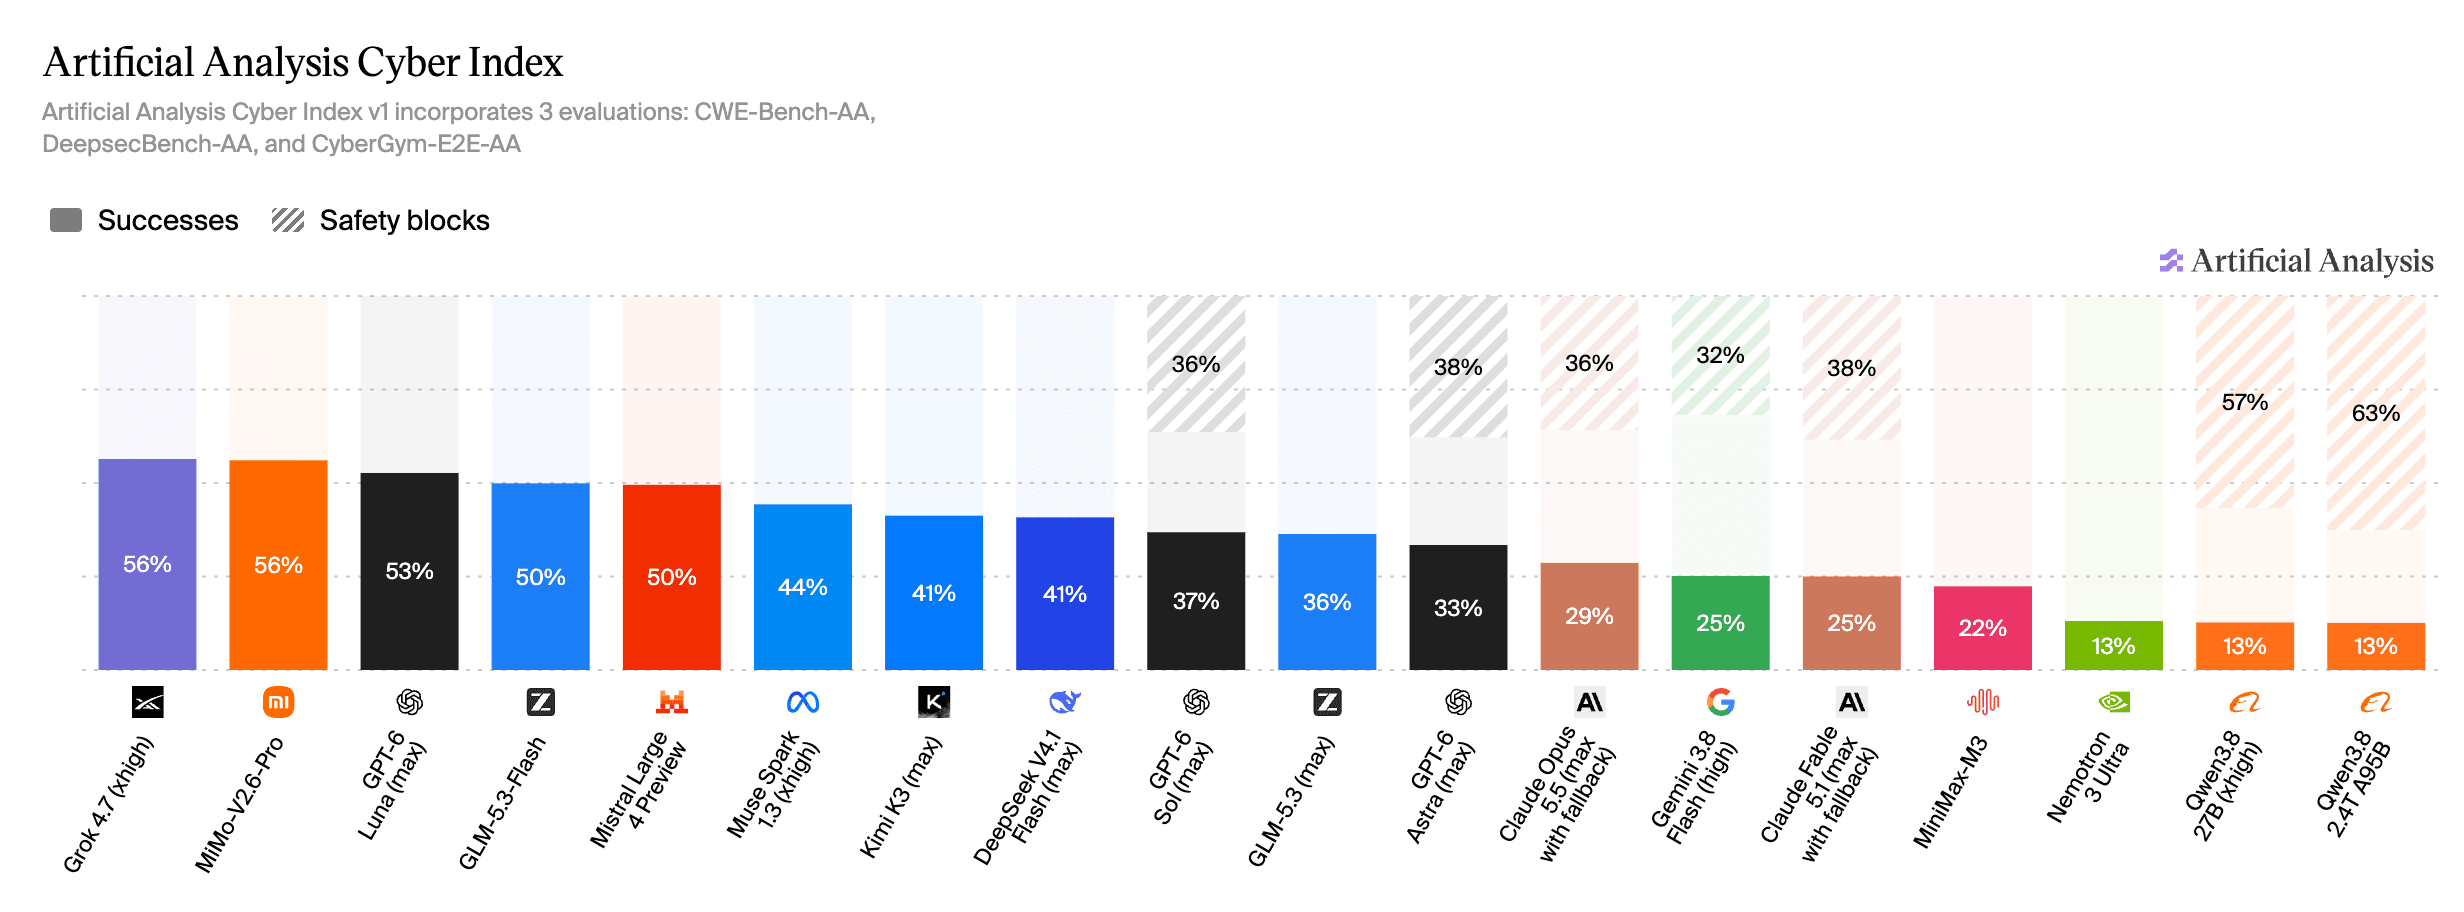
- Cybersecurity – we use cybersecurity benchmarks to measure the defensive cybersecurity capability of models, including vulnerability identification, remediation, and incident response across white-box, gray-box and black-box target surfaces.
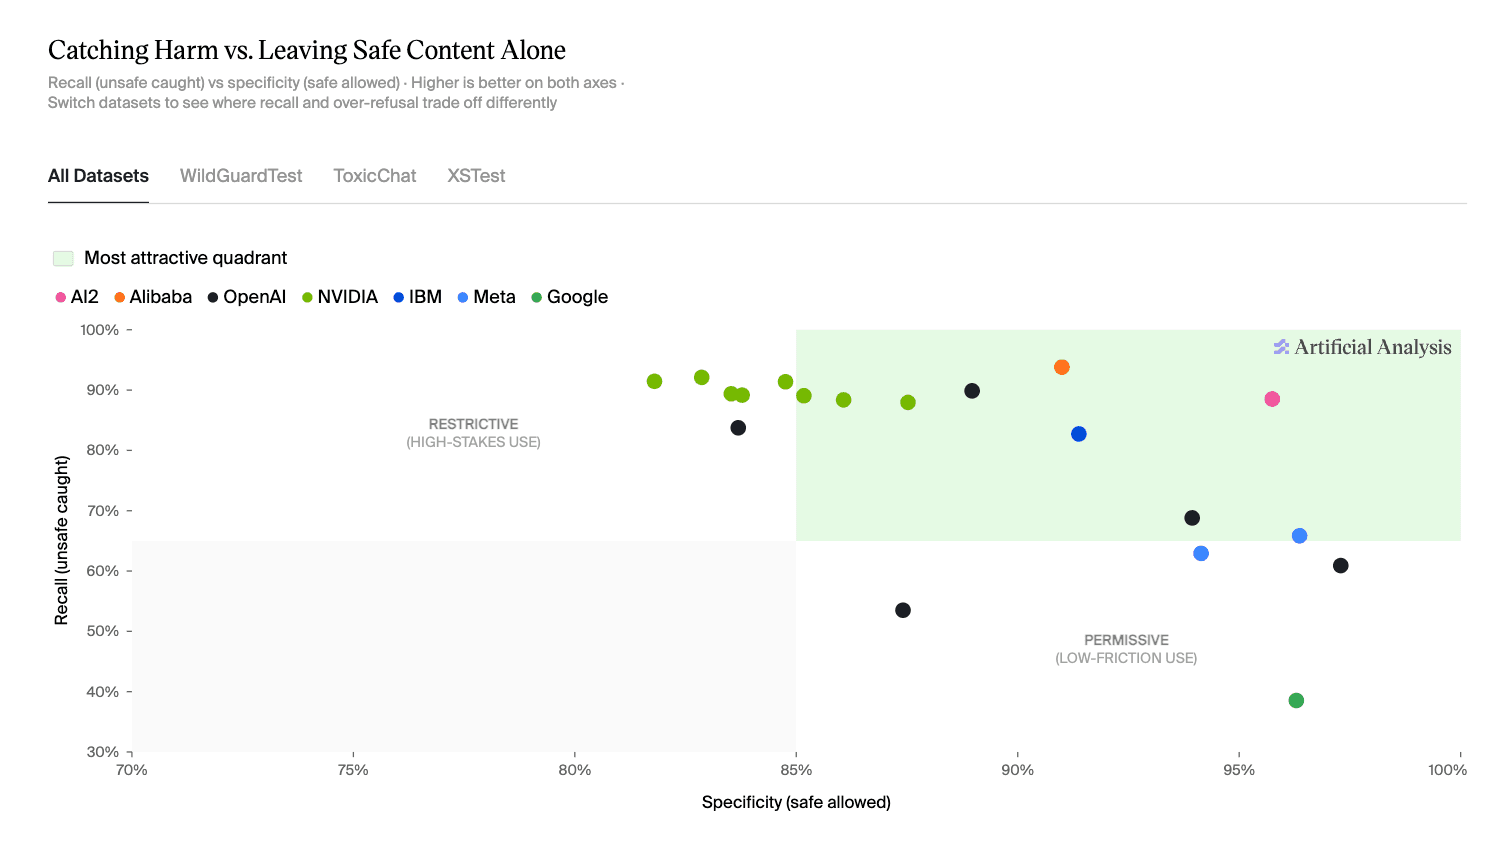
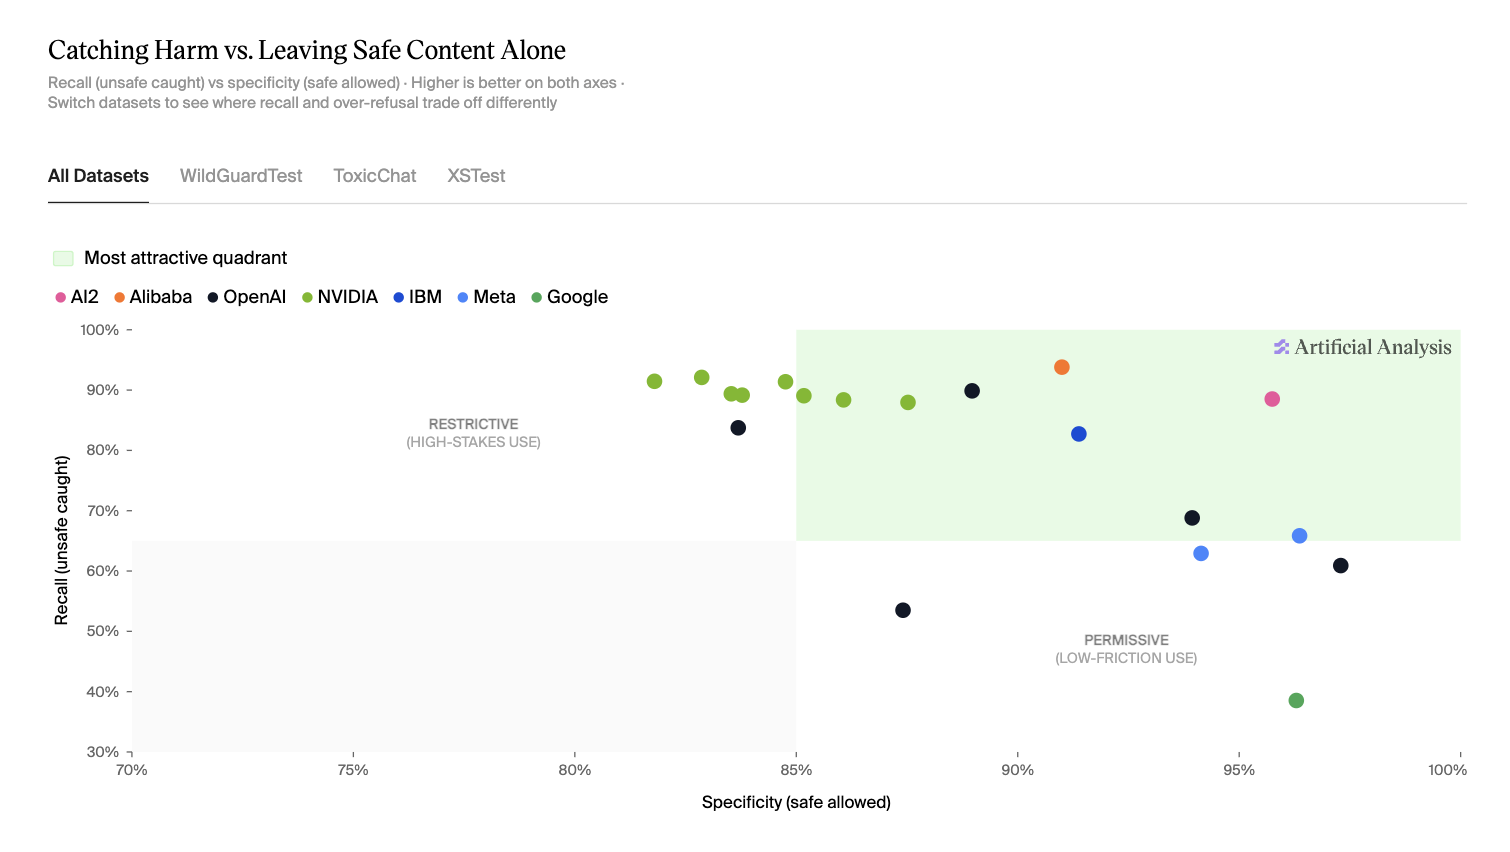
- Safety – we evaluate models across a broad spectrum of harms (e.g. CBRNE, violence, privacy) and across escalating levels of adversarial pressure, from direct requests to sophisticated elicitation, to measure both capability and trustworthiness.
Case study
Artificial Analysis Cyber Index Alliance
The Artificial Analysis Cyber Index Alliance brings together industry partners to set a new standard for evaluating how AI models perform on enterprise cyber defense tasks. The Alliance launches alongside the Artificial Analysis Cyber Index, which combines three partner-contributed and open benchmarks to evaluate how well agents find and fix vulnerabilities.
 NVIDIA
 IBM
 Vercel
 Collinear AI
Intelligence
Capability, cost and performance
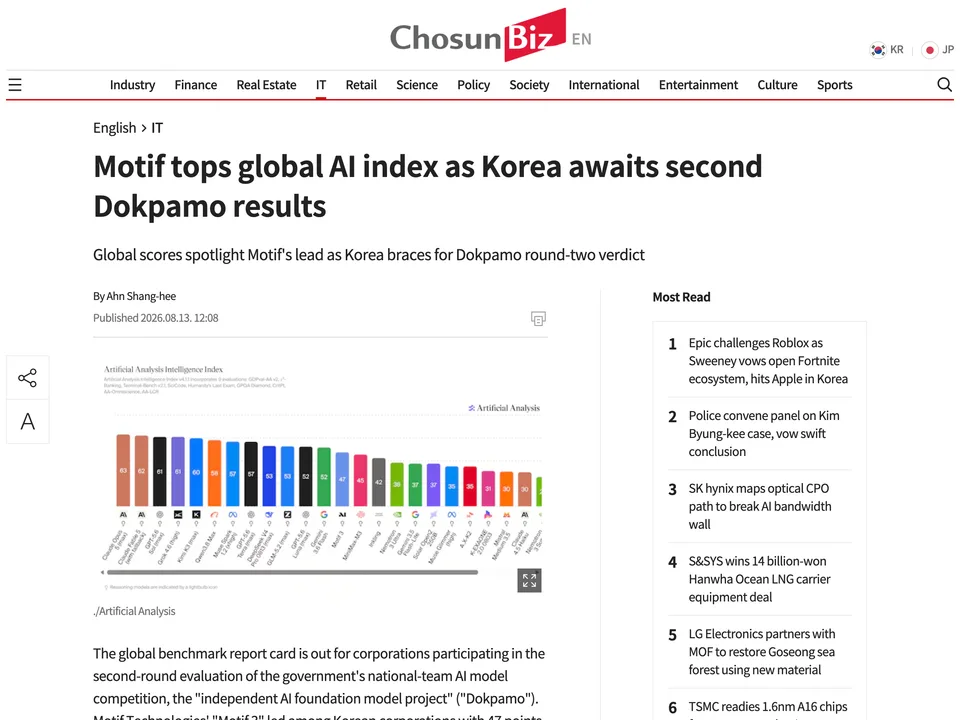
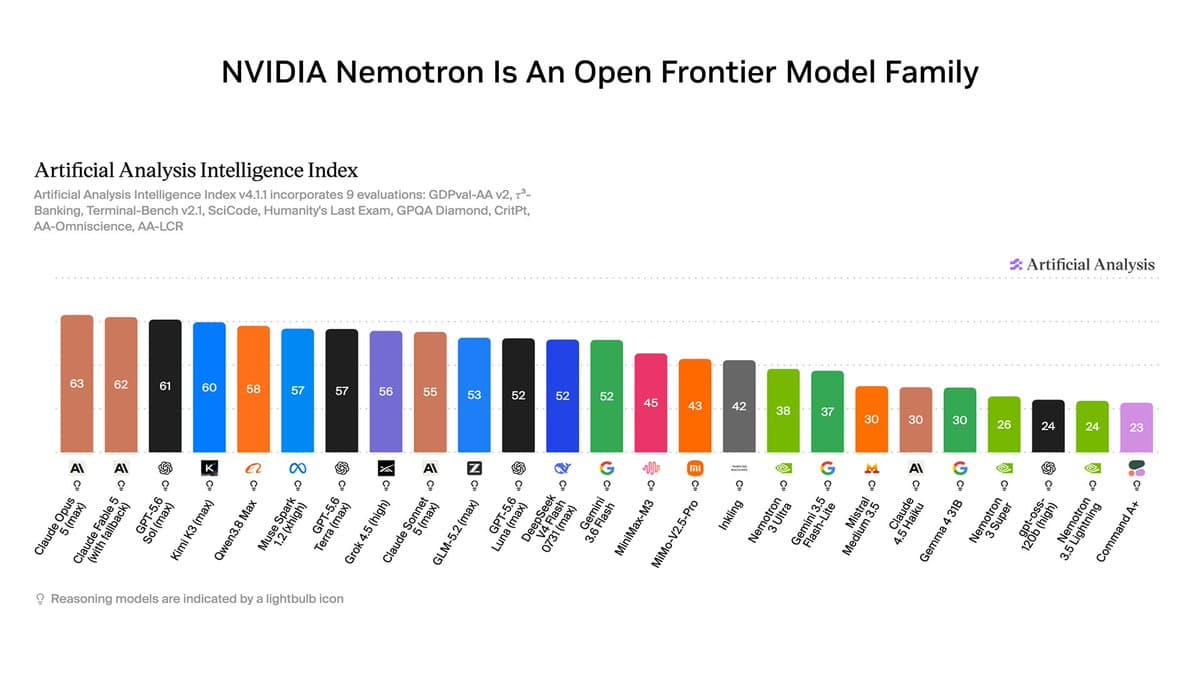
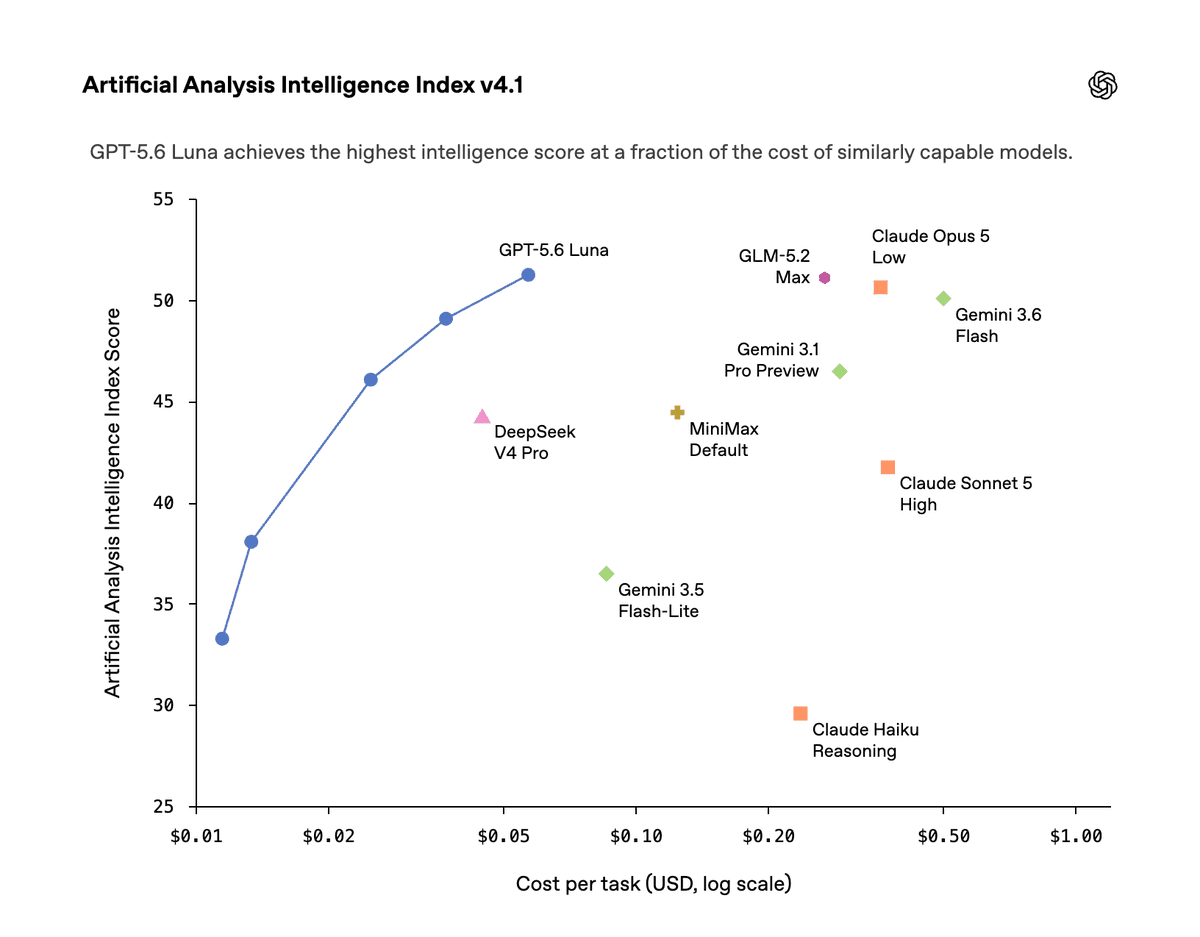
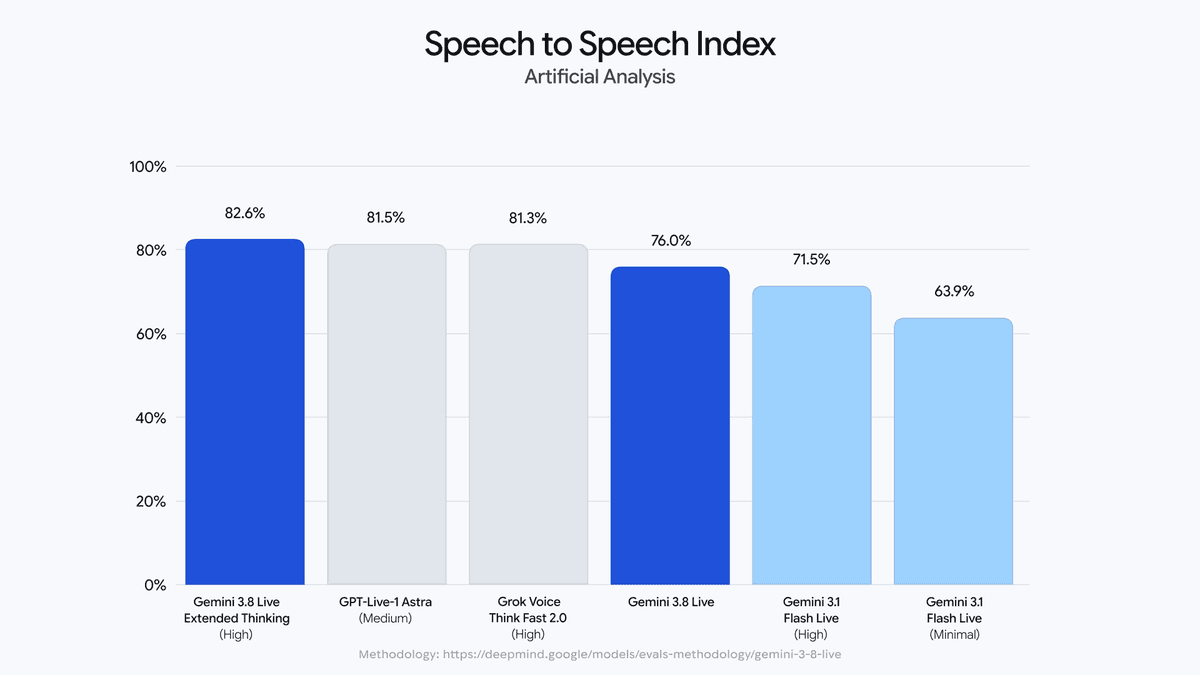
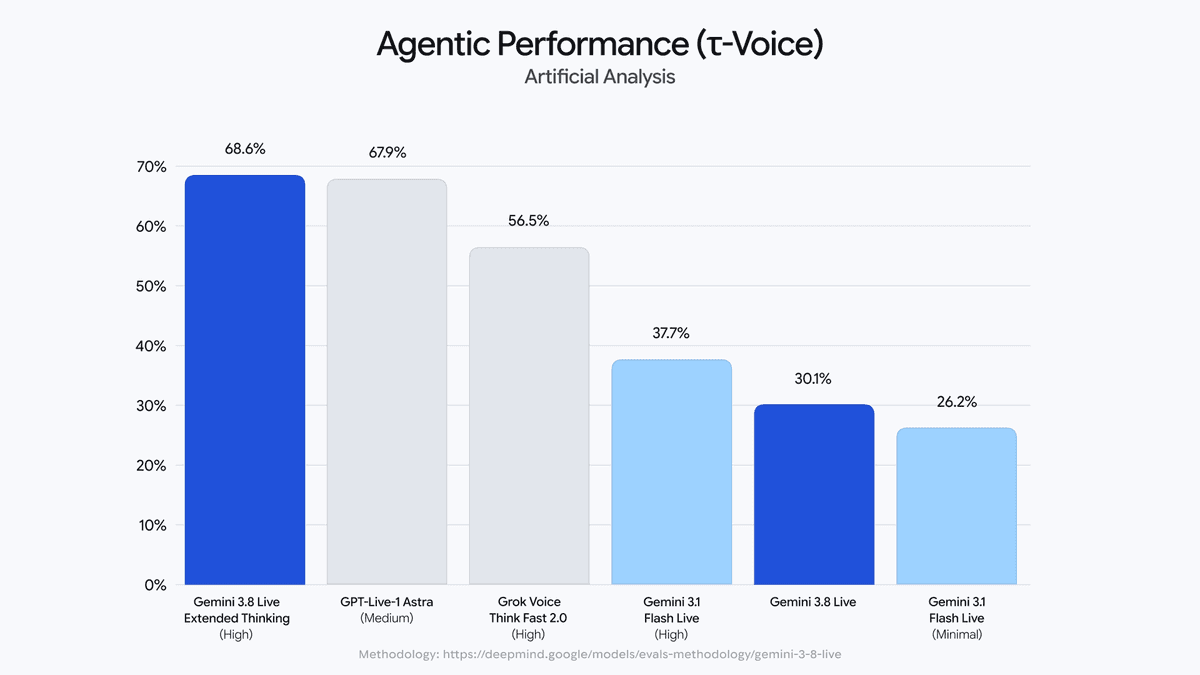
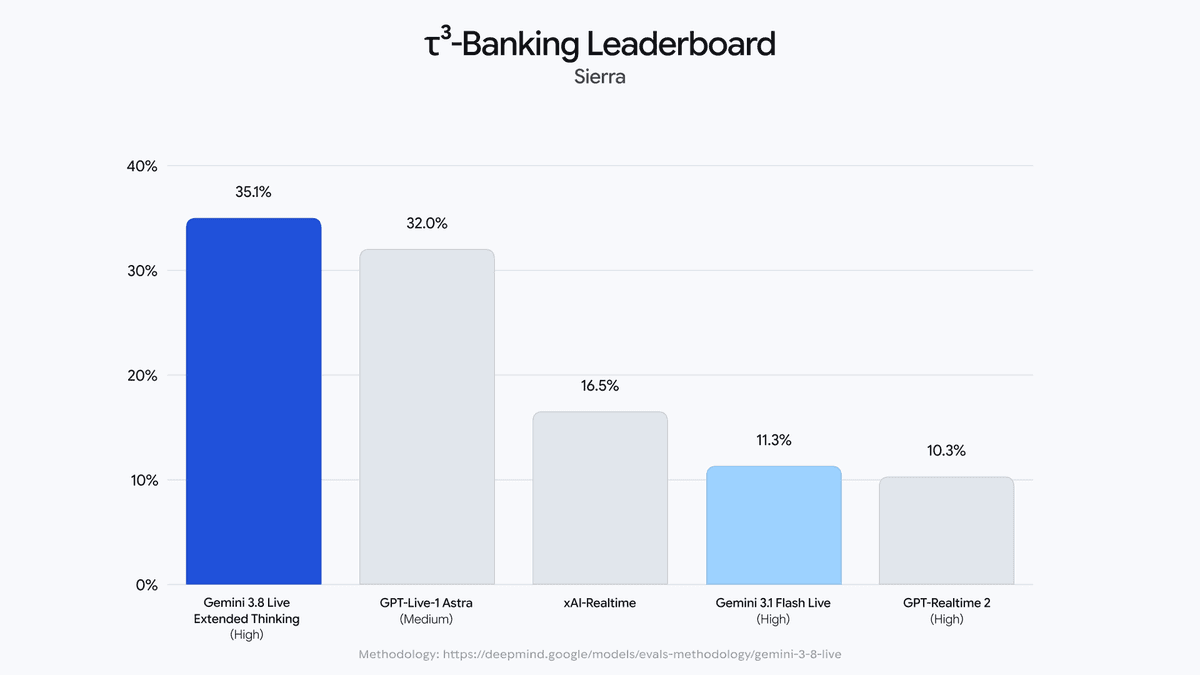
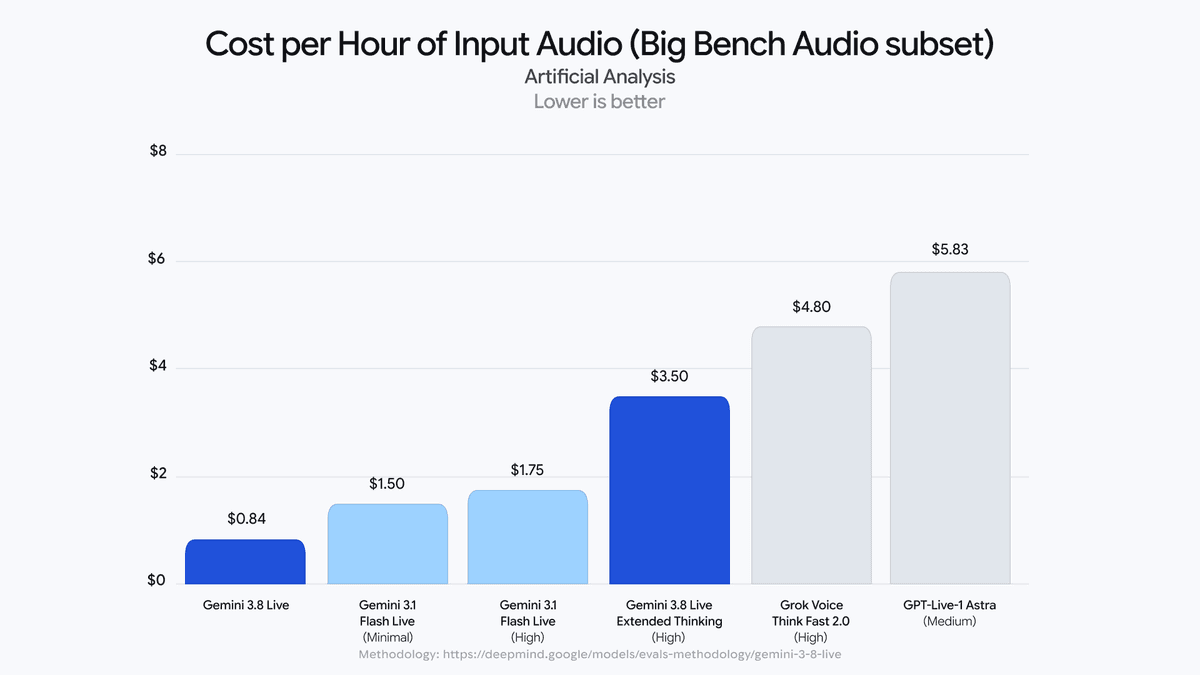
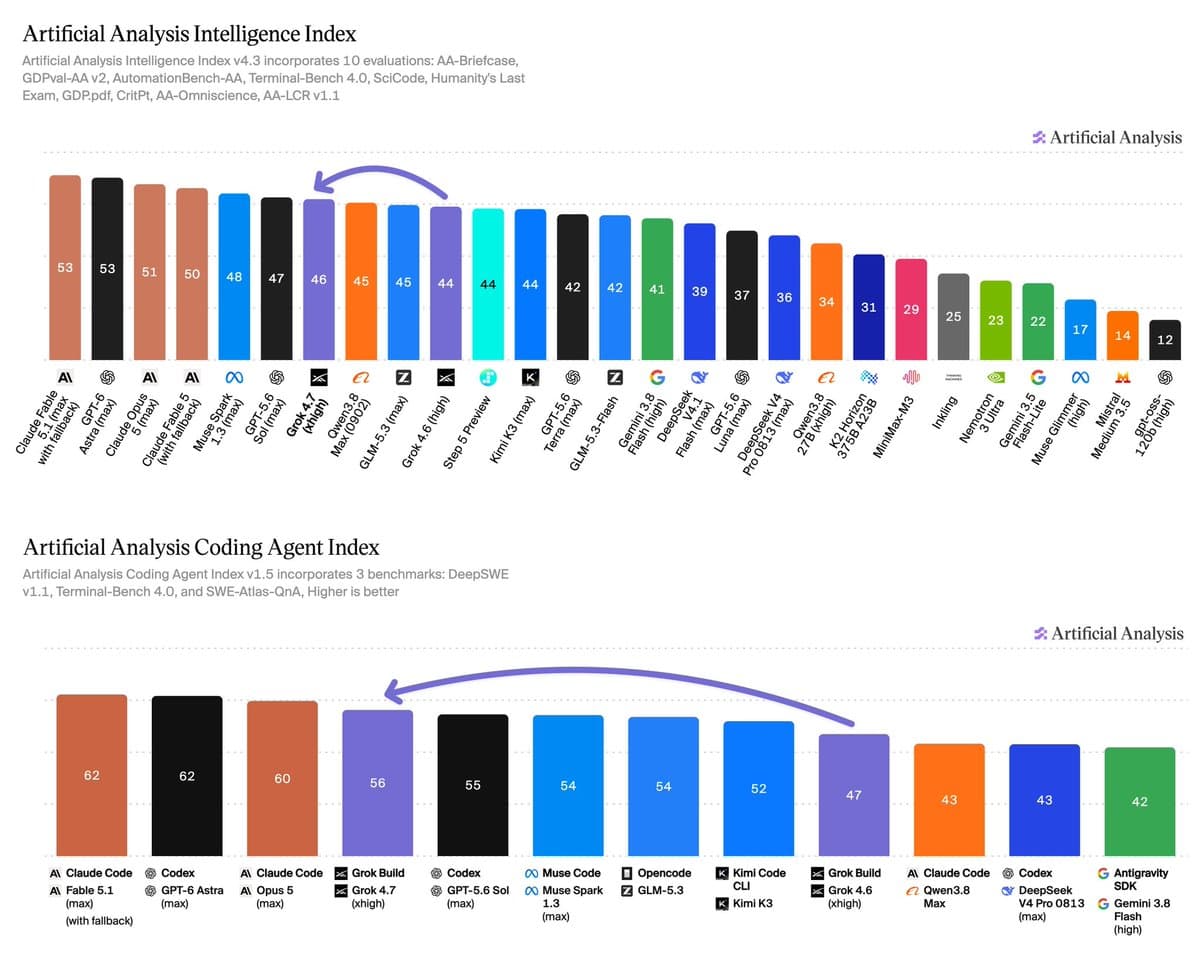
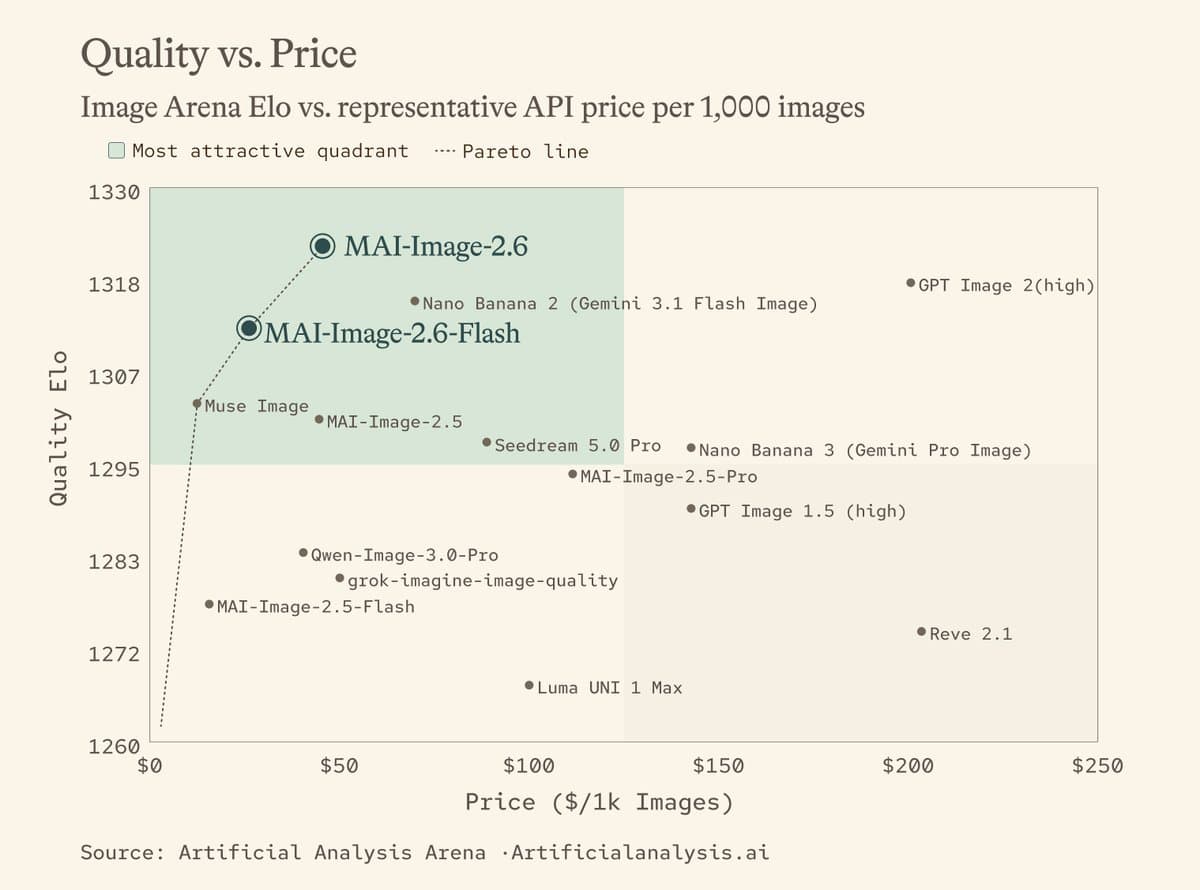
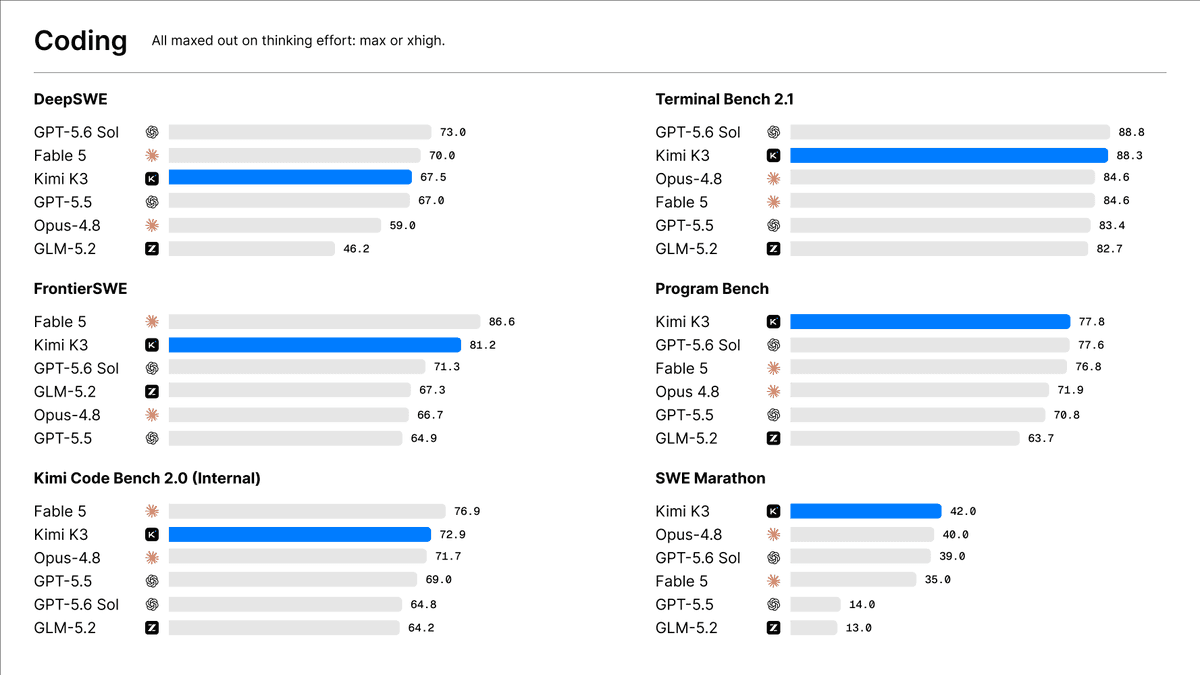
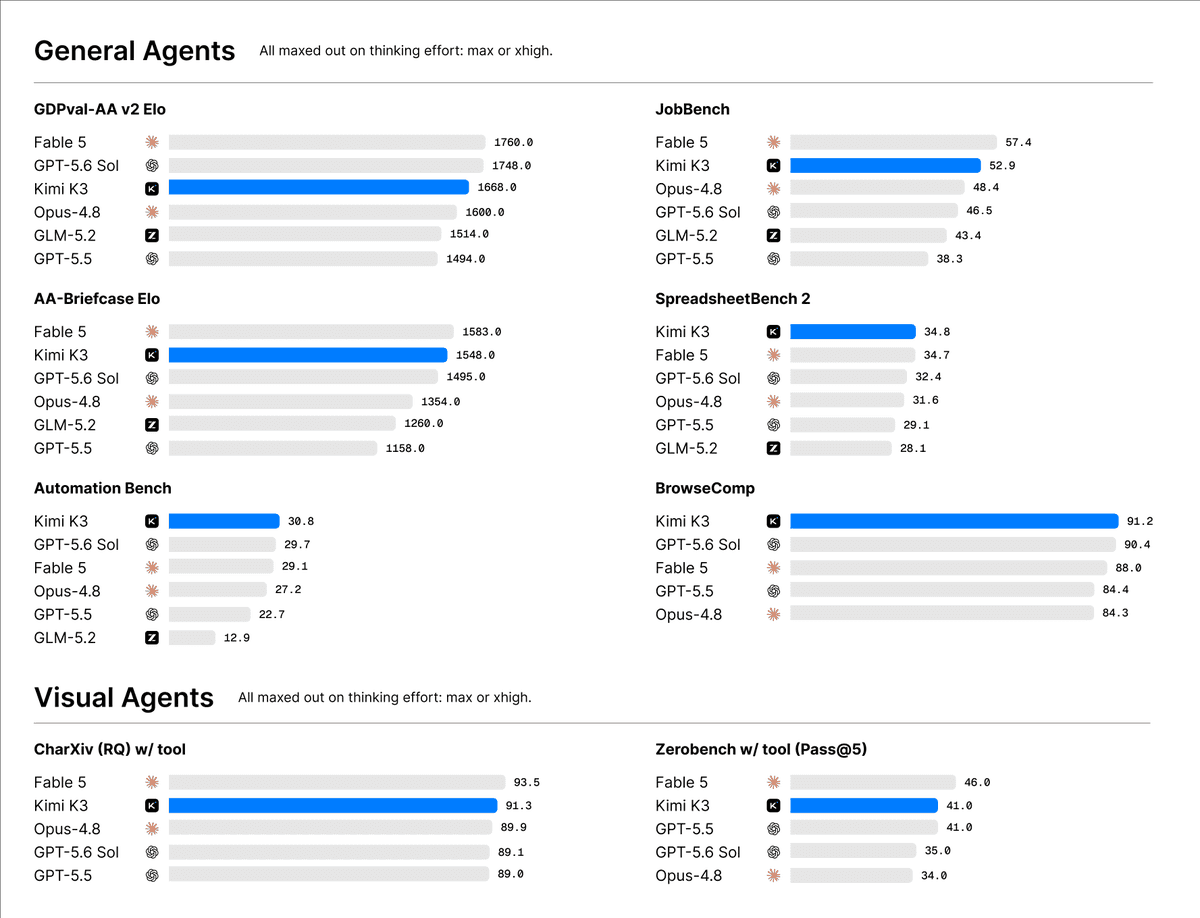
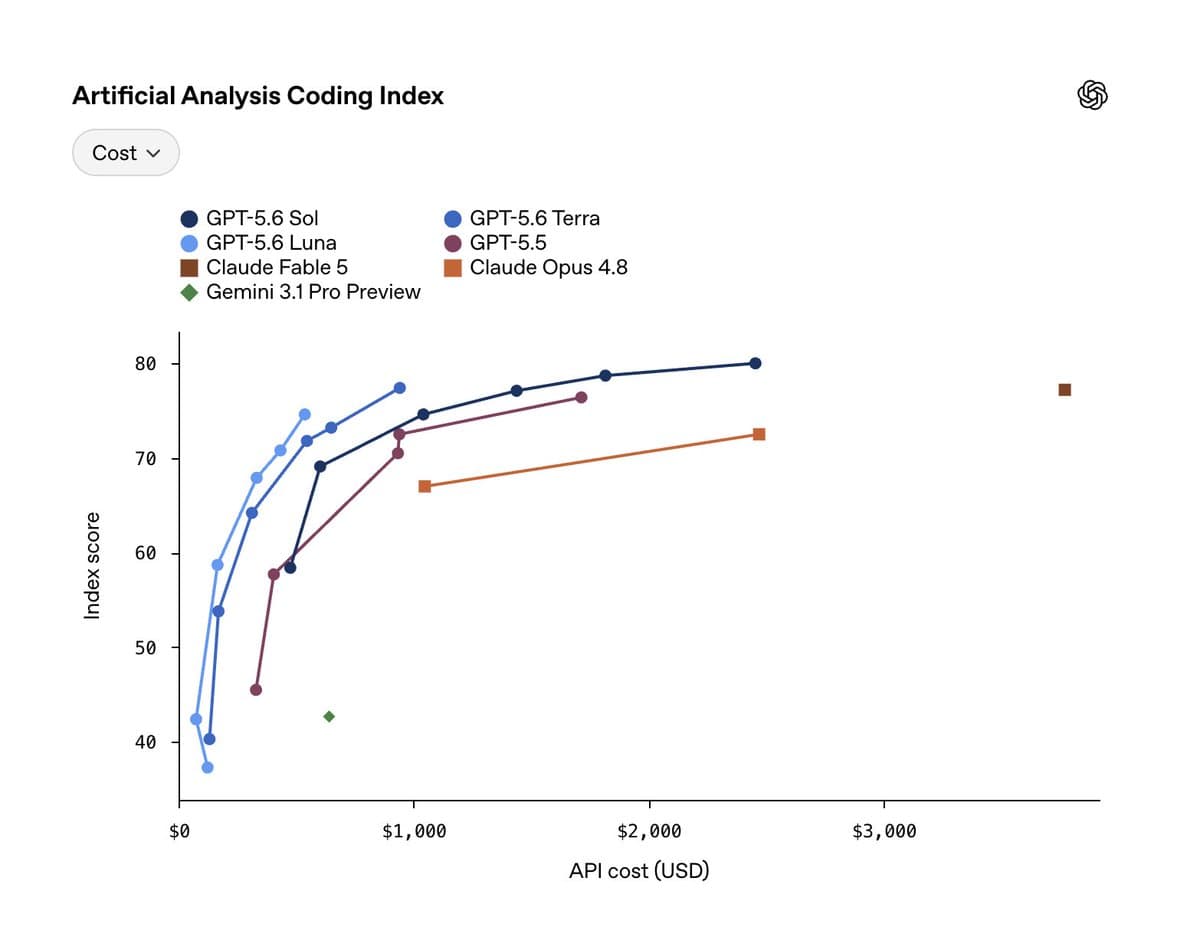
Artificial Analysis defines the global standard in measuring capabilities, accuracy, hallucination, cost, speed and latency of models and agents. We are widely referenced in frontier model launches such as Claude Opus 5.5 and GPT-5.6.
For the public sector, we provide an independent view of what tasks models can complete, how much this costs, and how long it takes. This is critical to inform policy design questions (e.g. how AI will affect jobs) and inform technology selection (e.g. which model to choose for a use case).
Case study
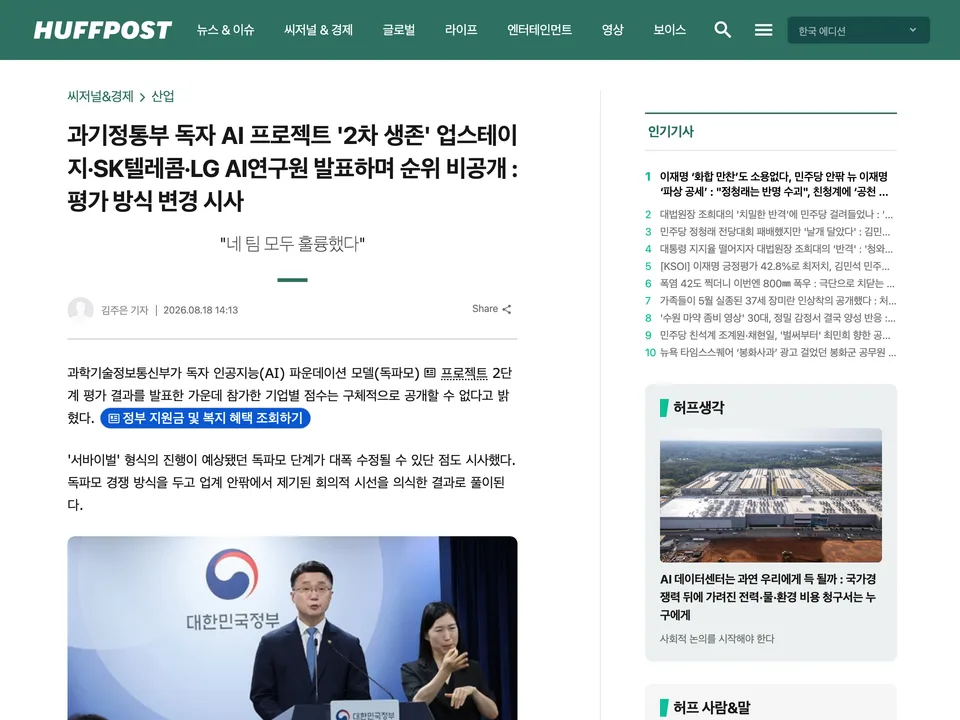
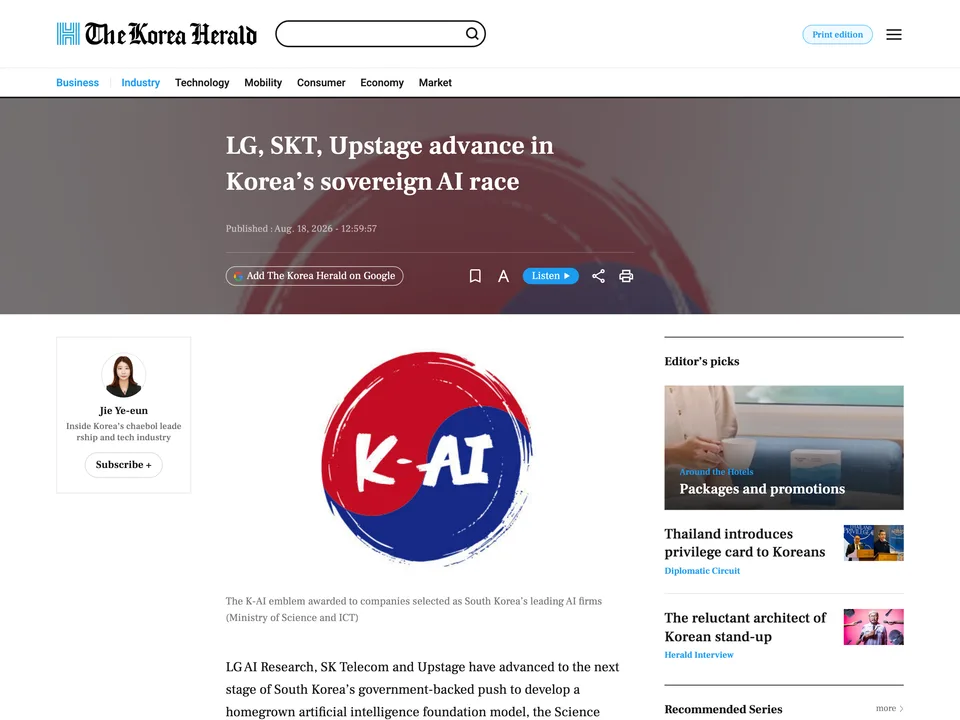
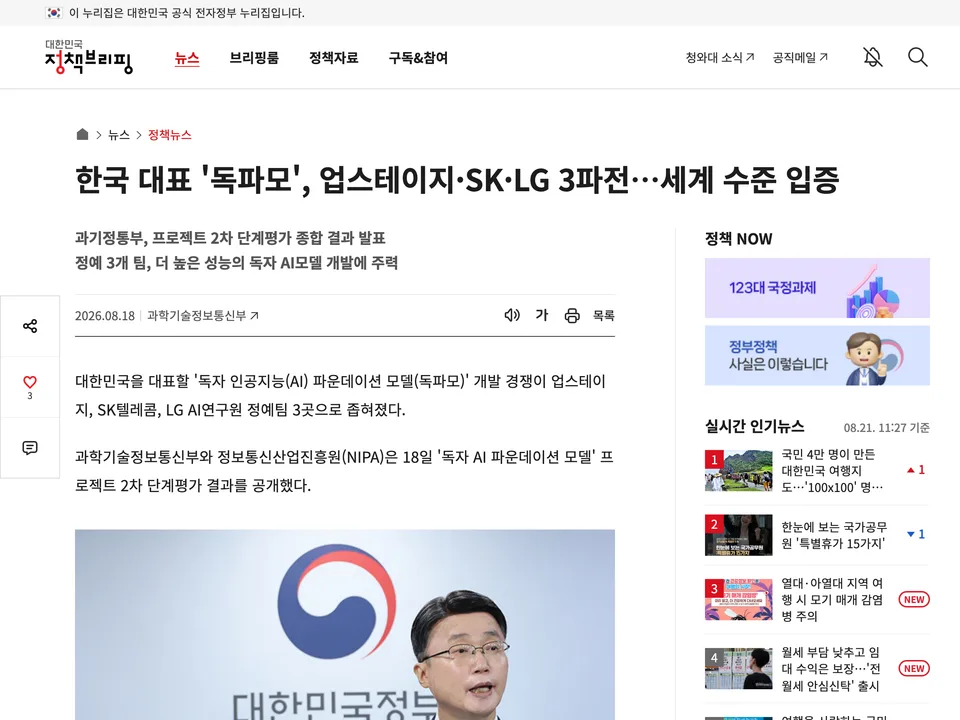
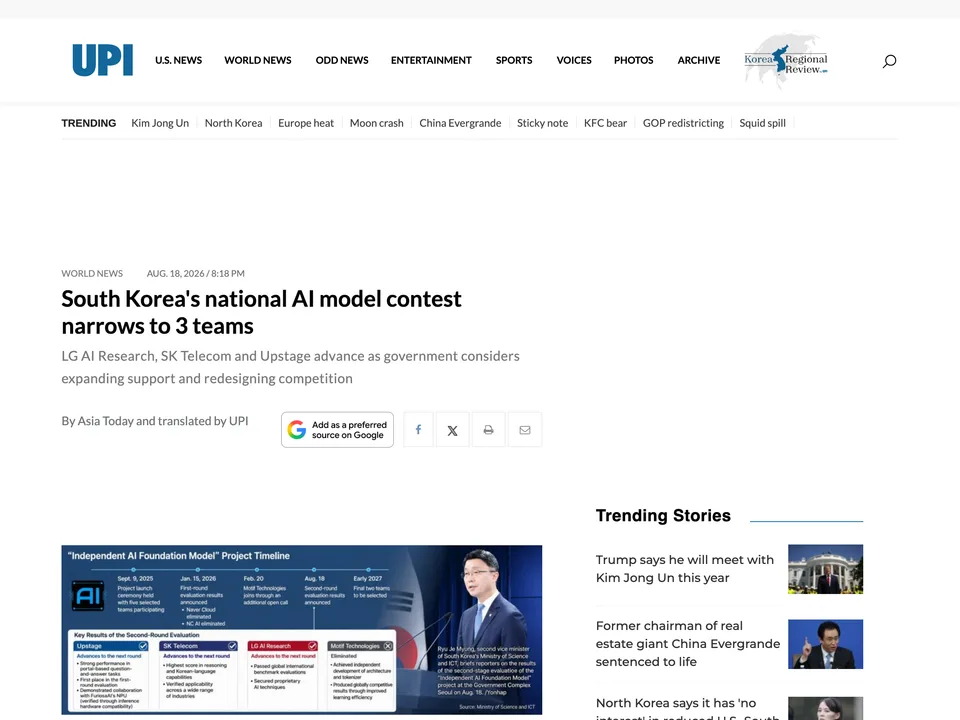
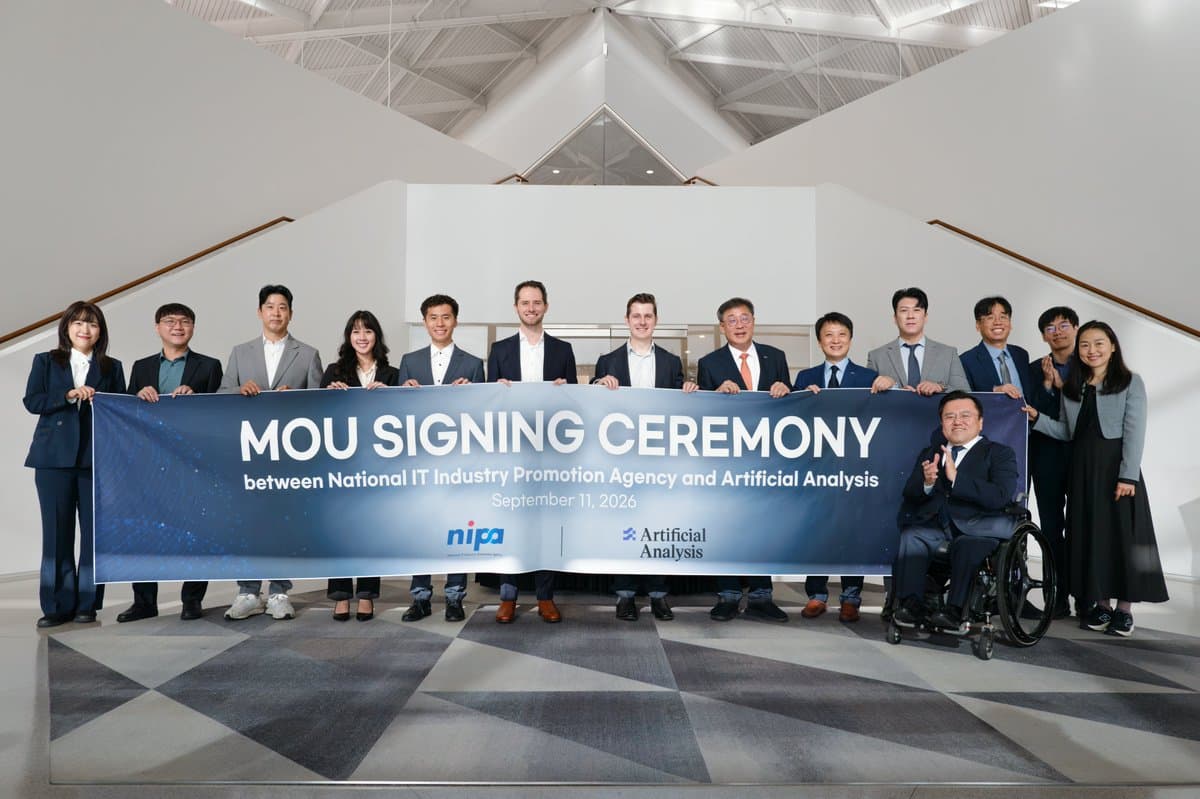
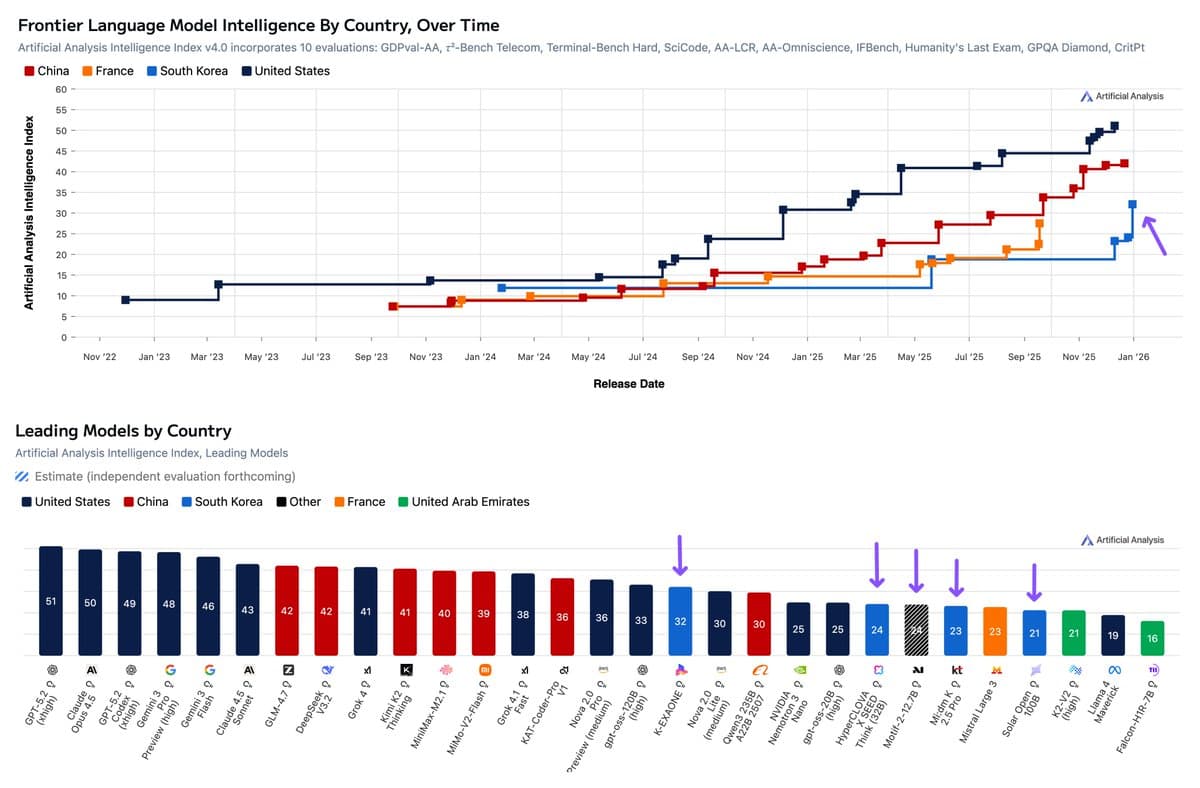
Benchmarking partner for the government of South Korea
We were the benchmarking partner for South Korea's Sovereign AI Foundation Model project, led by the Ministry of Science and ICT (MSIT) and NIPA. We supported evaluation methodology design, running evaluations, and reporting results.
Cybersecurity
Artificial Analysis Cyber Index Alliance
The Artificial Analysis Cyber Index Alliance brings together industry partners to set a new standard for evaluating AI models on enterprise cyber defense.
The Alliance launches alongside the Artificial Analysis Cyber Index. The Index measures the defensive cyber capability of models: discovering vulnerabilities in a codebase, reproducing and validating them, and patching them without breaking existing functionality.
Cyber Index v1 combines three cybersecurity evaluations - CWE-Bench-AA, DeepsecBench-AA, and CyberGym-E2E-AA.

The go-to reference











Get in touch
Artificial Analysis can support federal, state and local governments with benchmarking, advisory, and data to help design AI policy and select AI technologies.