April 23, 2026
OpenAI's GPT-5.5 is the new leading AI model
See model pageOpenAI's GPT-5.5 is the new leading model. GPT-5.5 tops the Artificial Analysis Intelligence Index by 3 points, breaking a three-way tie with Anthropic and Google
OpenAI gave us pre-release access to test all five reasoning effort levels: xhigh, high, medium, low and non-reasoning.
Key takeaways:
➤ OpenAI tops five headline evaluations: GPT-5.5 (xhigh) leads Terminal-Bench Hard, GDPval-AA and our newly hosted APEX-Agents-AA. The model trails only other OpenAI models in CritPt and AA-LCR, and comes second to Gemini 3.1 Pro Preview on three additional evaluations. The largest gains are on AA-Omniscience (+14 pts), our knowledge and hallucination benchmark, and τ²-Bench Telecom (+7 pts), a customer service agent benchmark.
➤ 20% more expensive to run our Index: Per-token pricing has doubled from GPT-5.4 to $5/$30 per 1M input/output tokens. However, a ~40% token use reduction largely absorbs the hike - resulting in a net ~+20% cost to run our Intelligence Index.
➤ Effort a clear ladder for balancing intelligence and cost: GPT-5.5 (medium) scores the same as Claude Opus 4.7 (max) on our Intelligence Index at one quarter of the cost (~$1,200 vs $4,800) - although Gemini 3.1 Pro Preview scores the same at a cost of ~$900. GPT-5.5 (low) approximates Claude Opus 4.7 (Non-reasoning, high) on our Intelligence Index at half the cost to run (~$500 vs ~$1,000).
➤ Number one in GDPval-AA with an Elo of 1785: GPT-5.5 (xhigh) leads Claude Opus 4.7 (max) by ~30 pts and Gemini 3.1 Pro Preview by ~470 pts. GDPval-AA is Artificial Analysis' benchmark that leverages OpenAI's GDPval dataset to evaluate models on real-world economically valuable tasks.
➤ Top AA-Omniscience accuracy, but trailing the frontier on hallucination: Our private AA-Omniscience benchmark rewards factual knowledge across diverse topics, but punishes hallucination. GPT-5.5 (xhigh) has the highest accuracy at 57% - meaning the model can recall facts in the Omniscience corpus more effectively than any other model. However, it has a hallucination rate of 86% - vs Opus 4.7 (max) at 36%, and Gemini 3.1 Pro Preview at 50%. This makes it more likely to answer a question when it does not 'know' the answer. The 14 pt gain in AA-Omniscience from GPT-5.4 (xhigh) was largely driven by knowledge, with a modest improvement in hallucination.
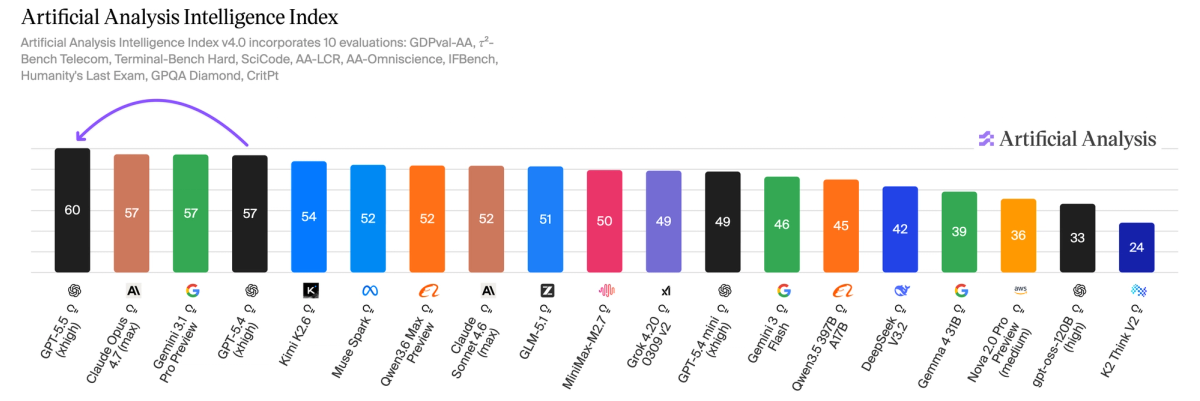 GPT-5.5 tops the Artificial Analysis Intelligence Index by 3 points, breaking a three-way tie with Anthropic and Google
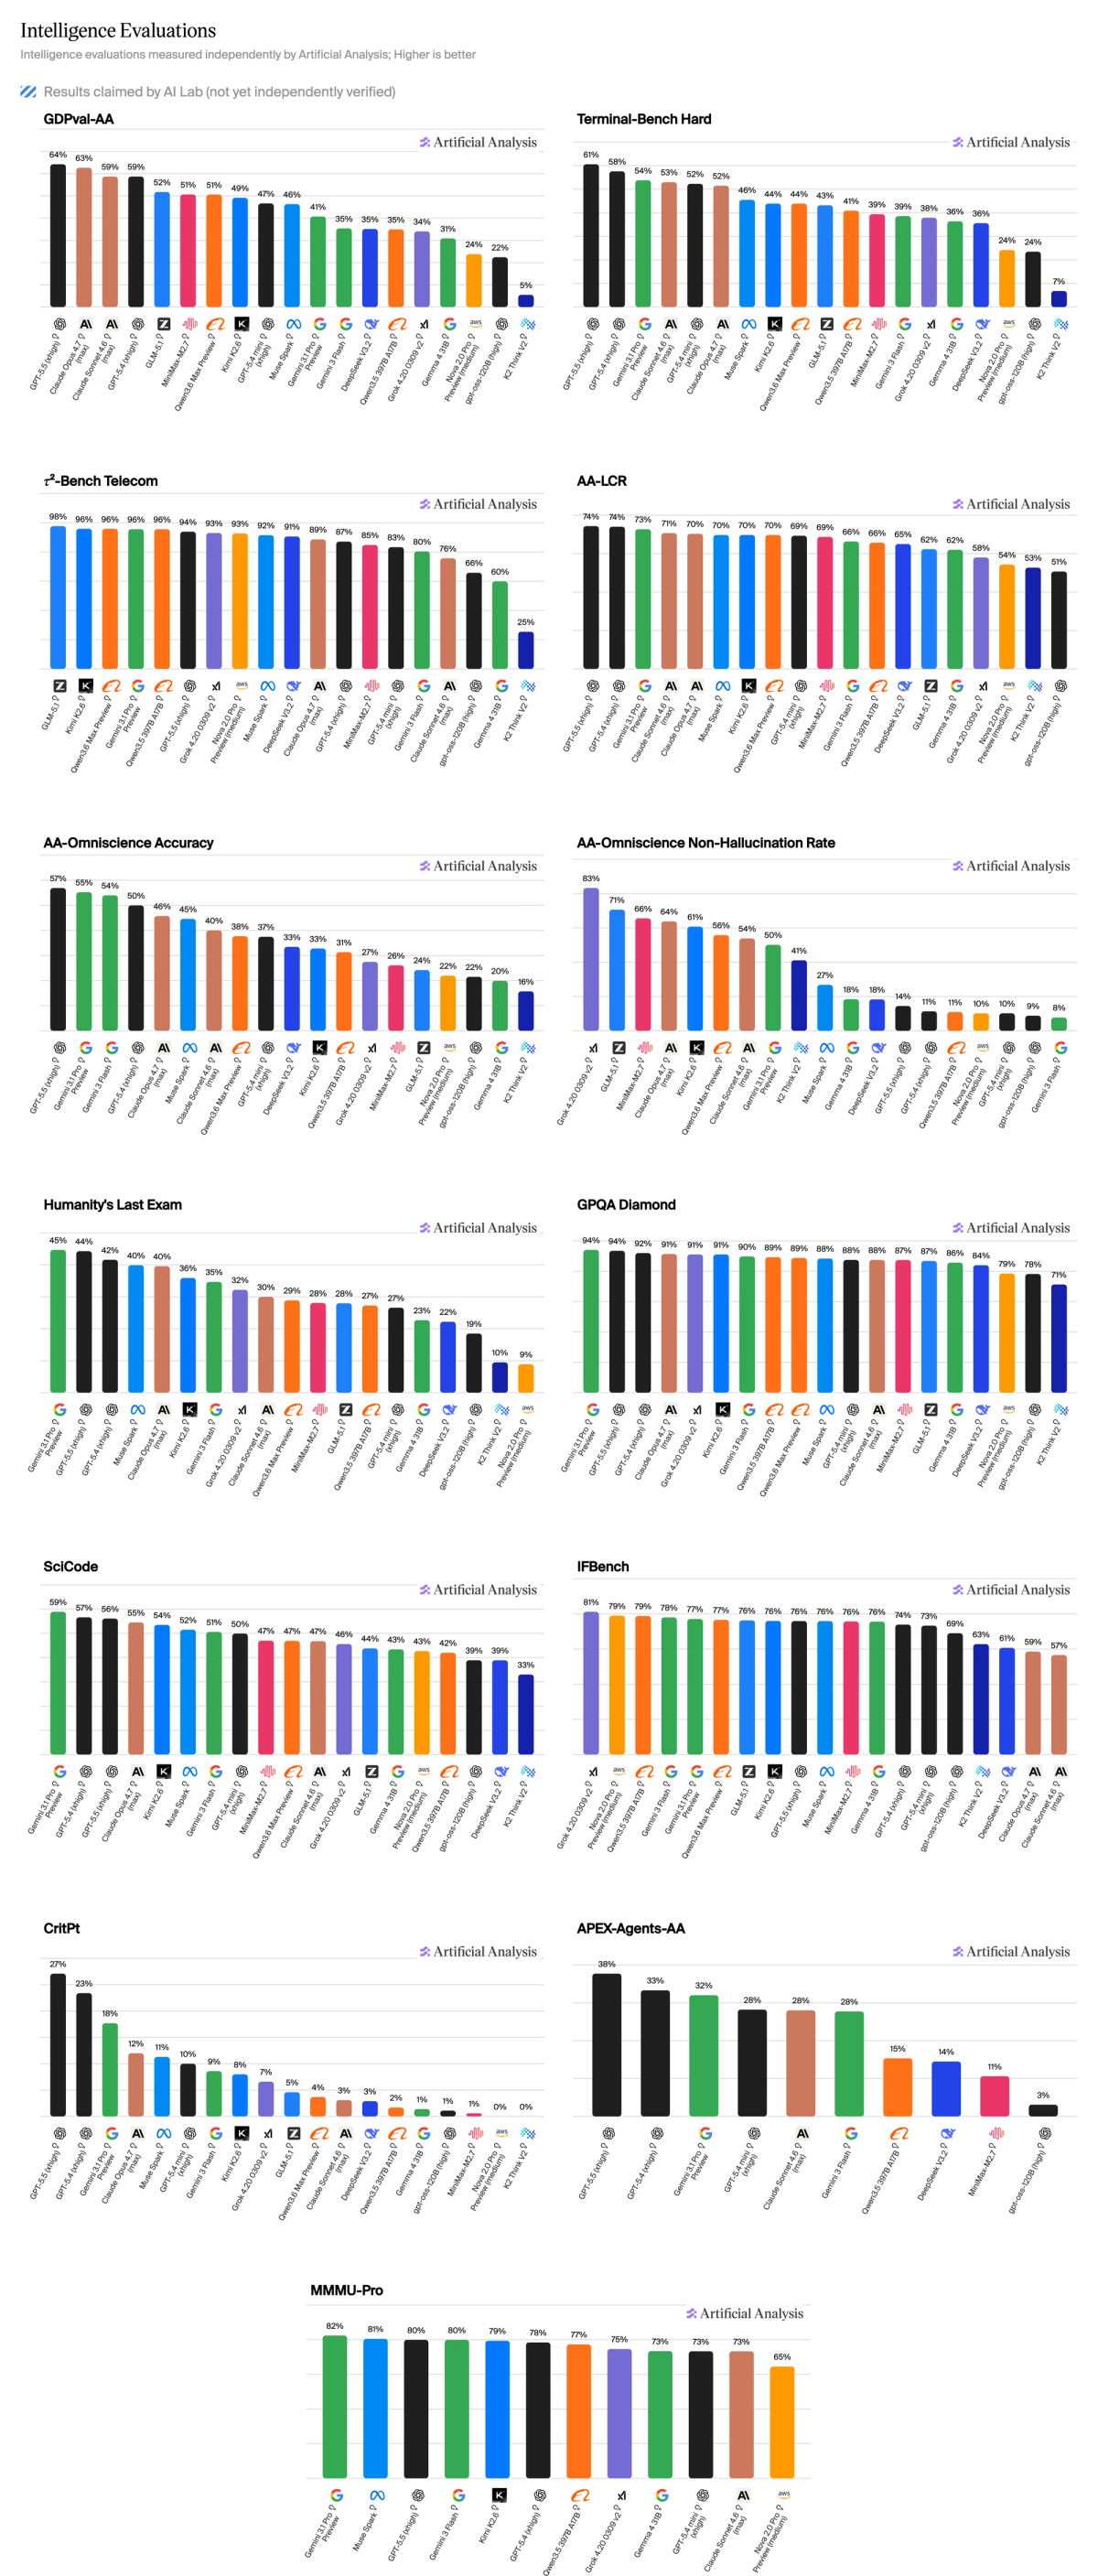 OpenAI leads five of our headline evaluations and places second to Gemini 3.1 Pro Preview on three.
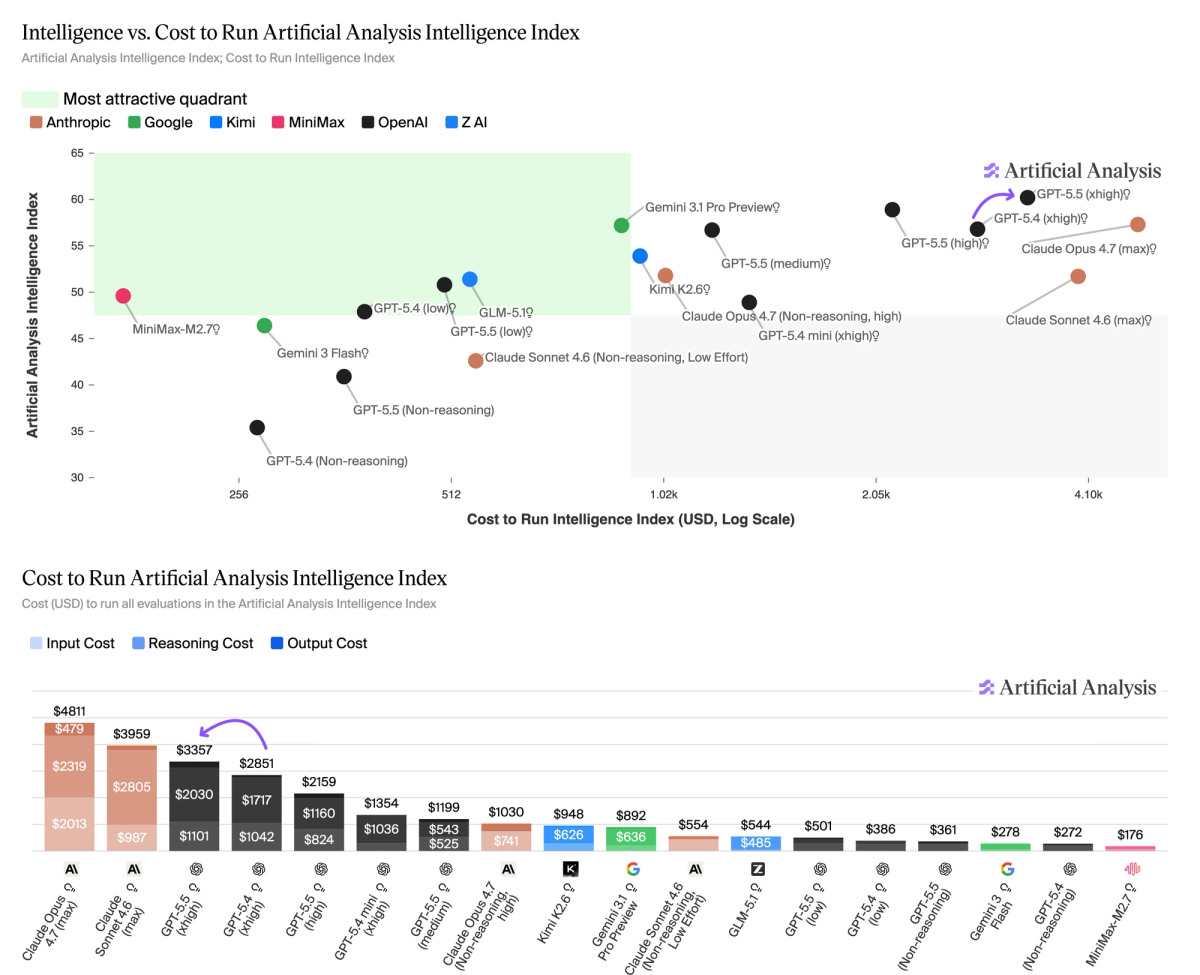 Effort variants provide a clear ladder to balance intelligence and cost. GPT-5.5 (xhigh) is ~20% more expensive to run our Index than its predecessor, but 30% cheaper than Claude Opus 4.7 (max)
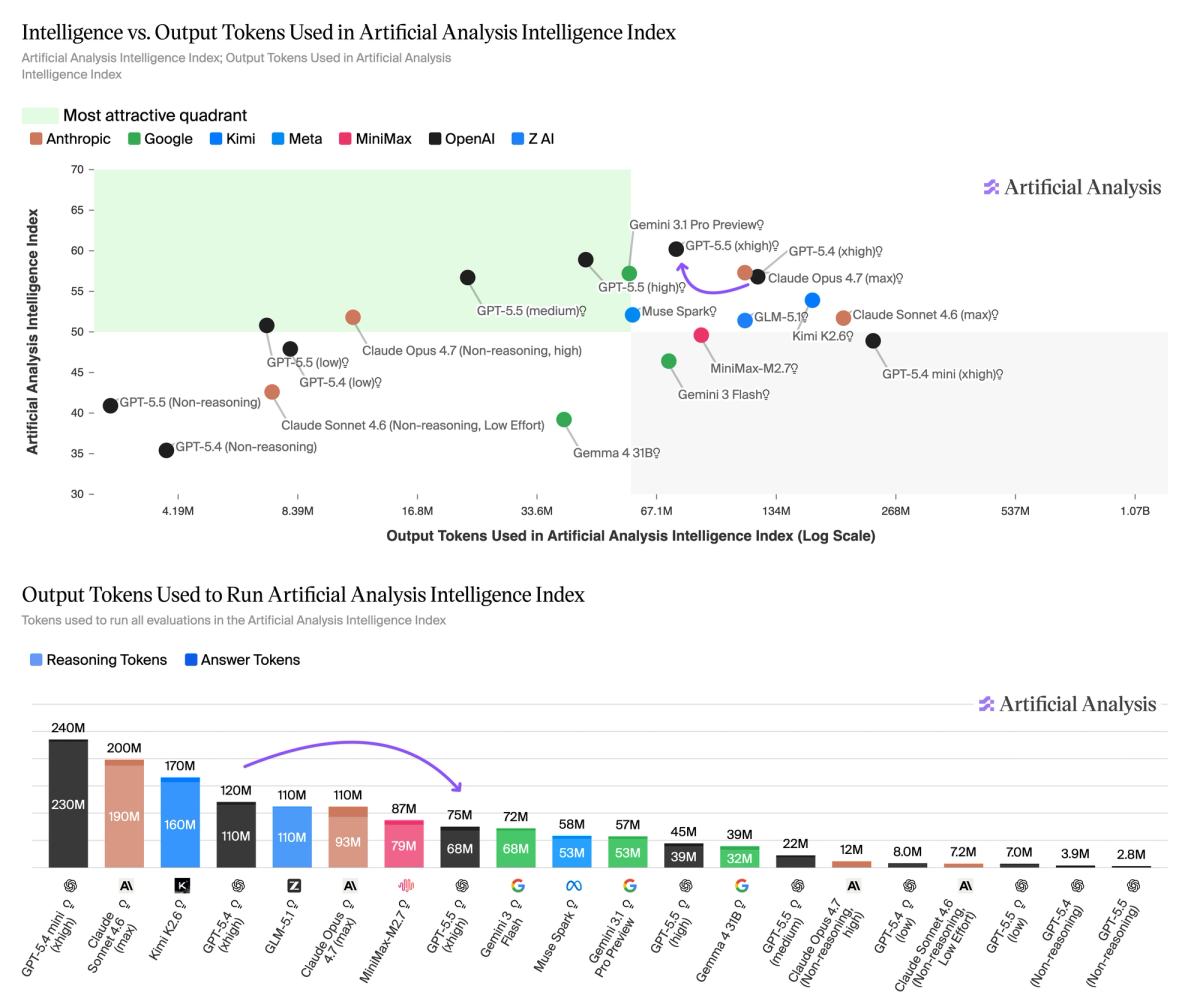 GPT-5.5 (xhigh) uses ~40% fewer output tokens to run our Index than its predecessor
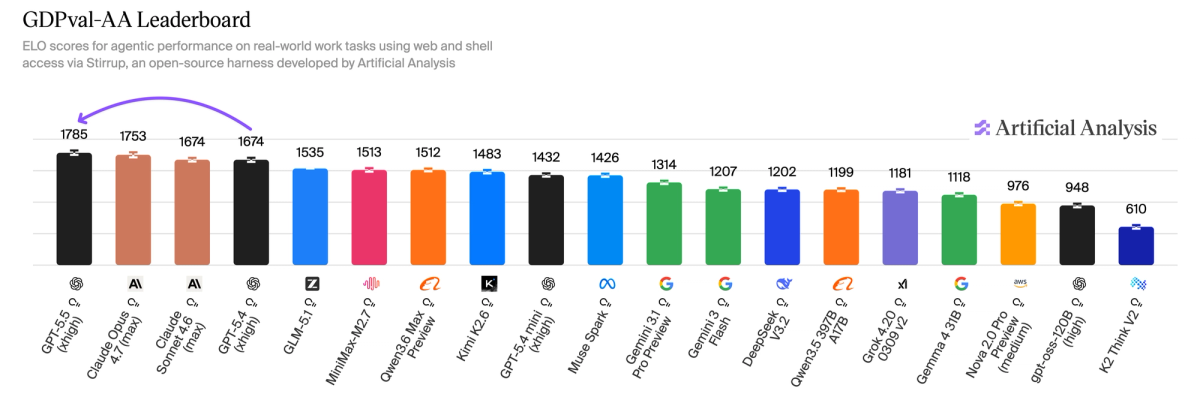 GPT-5.5 (xhigh) leads GDPval-AA with an Elo of 1785
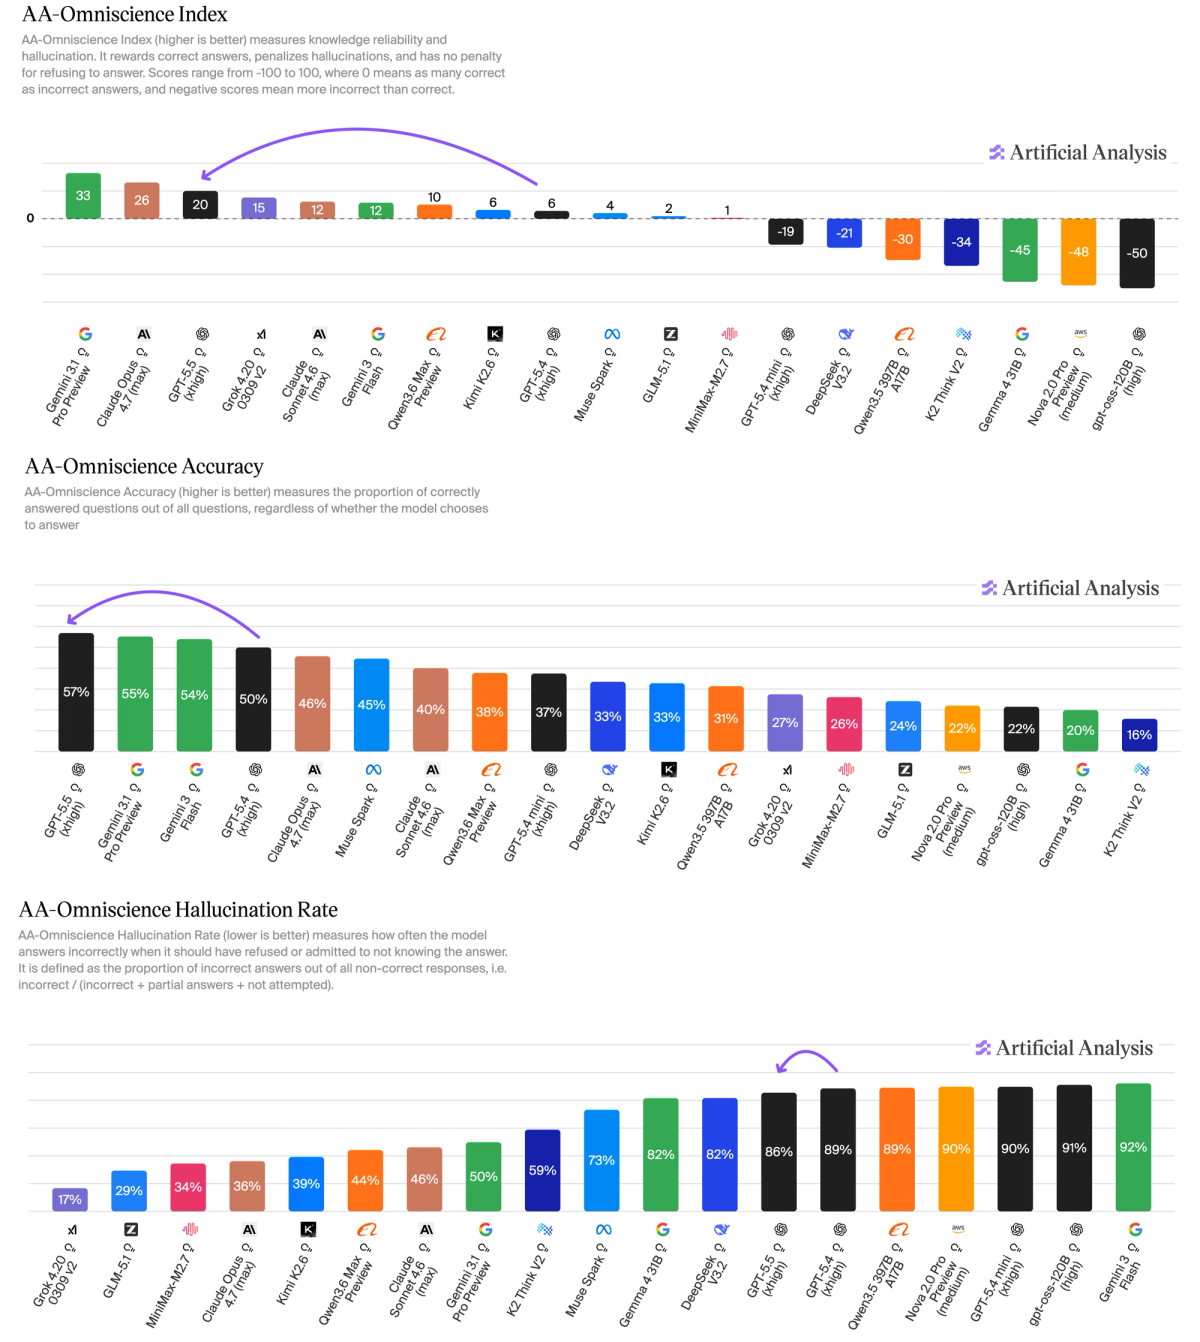 GPT-5.5 (xhigh) records our highest ever AA-Omniscience accuracy score but trails the frontier on hallucination
See Artificial Analysis for further details and benchmarks of GPT-5.5: https://artificialanalysis.ai/models/gpt-5-5
Read the latest
Korean AI Lab Upstage releases Solar Mini 4
Korean AI Lab Upstage has released Solar Mini 4 which scores 24 on the Artificial Analysis Intelligence Index, but costs ~5x as much per task as GPT-6 Luna (max) despite similar per-token prices
September 30, 2026
Gemini 4 Argon: Google is back as one of the top three labs in intelligence achieved
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
September 30, 2026
AA-AgentPerf-Local: Benchmarking local AI agents on laptops and workstations
Our open-source tool for testing how fast agentic AI runs on laptops and workstations, with launch results for the DGX Spark, Ryzen AI Halo, MacBook Pro (M5 Pro) and RTX 5090 across four open-weights models
September 29, 2026