June 8, 2026
MiniMax-M3: Leading open weights model, once the weights are released
See model pageMiniMax-M3 scores 55 on the Artificial Analysis Intelligence Index. Once the weights are released, it will be the leading open weights model
M3 is MiniMax's first multimodal M-series model, adding image and video input and a 1M token context window over the text-only MiniMax-M2.7 (50). At 55 on the Intelligence Index it sits just ahead of open weights peers Kimi K2.6 (54) and MiMo-V2.5-Pro (54). MiniMax has noted they plan to release the weights within ~10 days. When MiniMax released the weights for M2.7, it was under a commercially restricted license.
Key takeaways:
-
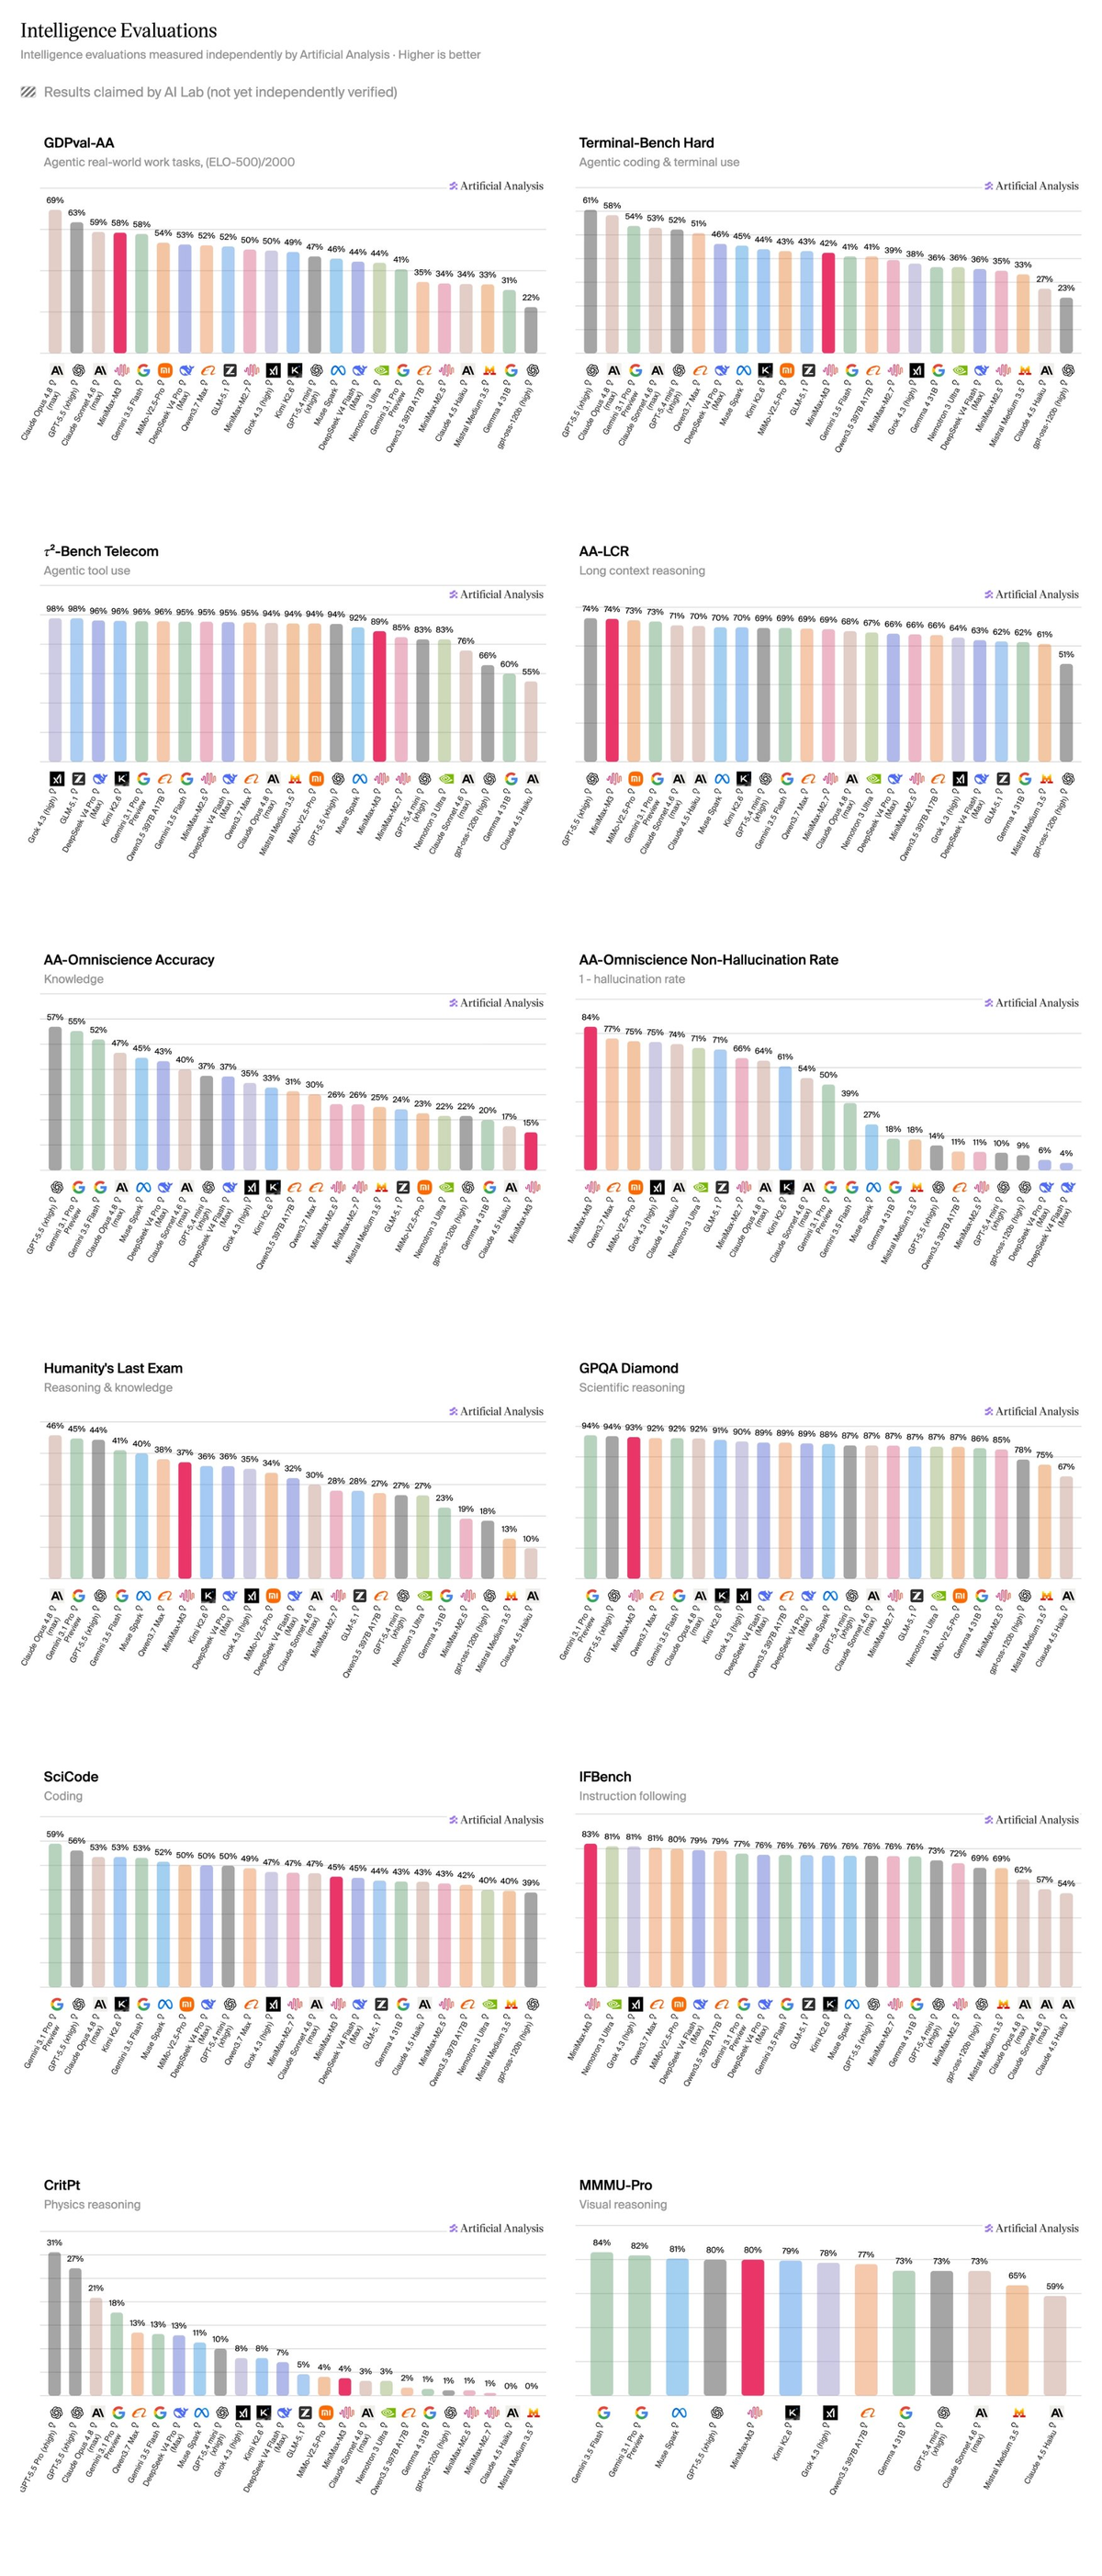
MiniMax-M3 improves on MiniMax-M2.7 across most evaluations. HLE +9 points (28% to 37%), GPQA Diamond +6 (87% to 93%), AA-LCR +5 (69% to 74%), IFBench +7 (76% to 83%), and CritPt +3 (1% to 4%), with a small regression on SciCode (47% to 45%)
-
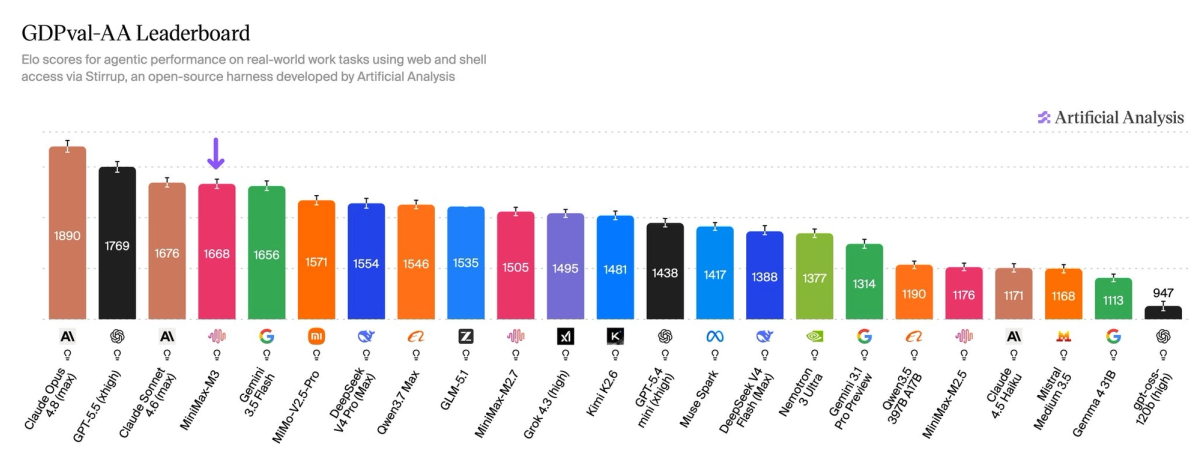
M3 scores ~1670 on GDPval-AA, behind Claude Opus 4.8 (max, 1890) and GPT-5.5 (xhigh, 1769), and level with Claude Sonnet 4.6 (max, 1676). GDPval-AA measures real-world tasks across 44 occupations and 9 industries
-
Native multimodality, scoring ~80% on MMMU-Pro. Level with GPT-5.5 (xhigh, 79.9%) and Kimi K2.6 (79.4%), behind Gemini 3.5 Flash (high, 84.3%). Not all open weights models support native vision input
-
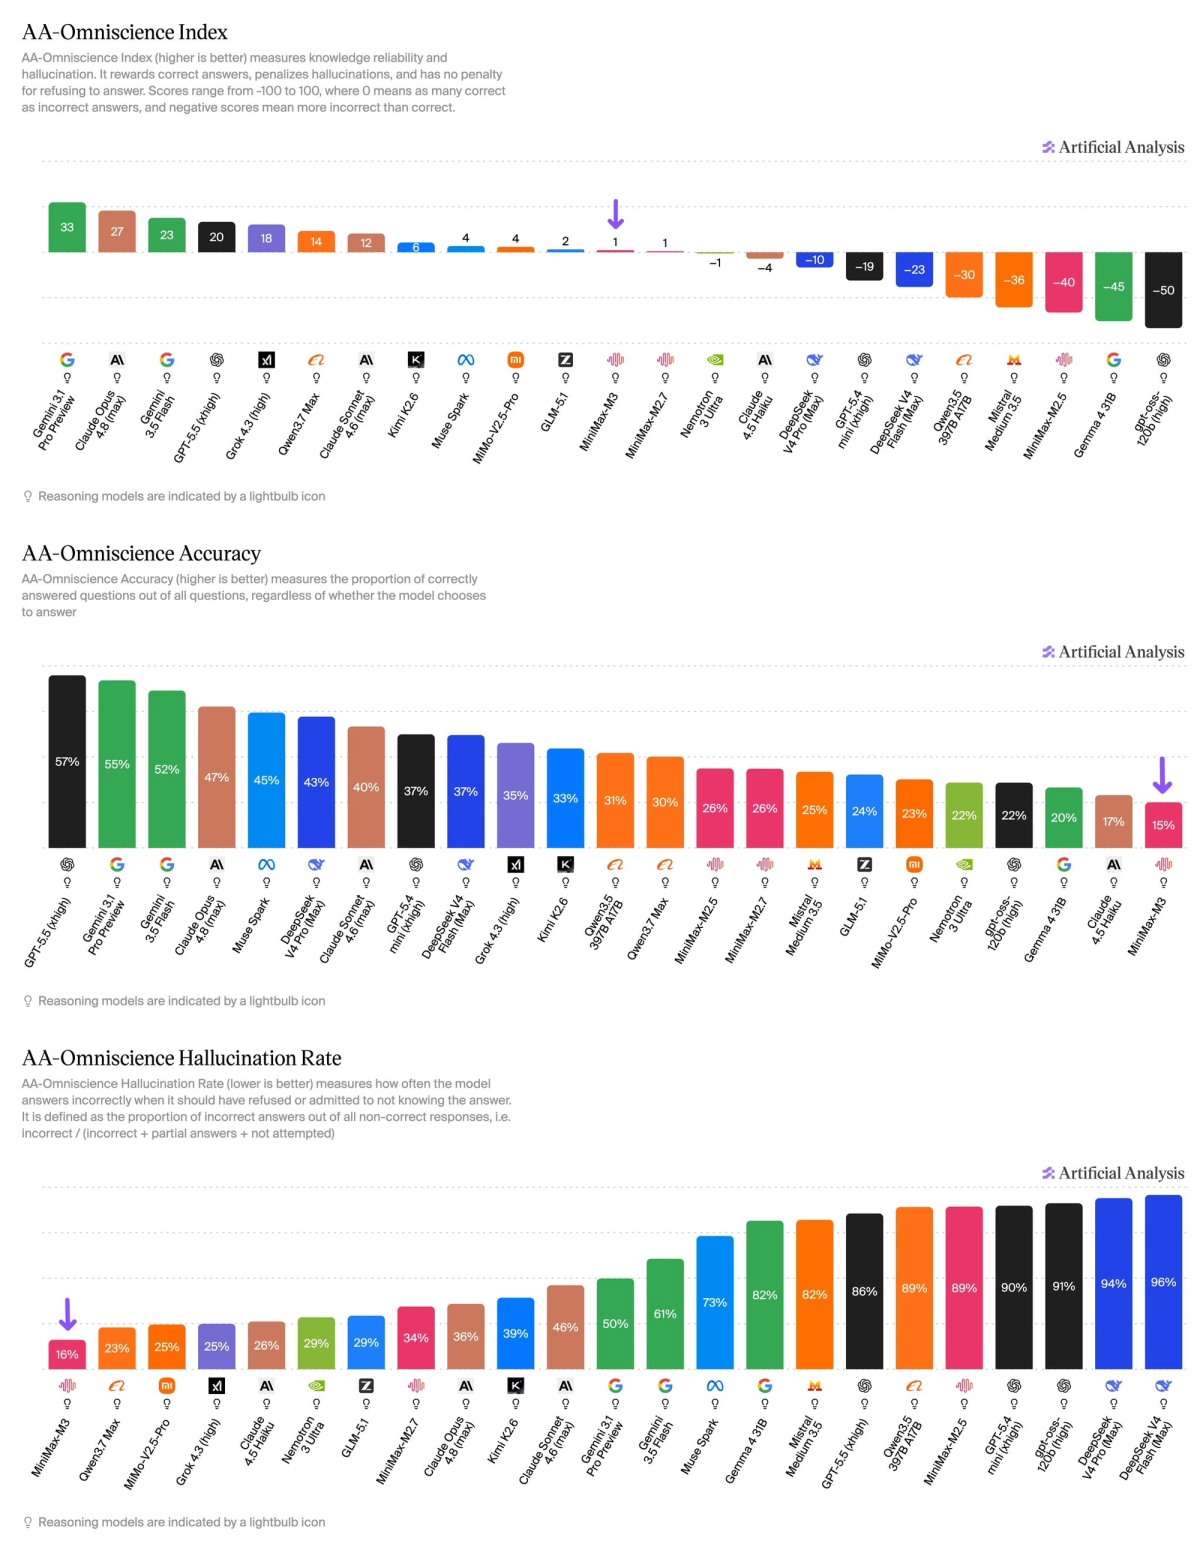
On AA-Omniscience, heavy abstention drives both low hallucination and low accuracy. M3 attempts only 30.9% of questions, the lowest among current peers, yielding a low hallucination rate (16.1%) and low accuracy (15.0%)
-
MiniMax-M3's token usage is close to M2.7's, using ~91M output tokens to run the Intelligence Index (~81M reasoning) versus ~87M (~79M reasoning), while scoring 5 points higher
Key model details:
-
Context window: 1M tokens, up from MiniMax-M2.7's 200K
-
Pricing: $0.30/$1.20 per 1M input/output tokens up to 512K context, rising to $0.60/$2.40 for 512K to 1M context
-
Weights: Not yet released. MiniMax has stated the weights will follow
-
Availability: MiniMax first-party API, SiliconFlow, GMI and Novita
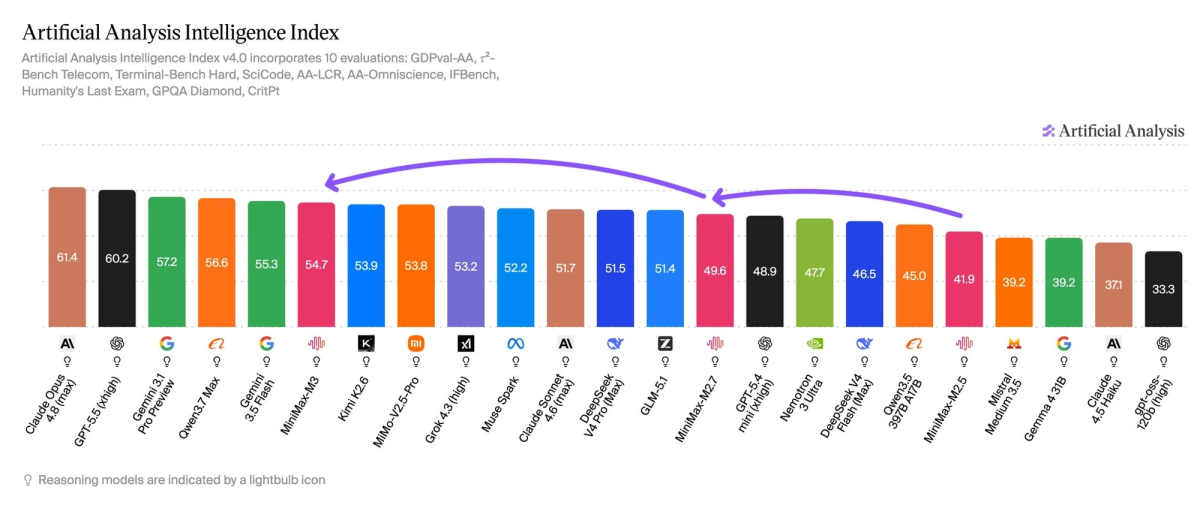
MiniMax-M3 scores ~1670 on GDPval-AA, behind GPT-5.5 (xhigh, 1769) and level with Claude Sonnet 4.6 (Adaptive Reasoning, Max Effort, 1676). Once the weights are released, it will be the highest-scoring open weights model on GDPval-AA. GDPval-AA measures performance on real-world tasks across 44 occupations and 9 major industries
On AA-Omniscience, MiniMax-M3 attempts only 30.9% of questions, the lowest among current peers. The abstention yields a low hallucination rate (16.1%) and accuracy (15.0%)
Breakdown of individual evaluation results for MiniMax-M3
Read the latest
Mistral has released Mistral Large 4, making France home to the most intelligent model outside the US and China
Mistral has released Mistral Large 4, scoring 38 on the Artificial Analysis Intelligence Index; France is back to having the most intelligent model from outside the US and China
October 6, 2026
Korean AI Lab Upstage releases Solar Mini 4
Korean AI Lab Upstage has released Solar Mini 4 which scores 24 on the Artificial Analysis Intelligence Index, but costs ~5x as much per task as GPT-6 Luna (max) despite similar per-token prices
September 30, 2026
Gemini 4 Argon: Google is back as one of the top three labs in intelligence achieved
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
September 30, 2026