October 23, 2026
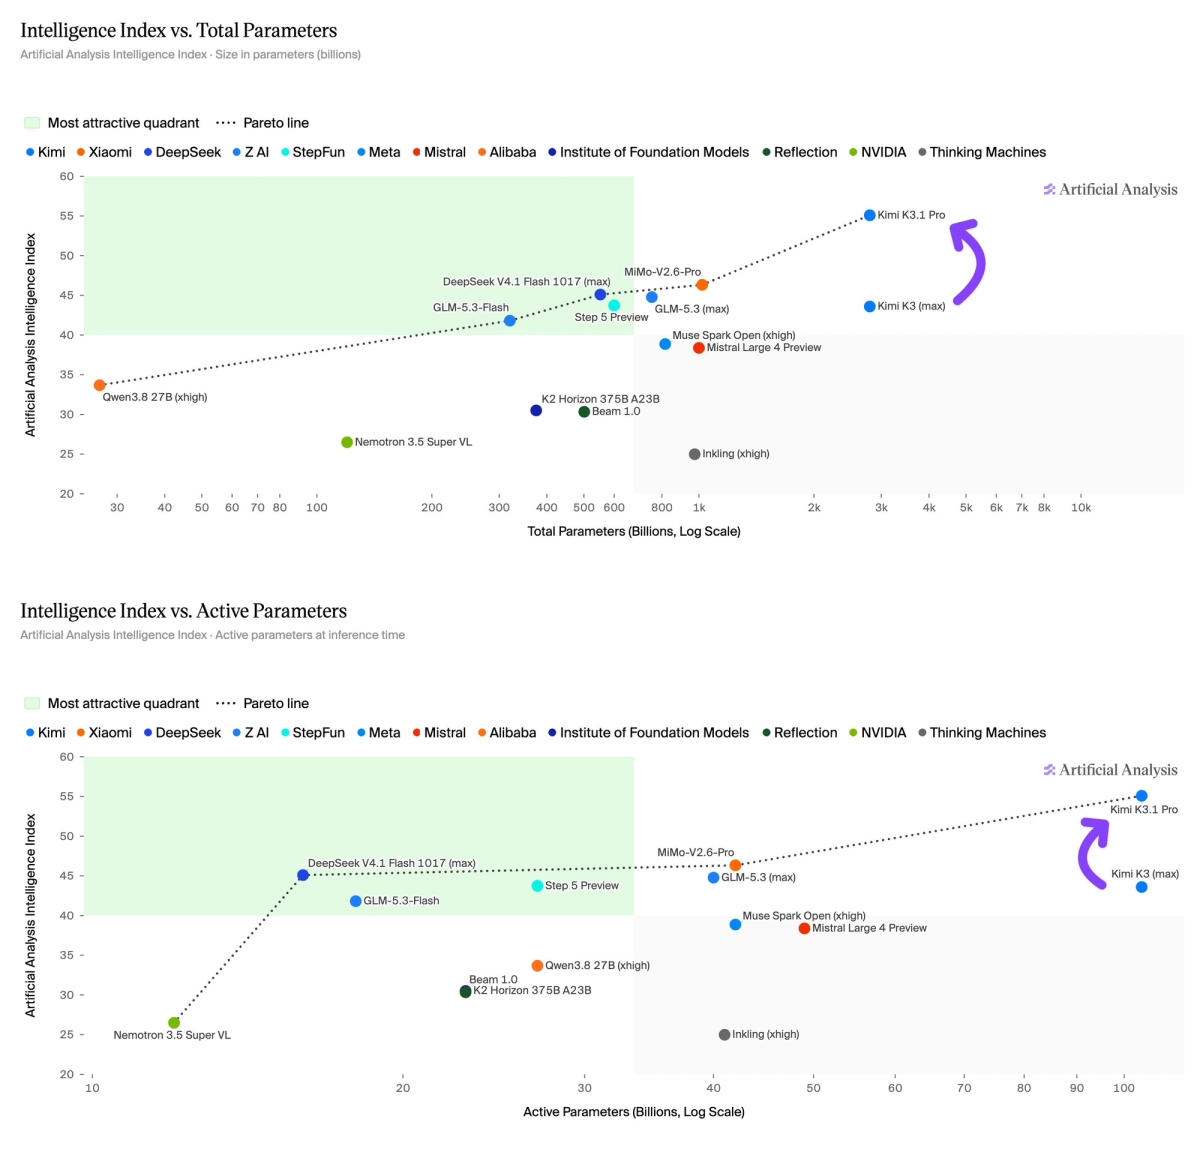
Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will be the leading open-weights model once its weights are published
See model page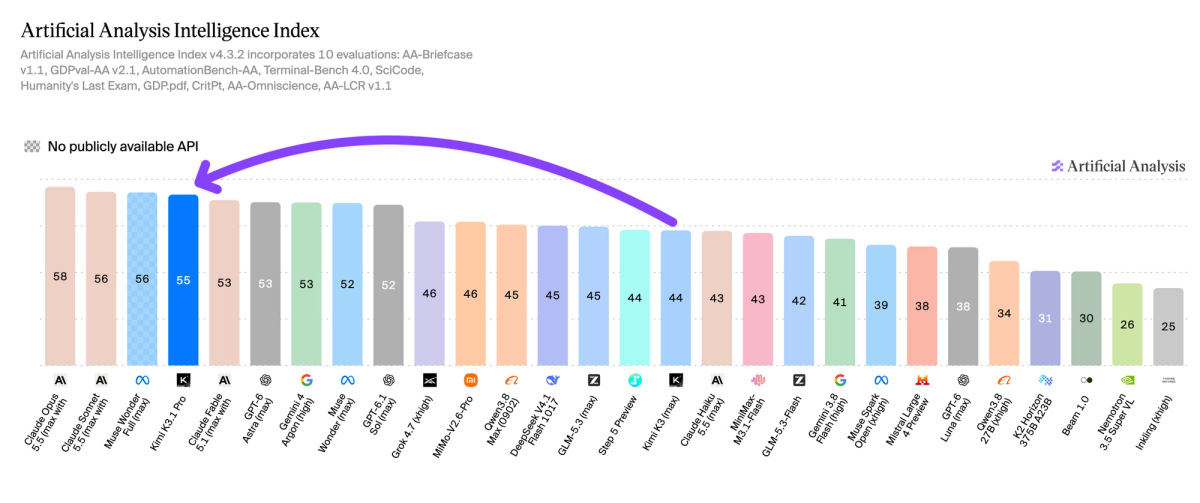
Moonshot's new reasoning model gains 11 points over Kimi K3 (max, 44). It trails only Claude Opus 5.5 (max with fallback, 58), Claude Sonnet 5.5 (max with fallback, 56), and Muse Wonder Full (max, 56) on the Intelligence Index.
Once the weights for K3.1 Pro are released it will be the highest-scoring open weights model and the gap between the leading open weights and proprietary models on the Intelligence Index will narrow from 12 points to 3.
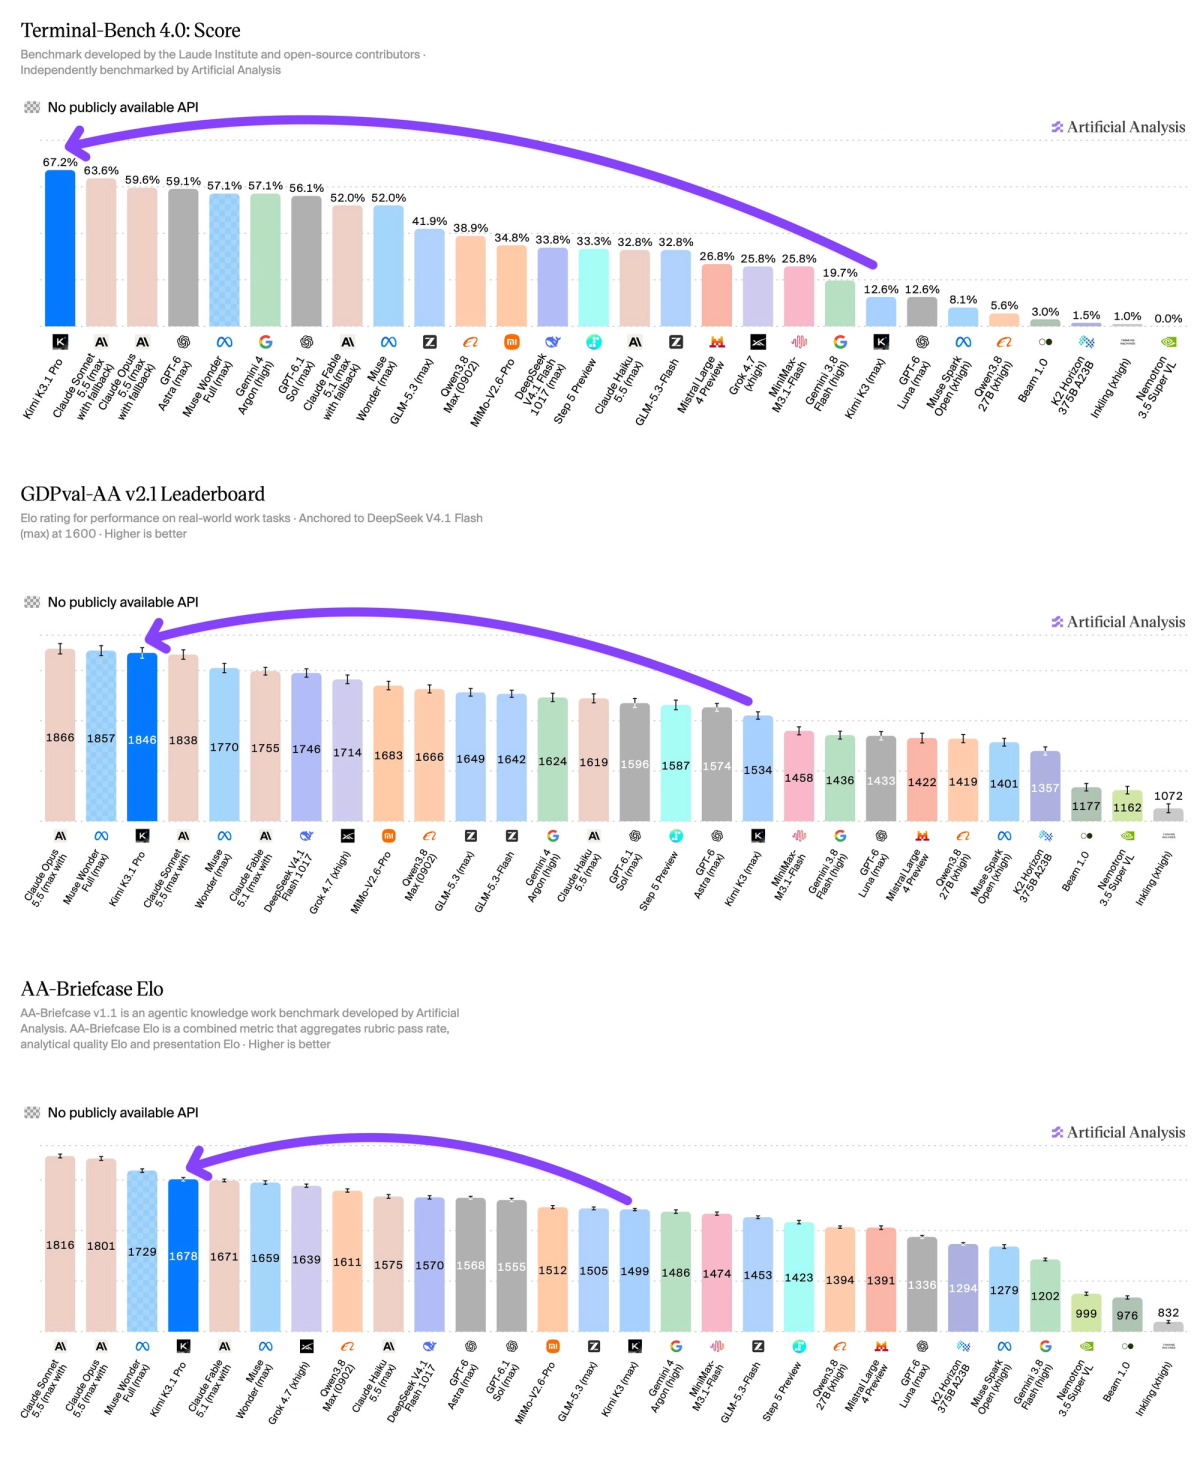
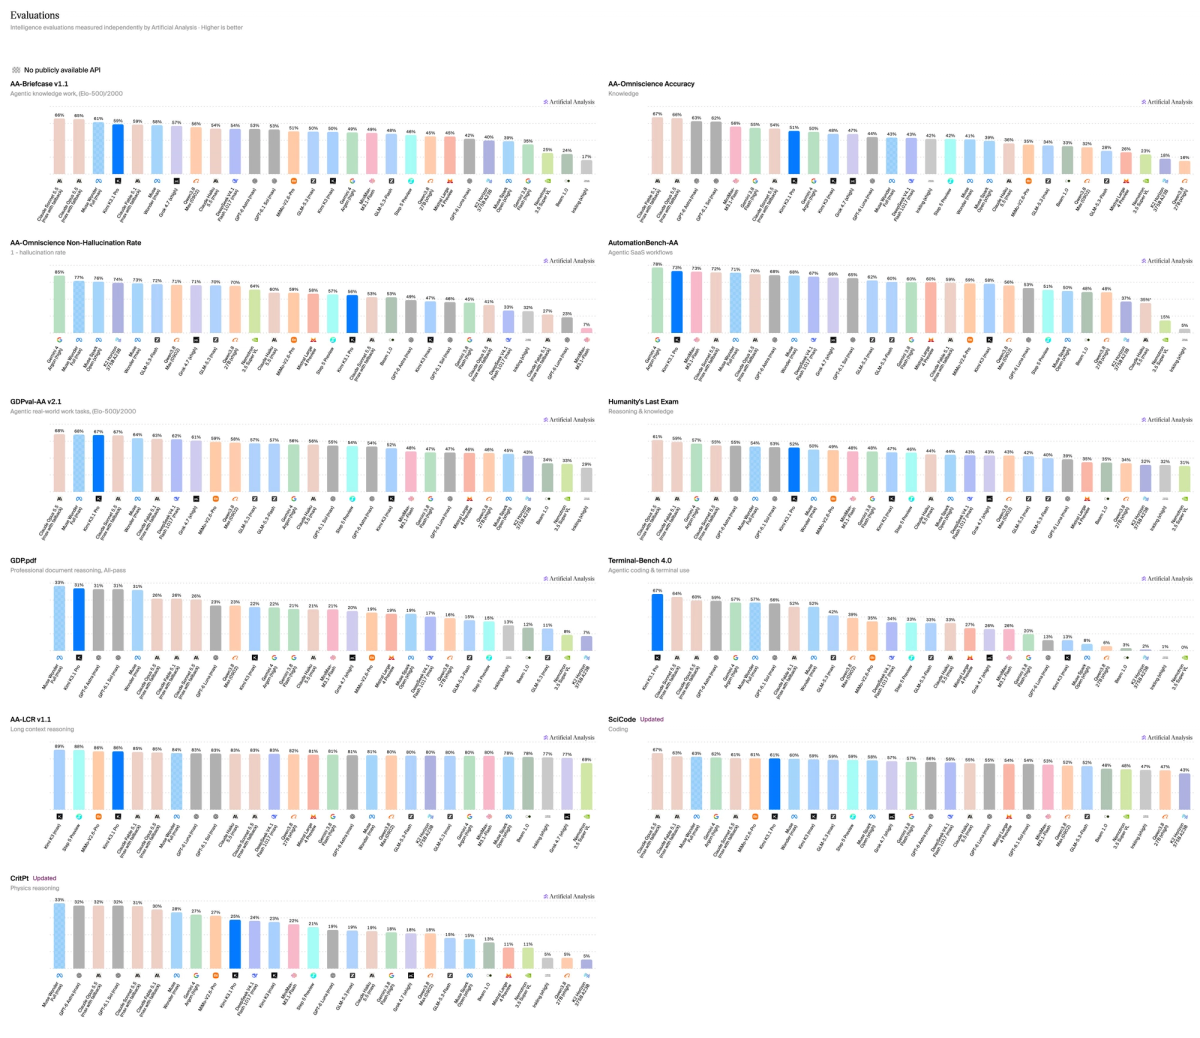
Key results: ➤ Large gains in agentic performance: Kimi K3.1 Pro scores 3rd on GDPval-AA with 1,846 Elo, up 312 Elo from Kimi K3, behind only Claude Opus 5.5 (1,866 Elo) and Muse Wonder Full (1,857 Elo). Kimi K3.1 Pro also achieves the highest score of any model on Terminal-Bench 4.0. K3.1 Pro scores 67%, up from 13% for Kimi K3 and ahead of Claude Sonnet 5.5 (64%). AutomationBench-AA, which tests agentic SaaS workflows, rises from 58% to 73%.
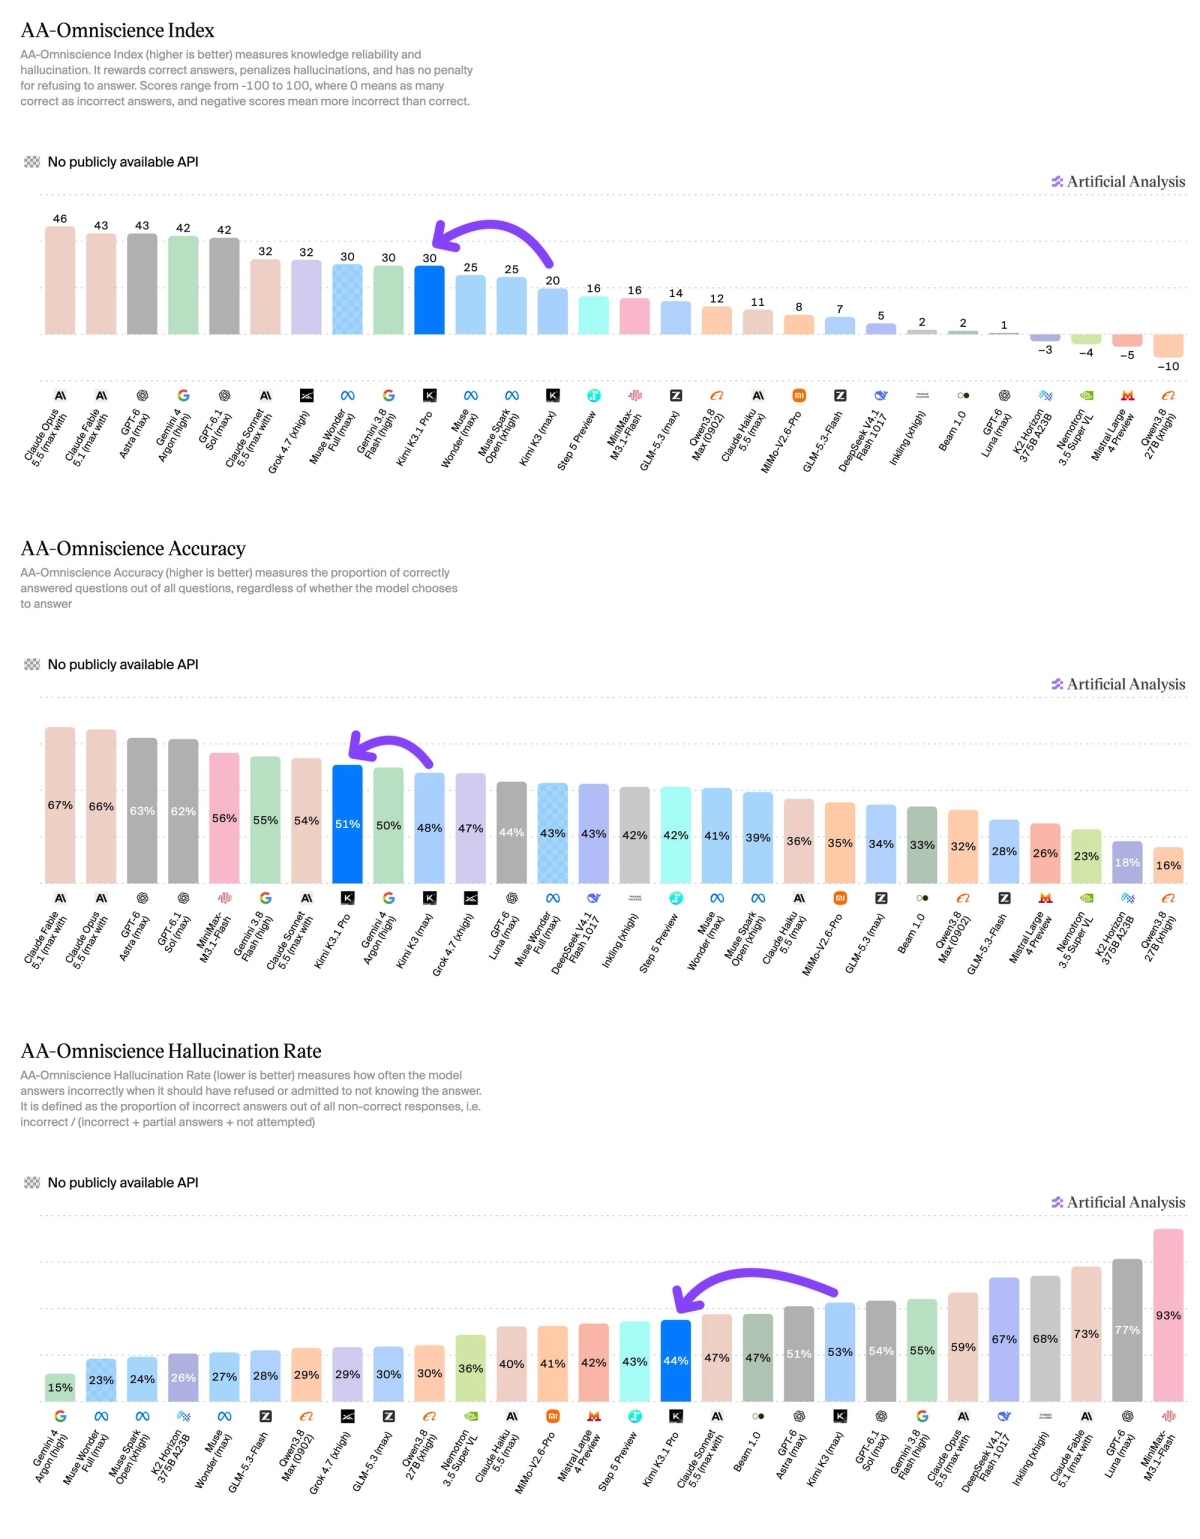
➤ Gains in other evals are more moderate: Humanity's Last Exam rises from 47% to 52%, CritPt from 23% to 25%, and SciCode from 59% to 61%. AA-Omniscience Index rises from 20 to 30, as the hallucination rate falls from 53% to 44% and accuracy rises from 48% to 51%.
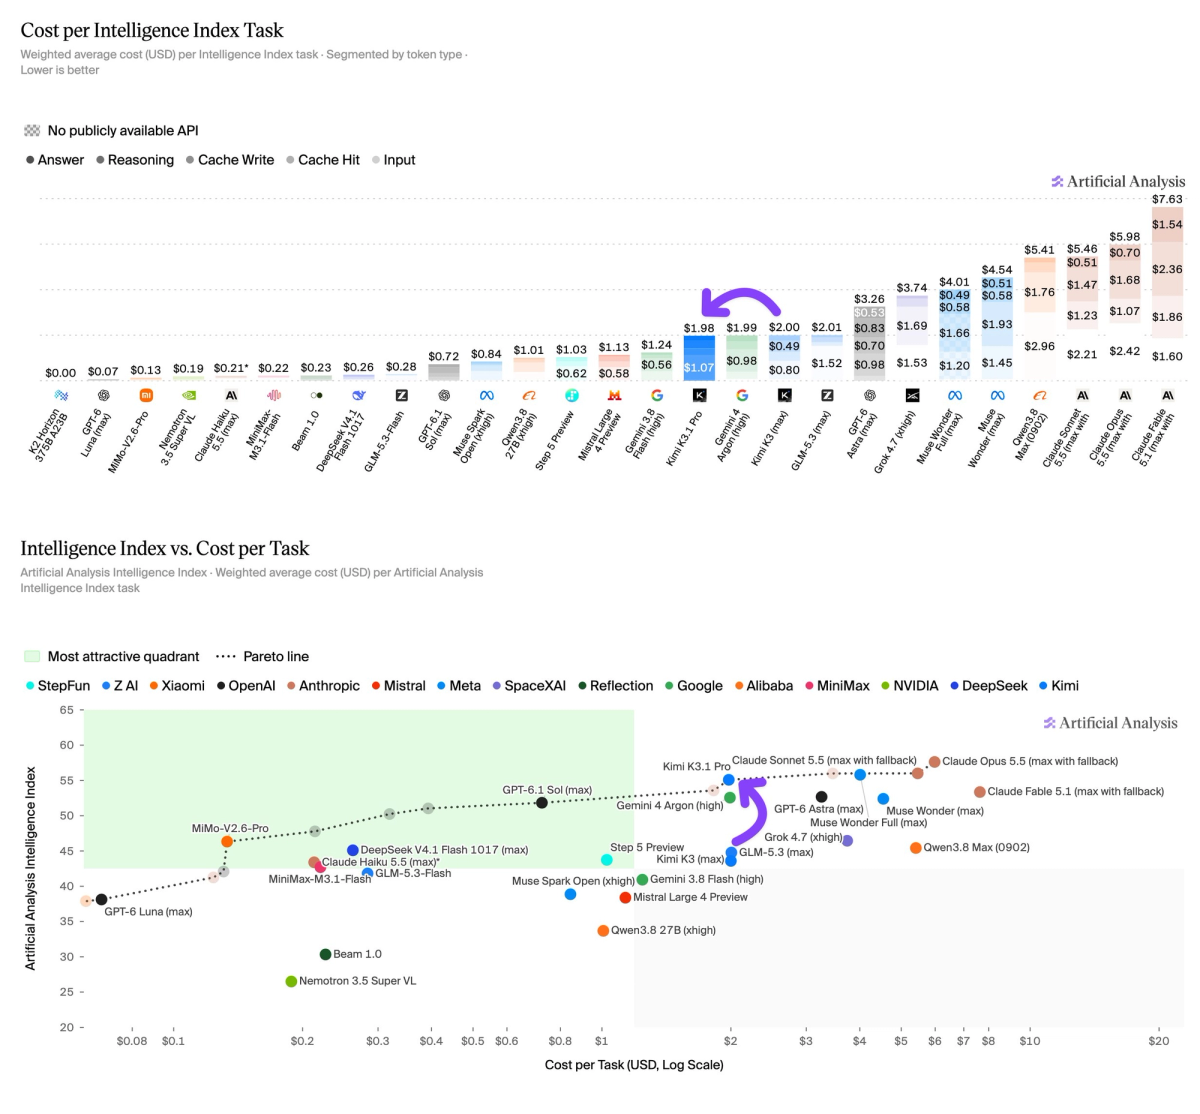
➤ Cost per Task roughly equal to Kimi K3 at $1.98 per Task: K3.1 Pro uses 55K output tokens per Intelligence Index task, 14% more than Kimi K3 at 48K, while its first-party token prices are 33% lower.
Additional model details: ➤ Context window: 1M tokens. ➤ Size: 2.8T total, 104B active parameters ➤ Input modalities: Text and image ➤ Weights and license: Weights currently not published, Moonshot is expected to release the weights soon after launch ➤ Pricing: $2/$10/$0.20 per 1M input/output/cache hit tokens, 33% lower than Kimi K3 on all three rates.
Individual eval results:
Read the latest
Announcing AA-PersonalityBench: measuring how AI models communicate
AA-PersonalityBench measures the personality and communication style of AI models. A panel of LLM judges compares answers pairwise on 30 personality traits, which roll up into 8 personality indexes, alongside 21 communication characteristics measured directly from every response.
October 19, 2026
HealthBench and HealthBench Professional: Evaluating models in realistic health conversations
We’re launching leaderboards for HealthBench and HealthBench Professional, two benchmarks evaluating how AI models respond in realistic health conversations
October 19, 2026
Reflection has released Beam, their first model launch
Reflection’s first model, Beam, scores 30 on the Artificial Analysis Intelligence Index, placing it #2 among US open weights models
October 16, 2026