September 29, 2026
GPT-6.1 Sol replaces GPT-6 Sol after just 7 days. It scores 1 point below GPT-6 Astra in the Intelligence Index at less than one quarter of the Cost per Task
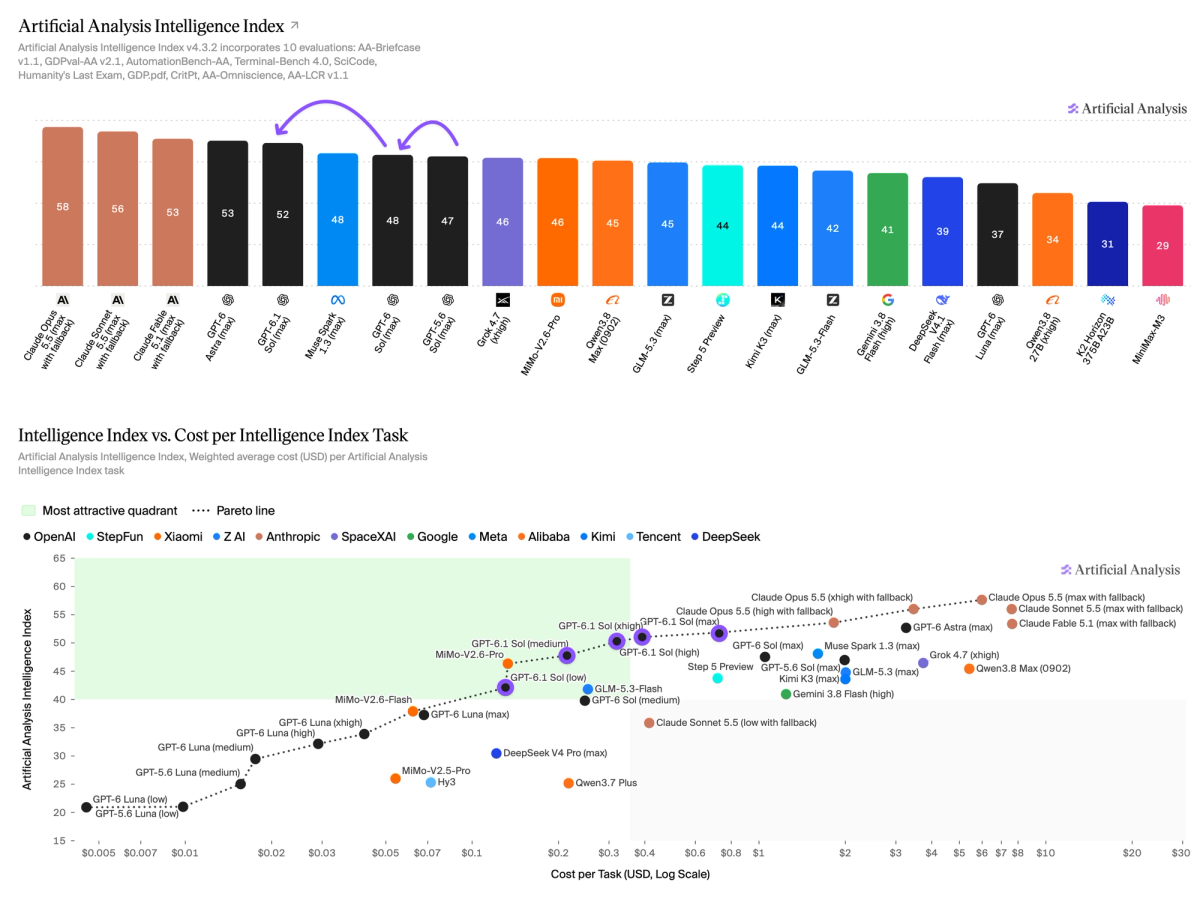
Pricing matches GPT-6 Sol at $2/$10 per million input/output tokens, except that the cache read discount rises from 90% to 95%. GPT-6.1 Sol’s overall blended price for agentic workloads is therefore slightly lower than GPT-6 Sol. This represents an additional price cut, following GPT-6 Sol’s original 50% discount from GPT-5.6 Sol.
Key takeaways:
➤ Achieves near-Astra Intelligence: GPT-6.1 Sol gains 4 points in the Intelligence Index vs GPT-6 Sol, and 5 points vs GPT-5.6 Sol - landing 1 point below GPT-6 Astra. It makes significant gains in agentic knowledge work, improving 4 points and 5 points in AA-Briefcase v1.1 and GDPval-AA v2.1 respectively. Other notable gains include a 12 point jump in Terminal-Bench 4.0, a 5 point jump in Humanity’s Last Exam, a 6 point jump in GDP.pdf, and an 8 point jump in AA-Omniscience Accuracy coupled with hallucination rate falling from 60% to 54%.
➤ Pushes cost efficiency frontier: At max effort, GPT-6.1 Sol costs less than a quarter of GPT-6 Astra per Intelligence Index task ($0.72 vs $3.26). It also costs 31% less per task than GPT-6 Sol ($1.05) and 64% less than GPT-5.6 Sol ($1.99). All effort levels of GPT-6.1 Sol push out the cost efficiency Pareto frontier: for a given level of intelligence, there is no cheaper model.
➤ Pushes token efficiency frontier, but uses slightly more output tokens than GPT-6 Sol: GPT-6.1 Sol uses ~10-30% more output tokens than GPT-6 Sol across effort levels. However, due to the increase in Intelligence Index score, its low and medium effort levels are Pareto optimal for token efficiency.
➤ Gains in Coding Agent Index: GPT-6.1 Sol gains 3 points on GPT-6 Sol at max effort in the Artificial Analysis Coding Agent Index, and sits 2 points below GPT-6 Astra.
Read the latest
Announcing the Artificial Analysis Cyber Index Alliance
The Artificial Analysis Cyber Index Alliance brings together industry partners to set a new standard for evaluating how AI models perform on enterprise cyber defense tasks. The Alliance launches alongside the Artificial Analysis Cyber Index, which combines three partner-contributed and open benchmarks to evaluate how well agents find and fix vulnerabilities.
September 28, 2026
Claude Sonnet 5.5 reaches #2 on the Artificial Analysis Intelligence Index
Anthropic's new Sonnet model scores 56, just 2 points behind Opus 5.5 (max), but at the highest Output Tokens per Task we have measured
September 28, 2026
GPT-6 Sol and Luna push the cost efficiency frontier
GPT-6 Sol and Luna push the cost efficiency frontier by halving cost relative to GPT-5.6 Sol and Luna. Intelligence Index and Coding Agent Index scores remain level with GPT-5.6, with progress in some evaluations and regressions in others
September 22, 2026