November 10, 2026
Multimodal Knowledge Agent (MKA) benchmark: testing knowledge work capabilities with complex visual files
See leaderboardWe’ve partnered with Google DeepMind to launch their Multimodal Knowledge Agent (MKA) evaluation, a new benchmark for agentic knowledge work over complex visual files
Google DeepMind’s MKA is a new benchmark requiring agents to review visually complex project files such as schematics and scans, and produce deliverables like slide decks, spreadsheets, reports, and marked-up images
Multimodal Knowledge Agent (MKA) overview:
➤ 200 private real-world visual tasks across 10 industries: Agents work from dense visual project files including architectural drawings, engineering schematics, and clinical scans to produce deliverables including slide decks, spreadsheets, PDFs, Word documents, and marked-up images. Unlike many agentic evaluations, these inputs emphasize realistic visual complexity and domain-specificity, and are genuinely required to complete the task rather than just providing additional context
➤ Climb vs. Regression rubric scoring: Each task is graded against expert rubrics, averaging ~70 weighted criteria per task. Criteria are split into ‘Regression’ (baseline checks models should pass) and ‘Climb’ criteria (harder checks designed to separate strong models). The headline score is Climb WSR (Weighted Satisfaction Rate) - the weighted proportion Climb rubric criteria successfully completed
➤ Evaluated in Stirrup with an agentic judge: We run every task in Stirrup, our open source agent harness, with code execution, web search, web fetch, and image-viewing tools (up to 250 turns), and grade submitted deliverables using GPT-6 Luna (medium) as an agentic judge
Key MKA results:
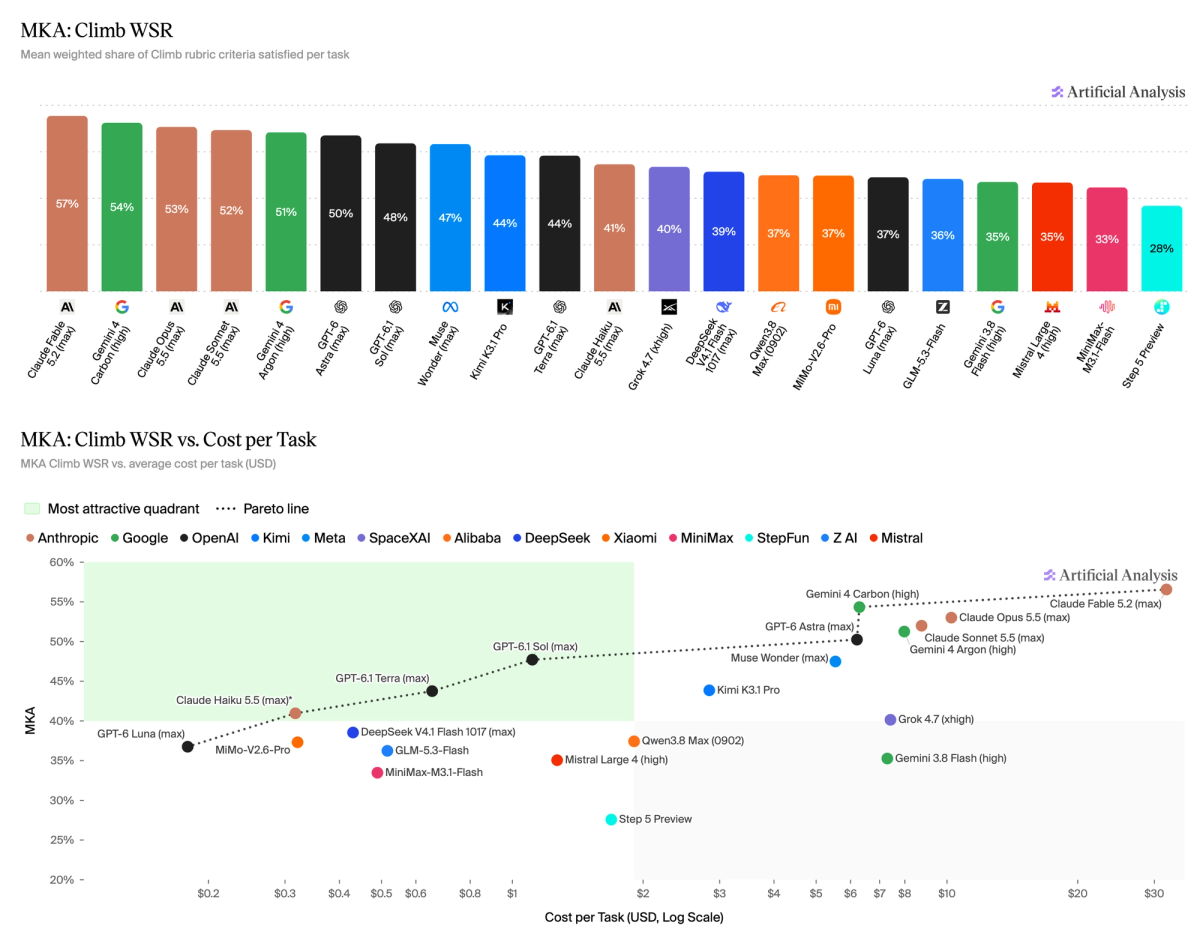
➤ Claude Fable 5.2 leads on multimodal knowledge work: Anthropic’s recently released Claude Fable 5.2 (max) leads the MKA leaderboard with a Climb WSR of 57%, followed by Gemini 4 Carbon (high) at 54% and Claude Opus 5.5 (max) at 53%
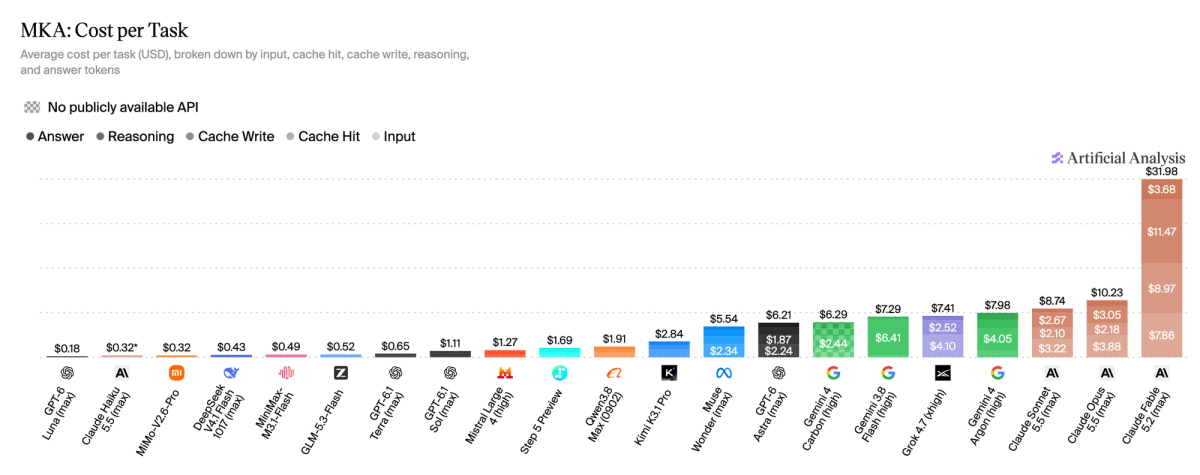
➤ Cost per Task spans nearly 30× within 10 points of the top score: Claude Fable 5.2 averages $31.97 per task, over 5× Gemini 4 Carbon ($6.29) for ~2 extra points, and ~29× GPT-6.1 Sol ($1.11). Below Carbon, all four OpenAI models tested sit on the cost-performance Pareto frontier (GPT-6 Astra, GPT-6.1 Sol, GPT-6.1 Terra, and GPT-6 Luna), with Claude Haiku 5.5 and MiMo-V2.6-Pro making up the rest of the frontier
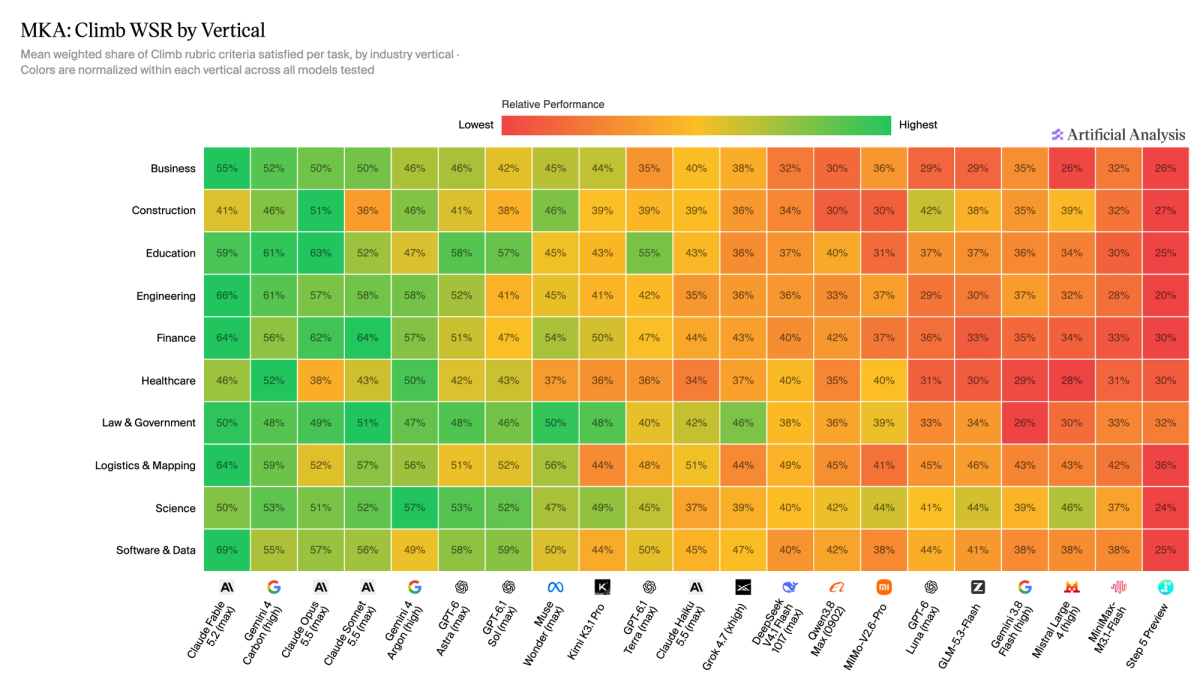
➤ No single model leads across all 10 industry verticals: Claude Fable 5.2 leads five verticals (Software & Data, Engineering, Logistics & Mapping, Business, and Finance alongside Claude Sonnet 5.5), Claude Opus 5.5 (max) leads Education and Construction, Gemini 4 Argon (high) leads Science, Gemini 4 Carbon (high) leads Healthcare, and Claude Sonnet 5.5 (max) narrowly leads Law & Government
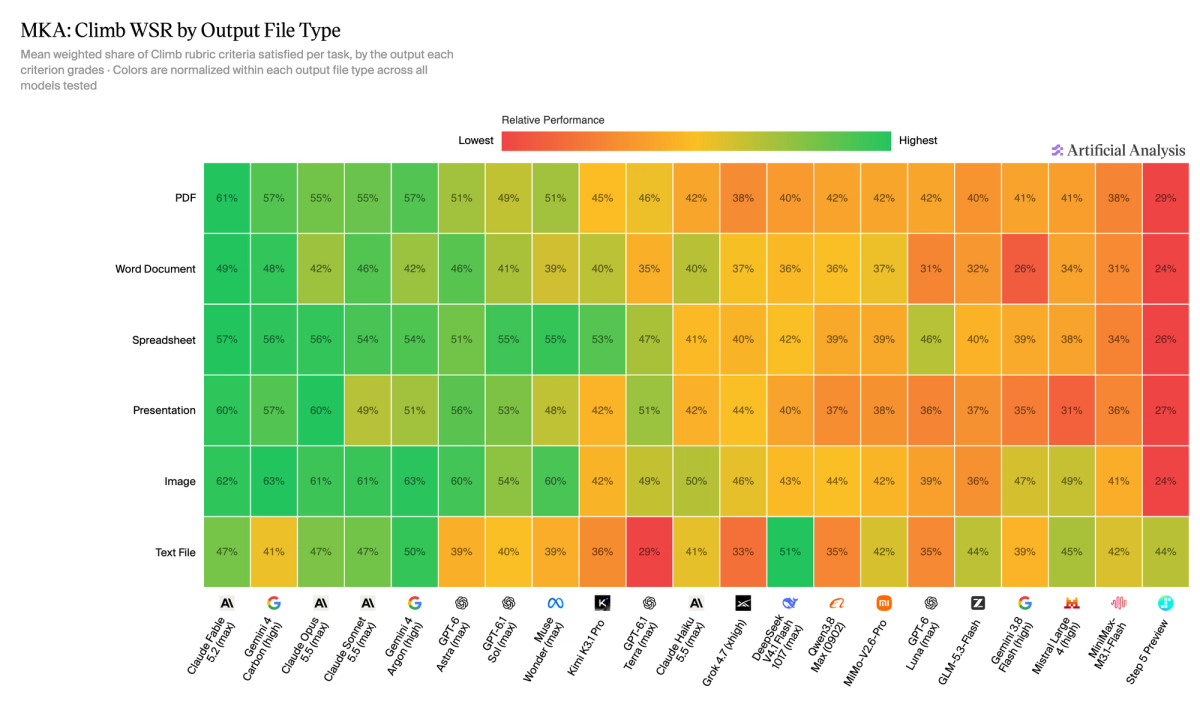
➤ MKA deliverables include six output file types and performance varies somewhat between them, though less than across verticals: On Climb WSR, Claude Fable 5.2 leads four file types (PDF, Word Document, narrowly Spreadsheet, and Presentation alongside Claude Opus 5.5 (max)), while Gemini 4 Argon (high) and Carbon (high) lead Image, and DeepSeek V4.1 Flash 1017 leads Text Files. Word Document and Text File output tasks are the hardest outputs: no model passes 52% on either
Thank you to the Google DeepMind team for their work building this benchmark and collaborating with us to bring it exclusively to Artificial Analysis!
Read the latest
Meta's Muse Ember is the cheapest model scoring 36 on the Intelligence Index
Meta's newest model Muse Ember scores 36 on the Artificial Analysis Intelligence Index, matching Claude Haiku 5.5 (max) at a third of the Cost per Task
November 9, 2026
Introducing the Artificial Analysis Decision Index v2
Introducing the Artificial Analysis Decision Index v2: a new proprietary evaluation, updated benchmarks, and a headline metric that rewards model calibration
November 8, 2026
VIALS-AA: different paths to scientific image reasoning
Independent VIALS-AA results, interactive agent traces, and an analysis of how models inspect scientific images.
November 6, 2026