June 3, 2026
Fun-Realtime-TTS: New Text to Speech model topping Artificial Analysis leaderboard
Alibaba's Fun-Realtime-TTS takes the #1 spot on the Artificial Analysis Speech Arena Leaderboard, surpassing Google's Gemini 3.1 Flash TTS and Inworld's Realtime TTS-2 Research Preview
Competition at the top of the TTS Arena is tighter than ever, with just 24 Elo points separating the top five models. Fun-Realtime-TTS takes the top spot with the highest Elo score on the leaderboard.
Alibaba's previous Fun-Realtime-TTS-Preview reached #7 on the leaderboard, making this Alibaba's first #1 model in the Artificial Analysis Speech Arena. Fun-Realtime-TTS is available via Alibaba Cloud with API access for developers.
Key takeaways:
➤ Quality: Fun-Realtime-TTS has an Elo score of 1,219 (+16/-16) based on 962 arena appearances, placing it ahead of Gemini 3.1 Flash TTS at 1,214, Inworld Realtime TTS-2 Research Preview at 1,209, and Cartesia Sonic 3.5 at 1,203
➤ Pricing: Fun-Realtime-TTS is priced at $27.59/1M characters, positioning it between Gemini 3.1 Flash TTS at $18.3/1M characters and Inworld Realtime TTS 1.5 Max at $35/1M characters, while remaining below Sonic 3.5 at $39/1M characters.
➤ Features: Fun-Realtime-TTS supports real-time speech generation with voice cloning, voice design, multilingual output, and support for regional accents and dialects.
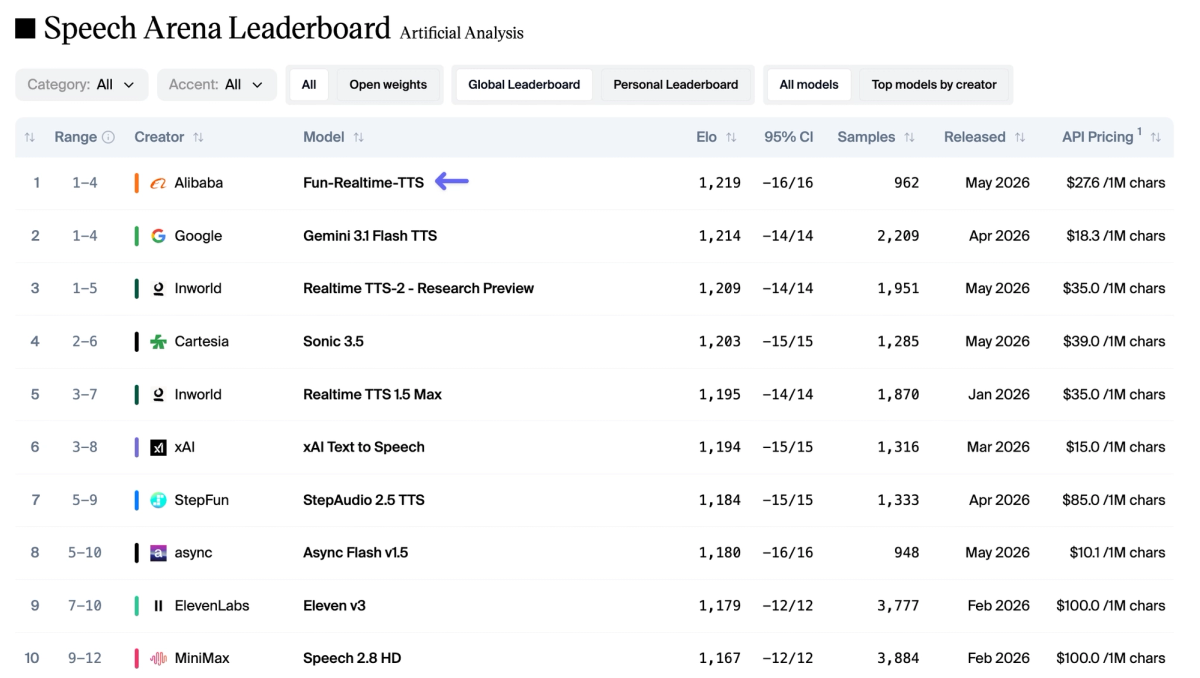
Fun-Realtime-TTS achieves the highest Elo score on the Speech Arena Leaderboard while remaining competitively priced at $27.6/1M characters, below several other frontier TTS models including Sonic 3.5 and Inworld Realtime TTS-2 Research Preview.
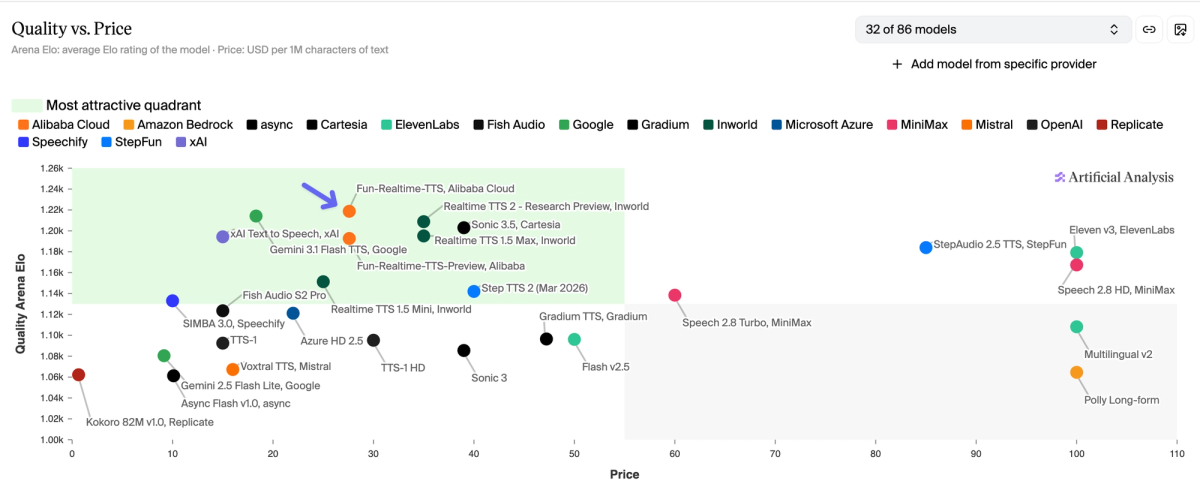
See the top models on the Artificial Analysis Speech leaderboard: https://artificialanalysis.ai/text-to-speech/leaderboard
Vote for models in the Speech Arena: https://artificialanalysis.ai/text-to-speech/arena
Explore sample clips from Fun-Realtime-TTS in the Speech Explorer: https://artificialanalysis.ai/text-to-speech/speech-explorer
Read the latest
Announcing AA-PersonalityBench: measuring how AI models communicate
AA-PersonalityBench measures the personality and communication style of AI models. A panel of LLM judges compares answers pairwise on 30 personality traits, which roll up into 8 personality indexes, alongside 21 communication characteristics measured directly from every response.
October 19, 2026
HealthBench and HealthBench Professional: Evaluating models in realistic health conversations
We’re launching leaderboards for HealthBench and HealthBench Professional, two benchmarks evaluating how AI models respond in realistic health conversations
October 19, 2026
Reflection has released Beam, their first model launch
Reflection’s first model, Beam, scores 30 on the Artificial Analysis Intelligence Index, placing it #2 among US open weights models
October 16, 2026