February 17, 2026
Claude Sonnet 4.6 - New leader in GDPval-AA
See model pageClaude Sonnet 4.6 is the new leader in GDPval-AA, slightly ahead of Anthropic’s Opus 4.6 on agentic performance of real-world knowledge work tasks less than two weeks after its launch
In our pre-release testing with @AnthropicAI, Sonnet 4.6 reached an ELO of 1633 using the adaptive thinking mode and max effort configurations that were introduced with Opus 4.6.
This represents a substantial improvement over Sonnet 4.5 with an expected win rate of over 85% for the latest model. To achieve this result, Sonnet 4.6 used more than 4x the total tokens than its predecessor, increasing from 58M tokens used by Sonnet 4.5 with extended thinking to 280M by Sonnet 4.6 with adaptive thinking. By comparison, Opus 4.6 with equivalent settings used 160M tokens, ~40% less.
This level of token usage pushed the total cost to run GDPval-AA just ahead of Opus 4.6, with both thinking and non-thinking variants slightly exceeding the cost of their Opus counterparts. While Sonnet 4.6 is now number 1 on the GDPval-AA leaderboard, it remains within the 95% confidence interval of Opus 4.6.
See below for a detailed breakdown and example outputs from our Sonnet 4.6 testing
We are currently running the Artificial Analysis Intelligence Index benchmarks on Claude Sonnet 4.6 progress - we will share an update on the model’s performance when these are complete.
GDPval-AA is our primary metric for general agentic performance, measuring the performance of models on knowledge work tasks from preparing presentations and data analysis through to video editing. Models use shell access and web browsing in an agentic loop through Stirrup, our open-source agentic reference harness.
The underlying GDPval dataset was released by OpenAI in September 2025 to capture self-contained work tasks across 44 occupations in 9 different sectors. It offers insight into the types of tasks models can complete that are relevant to today’s workforce, and is highly realistic due to the OpenAI team’s expert filtering and curation.
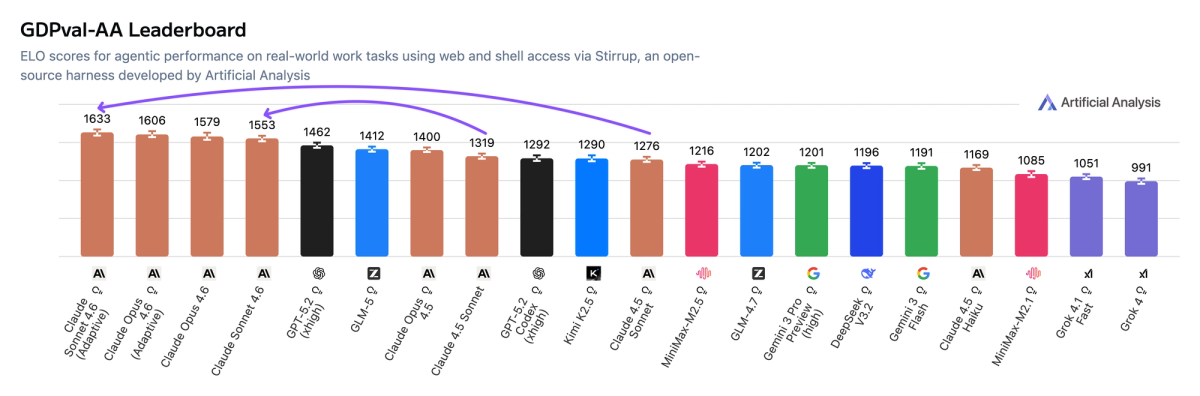 GDPval-AA Leaderboard
Check out additional analysis for this model on X: https://x.com/ArtificialAnlys/status/2023821893846135212?s=20 Explore the full suite of benchmarks at https://artificialanalysis.ai/
Read the latest
Announcing AA-PersonalityBench: measuring how AI models communicate
AA-PersonalityBench measures the personality and communication style of AI models. A panel of LLM judges compares answers pairwise on 30 personality traits, which roll up into 8 personality indexes, alongside 21 communication characteristics measured directly from every response.
October 19, 2026
HealthBench and HealthBench Professional: Evaluating models in realistic health conversations
We’re launching leaderboards for HealthBench and HealthBench Professional, two benchmarks evaluating how AI models respond in realistic health conversations
October 19, 2026
Reflection has released Beam, their first model launch
Reflection’s first model, Beam, scores 30 on the Artificial Analysis Intelligence Index, placing it #2 among US open weights models
October 16, 2026