September 22, 2026
Claude Opus 5.5 takes the top spot on the Artificial Analysis Intelligence Index, along with a 20% price cut and larger cache hit discount
See model pageClaude Opus 5.5 brings Anthropic to parity with GPT-6 Astra on evaluations like Terminal-Bench 4.0 and AutomationBench-AA, while extending Anthropic's lead in agentic knowledge work.
At max effort it scores 58 on the Artificial Analysis Intelligence Index, the highest score we have measured by several points. Anthropic has cut Opus pricing to $4/$20 per 1M input/output tokens (Opus 5: $5/$25) and cache reads from $0.50 to $0.20.
Key takeaways:
➤ Consistent strong performance, with leading scores on six of the ten Intelligence Index evaluations: Humanity's Last Exam 61.4% (previous best 59.1%, Claude Fable 5.1), SciCode 66.9% (63.1%, Fable 5.1), GDPval-AA v2.1, AA-Briefcase v1.1, AA-Omniscience and AutomationBench-AA. On Terminal-Bench 4.0 it scores 59.6%, level with the leader GPT-6 Astra (xhigh) and +11 points over Opus 5. It remains behind on CritPt, AA-LCR, and GDP.pdf
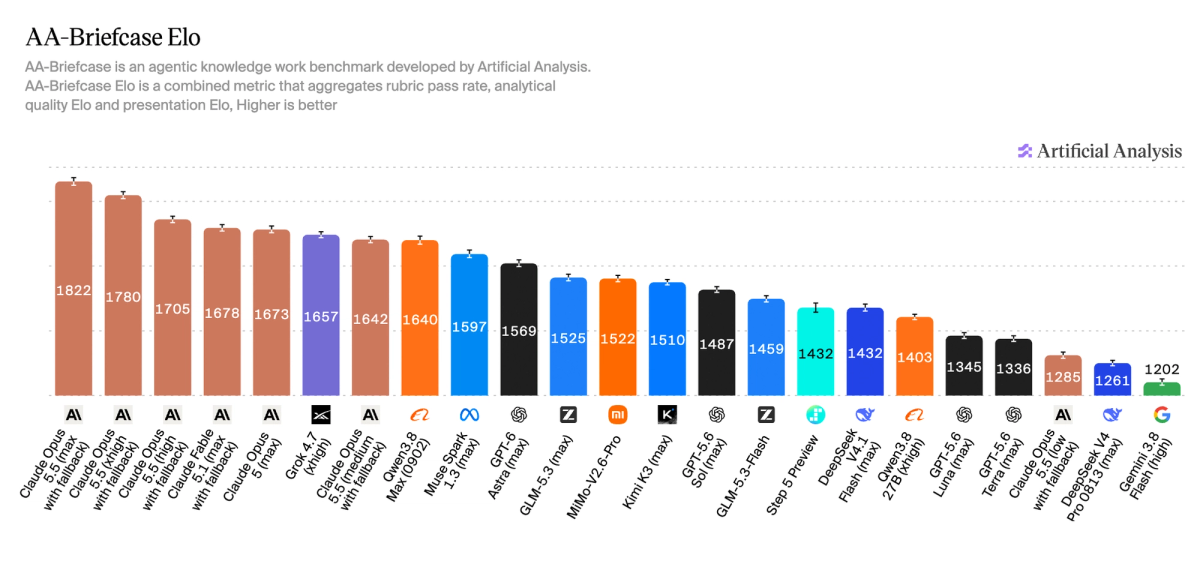
➤ Leads in agentic knowledge work: On AA-Briefcase, our private frontier knowledge work evaluation, it reaches an Elo of 1822. This is +143 over Fable 5.1, ahead on both analytical quality and presentation, and is the first time Anthropic has reached presentation quality surpassing GPT-5.6 Sol. This evaluation tests whether models can produce accurate and well-presented professional outputs using our open source reference agent harness, Stirrup
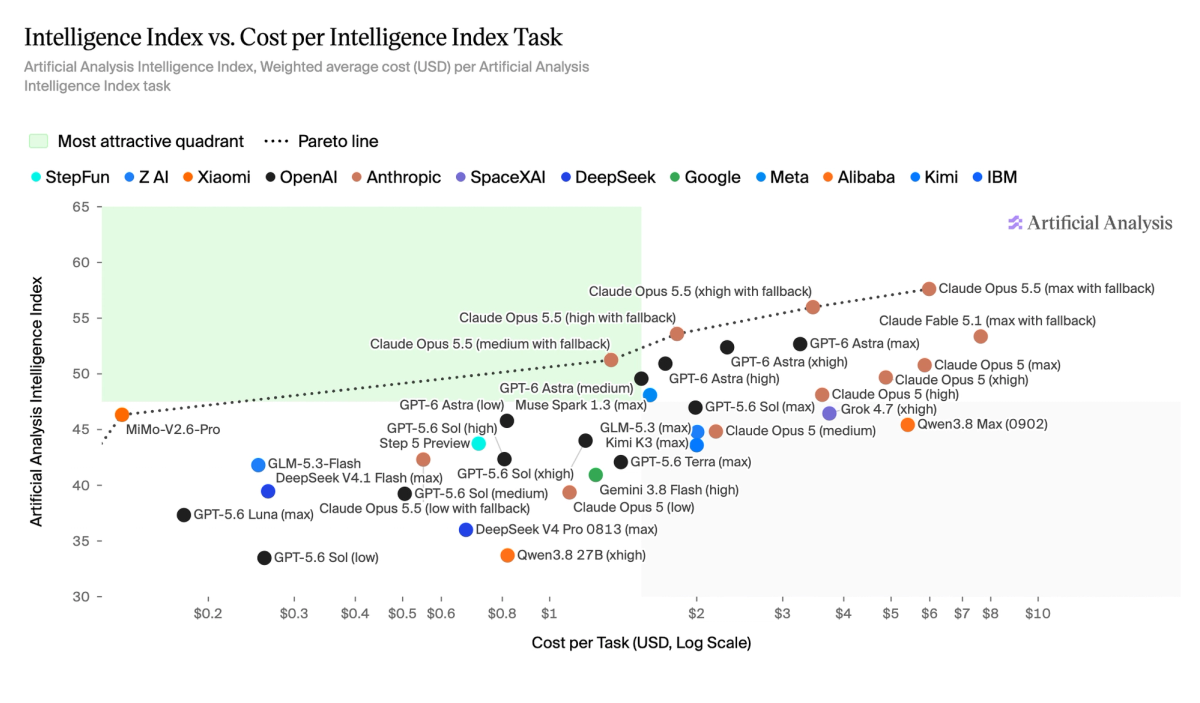
➤ Level with Opus 5 on cost per task despite 1.6x the output tokens: Opus 5.5 (max) uses ~119k output tokens per Intelligence Index task, against ~73k for Opus 5 (max), ~78k for Fable 5.1 (max) and ~27k for GPT-6 Astra (max)
➤ Four of five effort levels sit on the Intelligence vs Cost per Task frontier: Opus 5.5 max, xhigh, high, and medium all sit on the Pareto frontier, costing less or outperforming other models scoring 50+ (GPT-6 Astra, Claude Fable 5.1, and Claude Opus 5)
Other model details:
➤ Context window: 1 million token context with image and text input support, unchanged from Opus 5
➤ Pricing: $4/$20 per 1M input/output tokens, down 20% from $5/$25 for Opus 5. Cache writes $5 per 1M tokens for the 5 minute TTL, down from $6.25. Cache reads have been further discounted to $0.20 per 1M tokens, down 60% from Opus 5's $0.50. This is a 95% discount compared to uncached input pricing, up from 90% on previous Opus models
➤ Effort settings: Five effort settings (low, medium, high, xhigh, and max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled
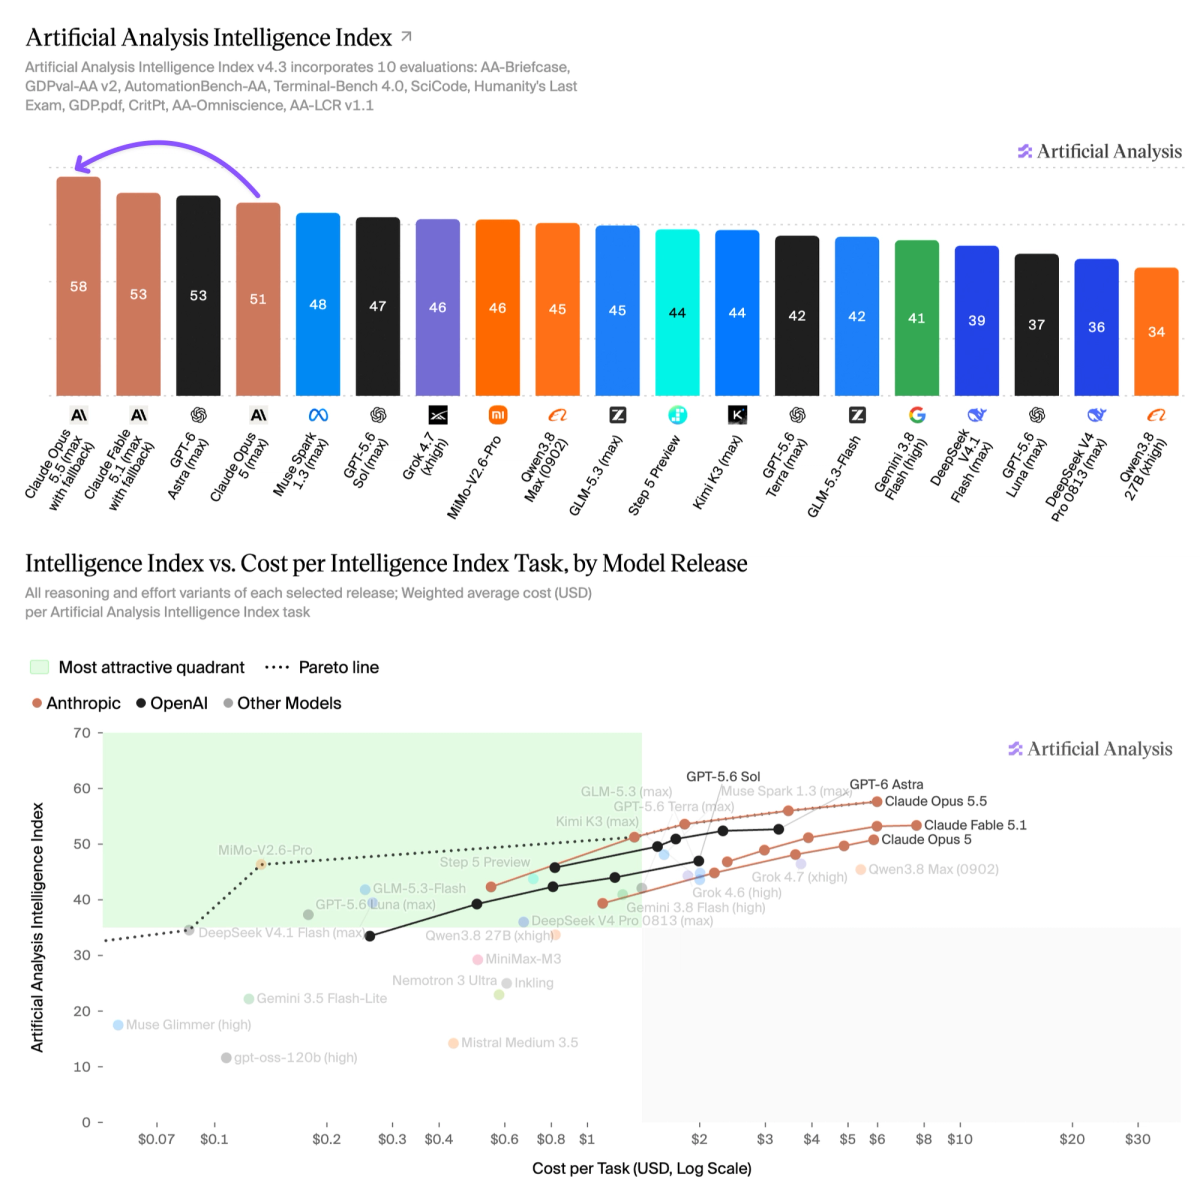
Four of Claude Opus 5.5's five effort levels sit on the Intelligence vs Cost per Task frontier: Opus 5.5 max, xhigh, high, and medium all sit on the Pareto frontier, costing less or outperforming other models scoring 50+.
Claude Opus 5.5 (max) is a top performer in agentic knowledge work. It leads AA-Briefcase v1.1 at 1,822 Elo (+143 over Fable 5.1) and GDPval-AA v2.1 at 1,846 Elo (+111 over Claude Fable 5.1, +138 over Claude Opus 5). On AA-Briefcase it leads across analytical quality and presentation sub-scores, and sits just behind Fable 5.1 for rubric-based scoring.
For further details and benchmarks of Claude Opus 5.5, see https://artificialanalysis.ai/models/claude-opus-5-5
Read the latest
Benchmarking Grok 4.7
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
September 21, 2026
Ant Group releases finance-focused Ling-3.0-flash-Fin
Ant Group has released their finance-focused flash model Ling-3.0-flash-Fin
September 16, 2026
Announcing Artificial Analysis Capability Indices v1.1
We are adding Agentic Tool Use sourced from AutomationBench-AA, AA-Briefcase to Agentic Knowledge Work, and GDP.pdf to Long-Context. Capability Indices v1.1 tunes each index more closely to the work it covers, combining slices of our core Intelligence Index v4.3 evaluations alongside specialized evaluations.
September 14, 2026