September 21, 2026
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
See model pageGrok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort.
Key takeaways:
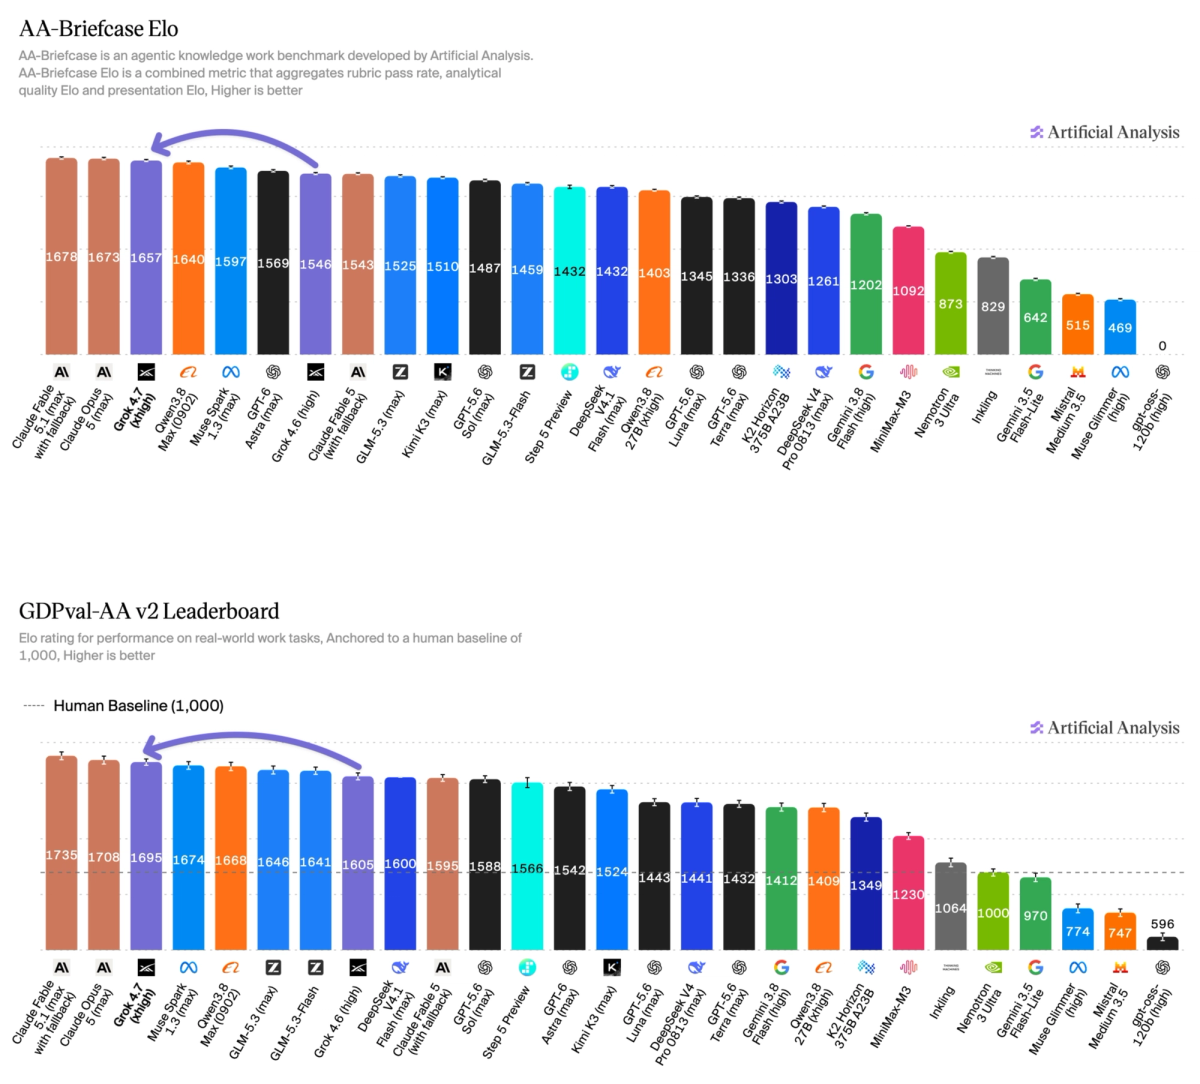
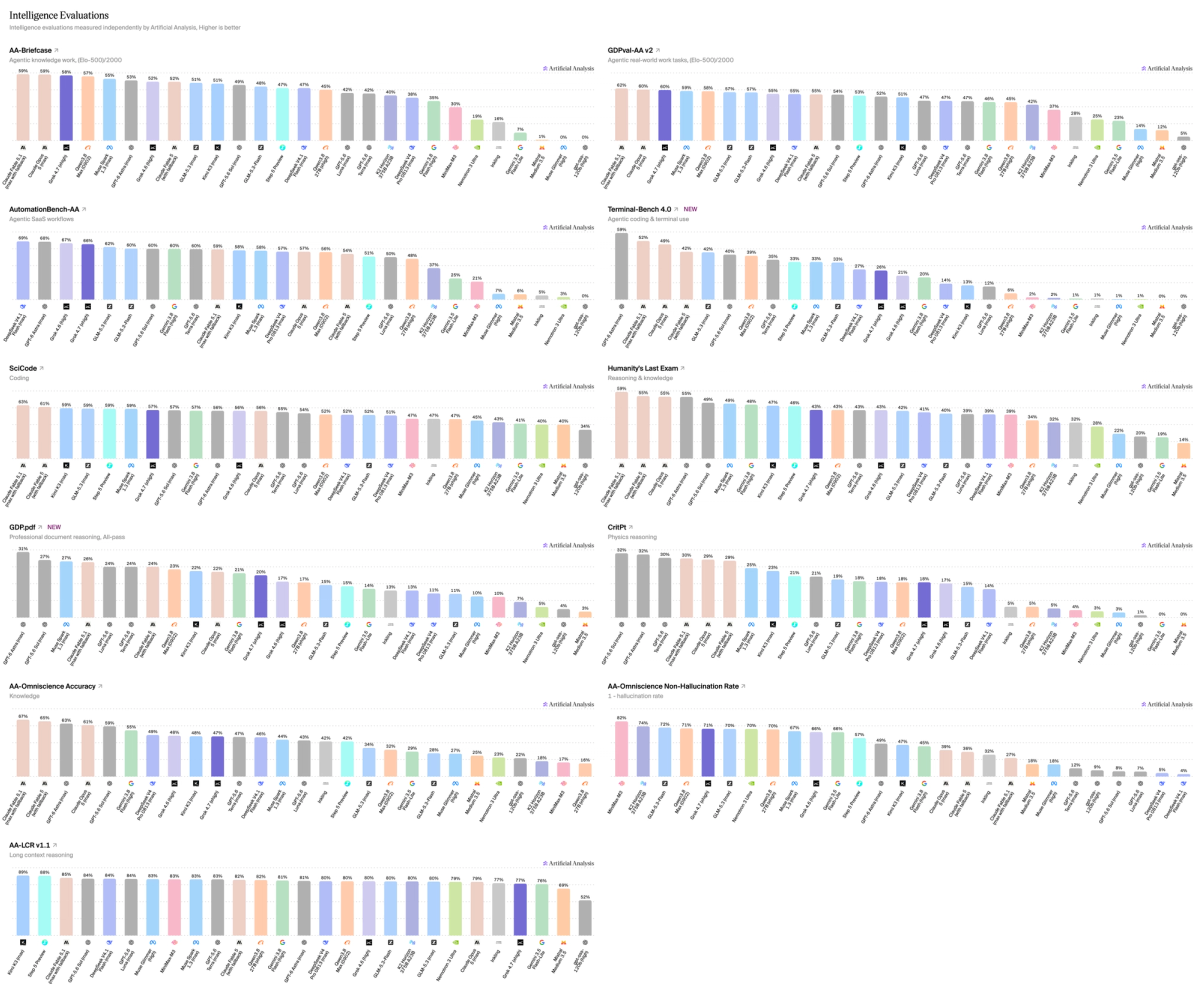
➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it just behind Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high).
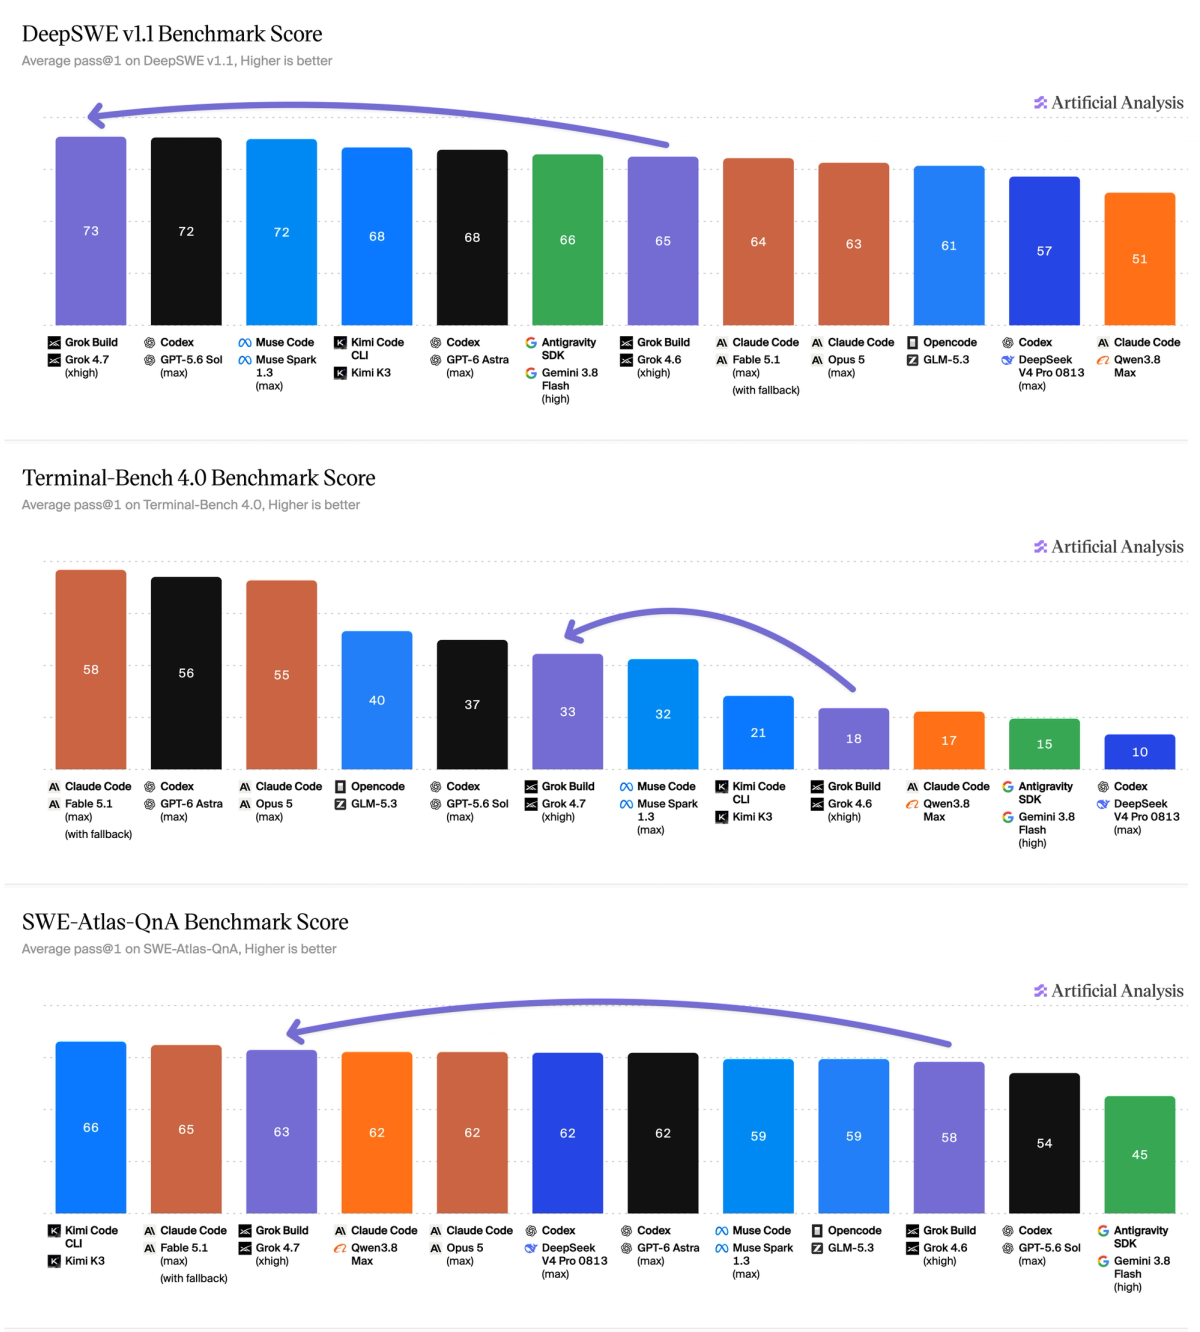
➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5.
➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6 (high) on the other Intelligence Index tasks. It improves on Terminal-Bench 4.0 (+4.5 percentage points) and GDP.pdf (+3.0 p.p.), with regressions on AA-LCR (-3.7 p.p.) and AutomationBench-AA (-1.1 p.p.).
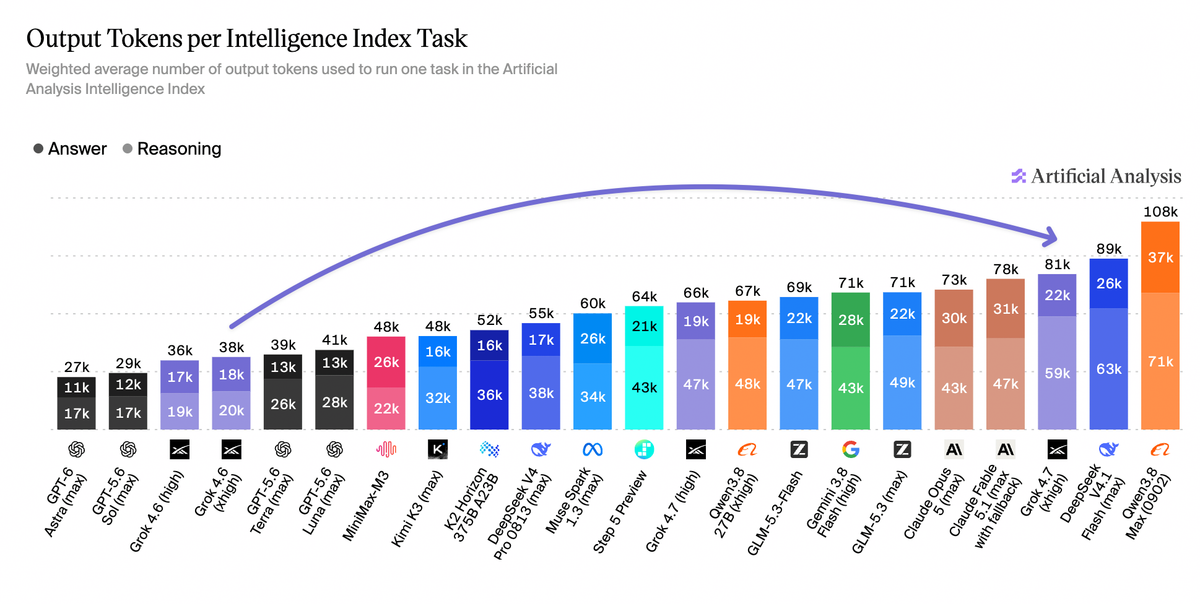
➤ High token use across tasks: Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) uses approximately 81k output tokens per Intelligence Index task, compared with 36k for Grok 4.6 (high) and 27k for GPT-6 Astra (max) - 125% and 196% more, respectively.
Other model details:
➤ Context window of 500k tokens, unchanged from Grok 4.6
➤ Pricing of $2/$6 per 1M input/output tokens with cache hits discounted to $0.50 per 1M tokens, matching Grok 4.6
➤ Configurable reasoning effort spans low to xhigh. Our evaluation uses xhigh.
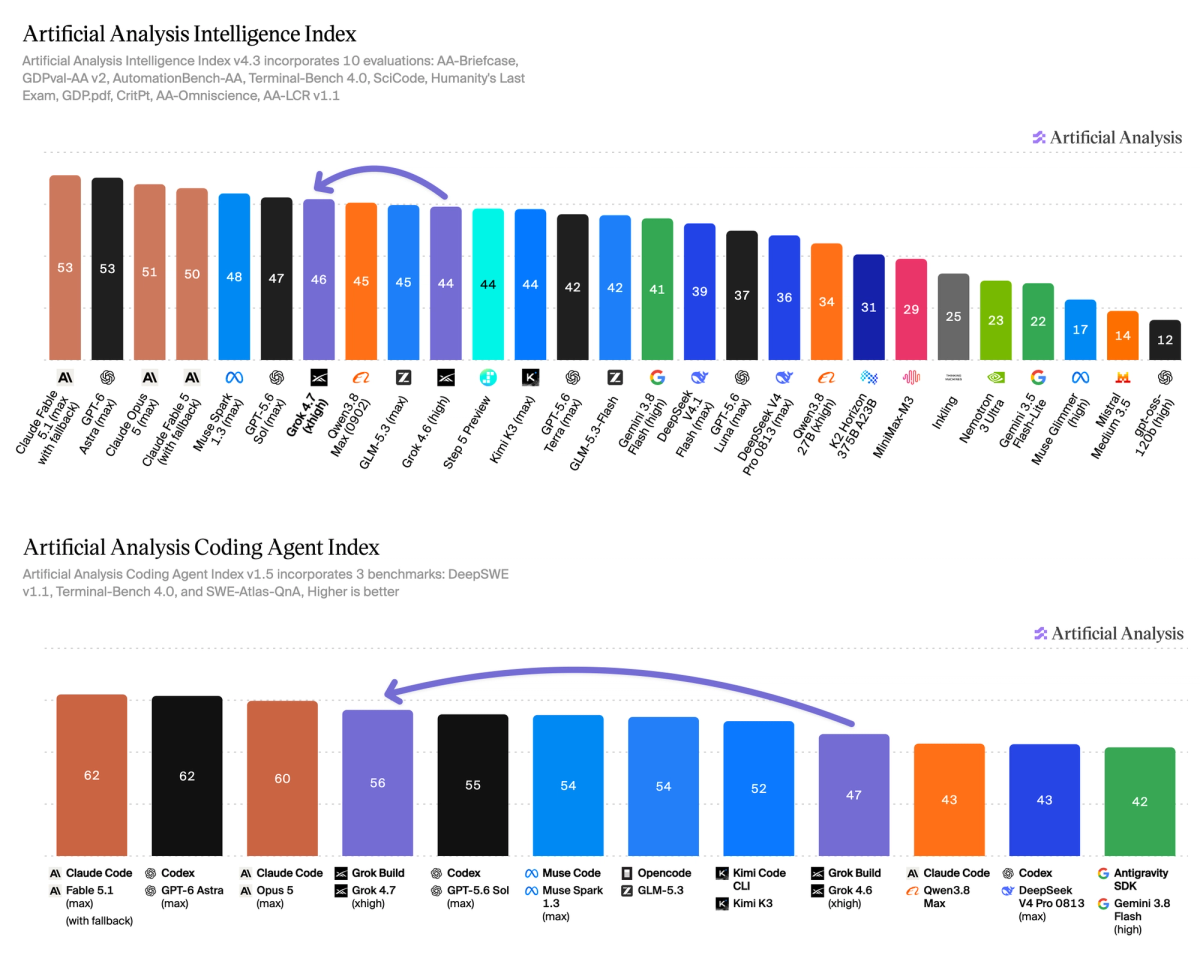
Grok 4.7 joins the frontier on agentic knowledge work tasks. On AA-Briefcase, which evaluates models on realistic professional work tasks, Grok 4.7 scores 1657 Elo, up 111 from Grok 4.6 (high) and placing it just behind Claude Opus 5 and Claude Fable 5.1.
Grok 4.7's improvement is led by analytical quality: it scores 1994 Elo for analytical quality and 1499 for presentation quality, compared with 1690 and 1519 respectively for Grok 4.6 (high). AA-Briefcase also checks whether submissions meet each task’s requirements, from completing the analysis to producing the requested deliverables.
On GDPval-AA, Grok 4.7 scores 1695 Elo, compared with 1605 for Grok 4.6 (high). These tasks require models to produce practical work products such as documents, spreadsheets and slides.
Grok Build with Grok 4.7 (xhigh) scores 56 on the Artificial Analysis Coding Agent Index, up from 47 with Grok 4.6 (xhigh).
It improves across all three components: DeepSWE v1.1 rises from 65% to 73%, Terminal-Bench 4.0 from 18% to 33%, and SWE-Atlas-QnA from 58% to 63%.
These results evaluate Grok with Grok Build, its first party coding agent. They are separate from the Intelligence Index results, which standardize the evaluation harness used across models.
Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) scores 46 on the Intelligence Index using 81k output tokens per task, more than double the 38k used by Grok 4.6 (xhigh). That compares with 60k for Muse Spark 1.3 (max) and 27k for GPT-6 Astra (max).
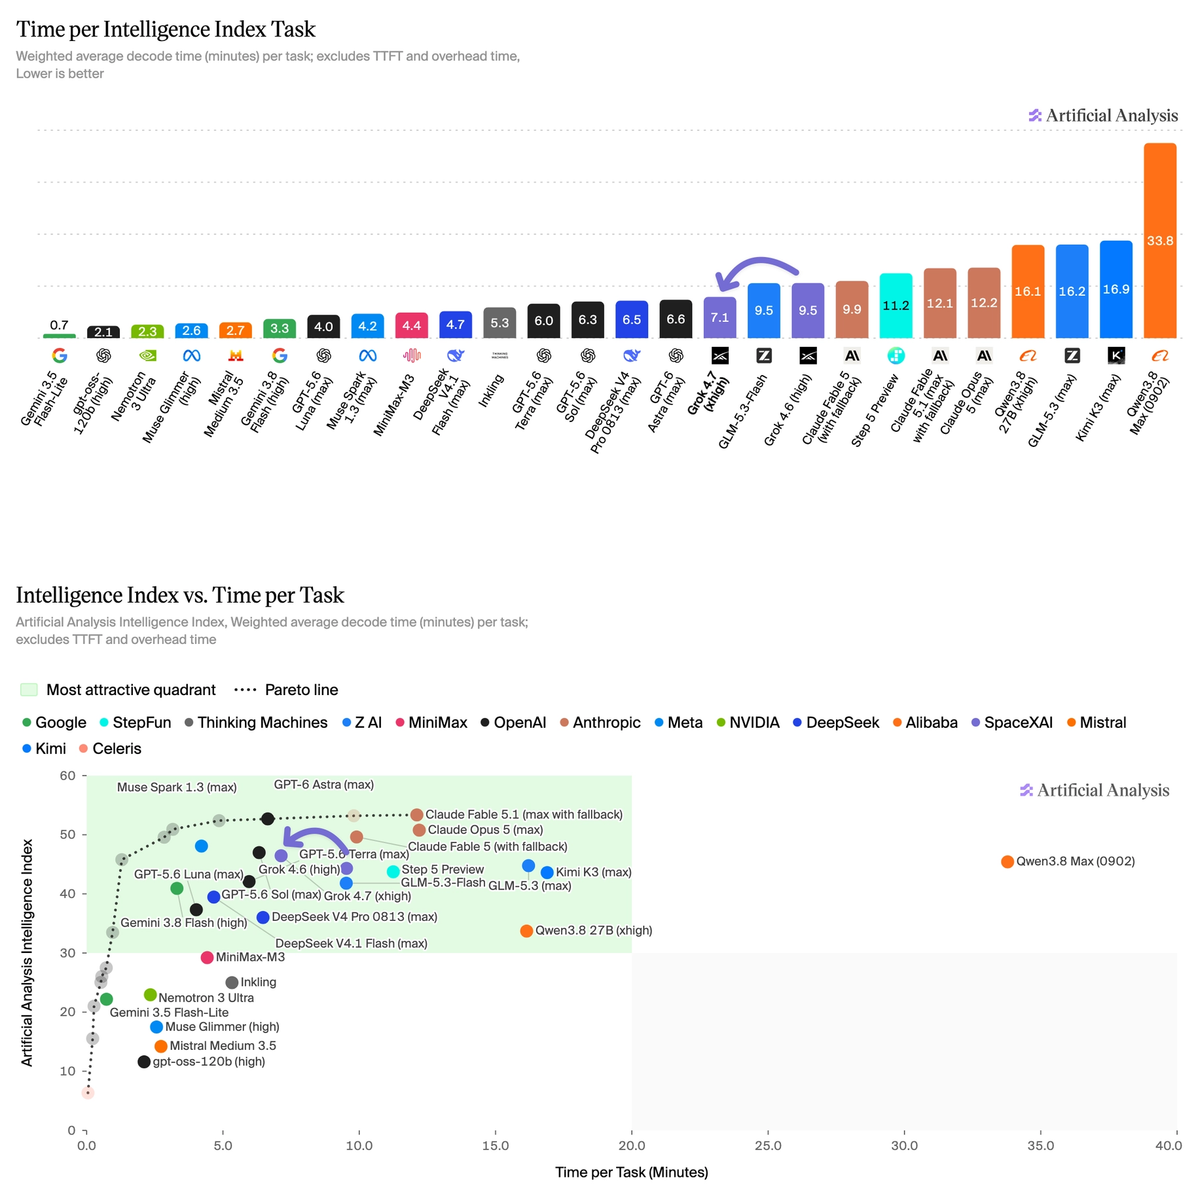
Our performance measurements put Grok 4.7's answer output speed at approximately 188 tokens/second for long prompts. Grok 4.7 averaged approximately 7.1 minutes per Intelligence Index task.
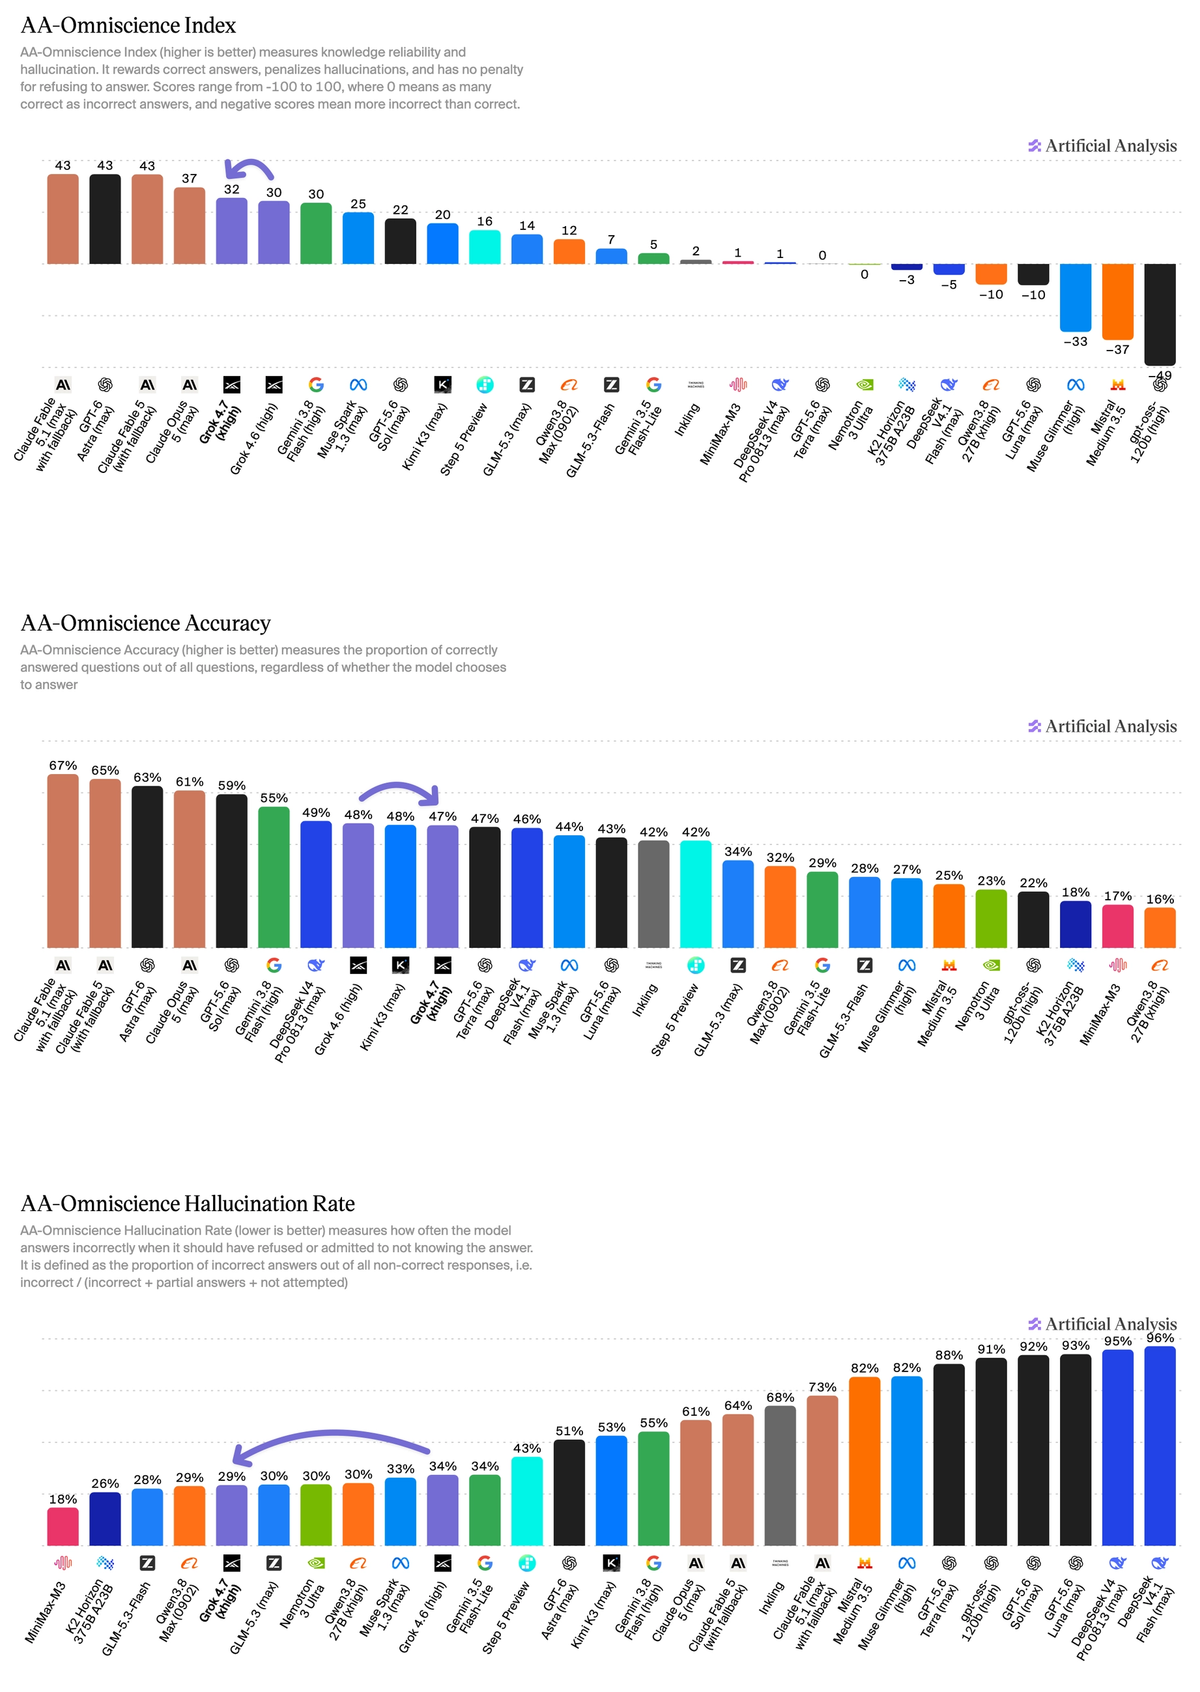
Grok 4.7 (xhigh) has a lower AA-Omniscience Hallucination Rate than Grok 4.6 (high): 29% versus 34%. Accuracy is broadly unchanged at 47% versus 48%, and overall AA-Omniscience Index improves from 30 to 32.
Full Intelligence Index evaluation breakdown for Grok 4.7 (xhigh), alongside Grok 4.6 (high) and other leading models.
Read the latest
Ant Group releases finance-focused Ling-3.0-flash-Fin
Ant Group has released their finance-focused flash model Ling-3.0-flash-Fin
September 16, 2026
Announcing Artificial Analysis Capability Indices v1.1
We are adding Agentic Tool Use sourced from AutomationBench-AA, AA-Briefcase to Agentic Knowledge Work, and GDP.pdf to Long-Context. Capability Indices v1.1 tunes each index more closely to the work it covers, combining slices of our core Intelligence Index v4.3 evaluations alongside specialized evaluations.
September 14, 2026
Benchmarking GPT-6 Astra
GPT-6 Astra ties leadership with Claude Fable 5.1 in both of our flagship Indices, at lower cost. Astra equals Fable 5.1 in the Intelligence Index at ~40% of the cost, and in the Coding Agent Index at ~60% of the cost.
September 9, 2026