August 24, 2026
Announcing the Speech Agent Arena: Compare Speech agents in real world conversations
Announcing our new Speech Agent Arena, evaluating Speech to Speech models on real-world scenarios to analyze conversational preference and task success rate
Existing Speech to Speech benchmarks cover reasoning, simulated agentic tasks, and conversational dynamics such as turn-taking and interruption handling. The Speech Agent Arena compares models and cascaded systems as humans complete real-world tasks, measuring conversational preference and successful tool use. This allows us to provide an evaluation which closer reflects real-world use, offering insight into which models users most prefer speaking with and how effectively those models support their requests.
Overview of the Speech Agent Arena and Task Success Rate
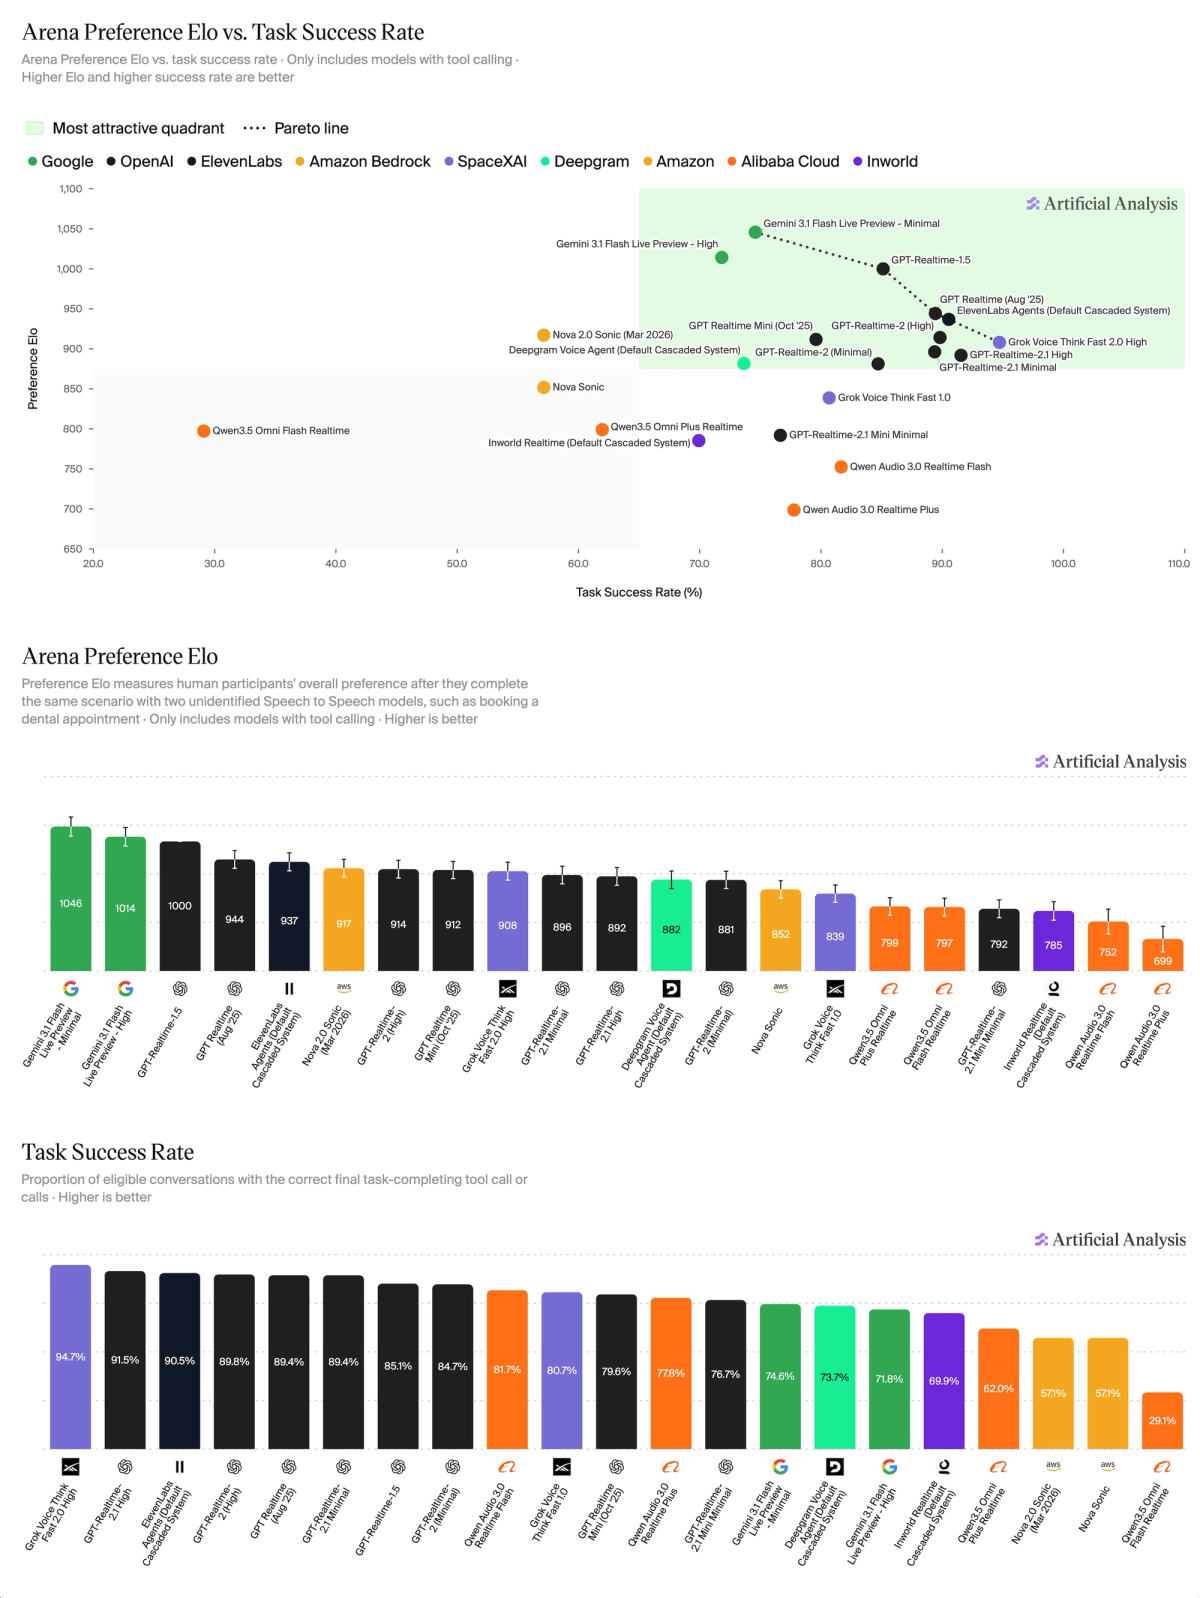
Human participants compare two hidden Speech to Speech models on the same assigned scenario, one of 15 agentic scenarios (tasks requiring tool calling, such as ordering takeout) or 20 non-agentic scenarios (tasks without tool calling, such as asking about opening hours). After separate live conversations with each model, participants select which they preferred, with these pairwise votes used to fit a Preference Elo score. For agentic scenarios, Task Success Rate is the share of eligible conversations (no participant deviations or unverifiable cases) where the model completed the requested action through the correct final tool call or calls.
For all but a New Patient Dental Booking example, scenario model prompts, tool schemas and participant instructions are currently private to reduce overfitting. Additionally, the Speech Agent Arena currently uses a qualified pool of paid, screened third-party participants to conduct and evaluate agent interactions.
Key results:
➤ Arena Preference Elo: GoogleAI Gemini 3.1 Flash Live Preview - Minimal leads at 1,046 Elo, followed by Gemini 3.1 Flash Live Preview - High at 1,014, OpenAI GPT-Realtime-1.5 at 1,000, GPT Realtime (Aug '25) at 944, and ElevenLabs Agents (default cascaded system of Scribe v2 Realtime / GPT-4o Mini / Eleven v3, with pre-registered tool schema) at 937. In reviewed conversations, highly preferred models tended to respond quickly, sound more natural and produce fewer unnatural sounds or audio artifacts
➤ Task Success Rate: SpaceXAI Grok Voice Think Fast 2.0 High leads at 94.7%, followed by OpenAI GPT-Realtime-2.1 High at 91.5%, ElevenLabs Agents (Default Cascaded System) at 90.5%, and GPT-Realtime-2 (High) at 89.8%, with GPT Realtime (Aug '25) and GPT-Realtime-2.1 Minimal tied at 89.4%. Gemini 3.1 Flash Live Preview - Minimal leads overall preference at 1,046 Elo but records a 74.6% Task Success Rate, showing that a preferred conversation does not always result in successful task completion - some conversations can sound as though the requested action was completed even when the required final tool call was unsuccessful
We are continuing to expand our coverage of native and cascaded Speech to Speech systems, and welcome feedback as we add more models, providers and scenarios.
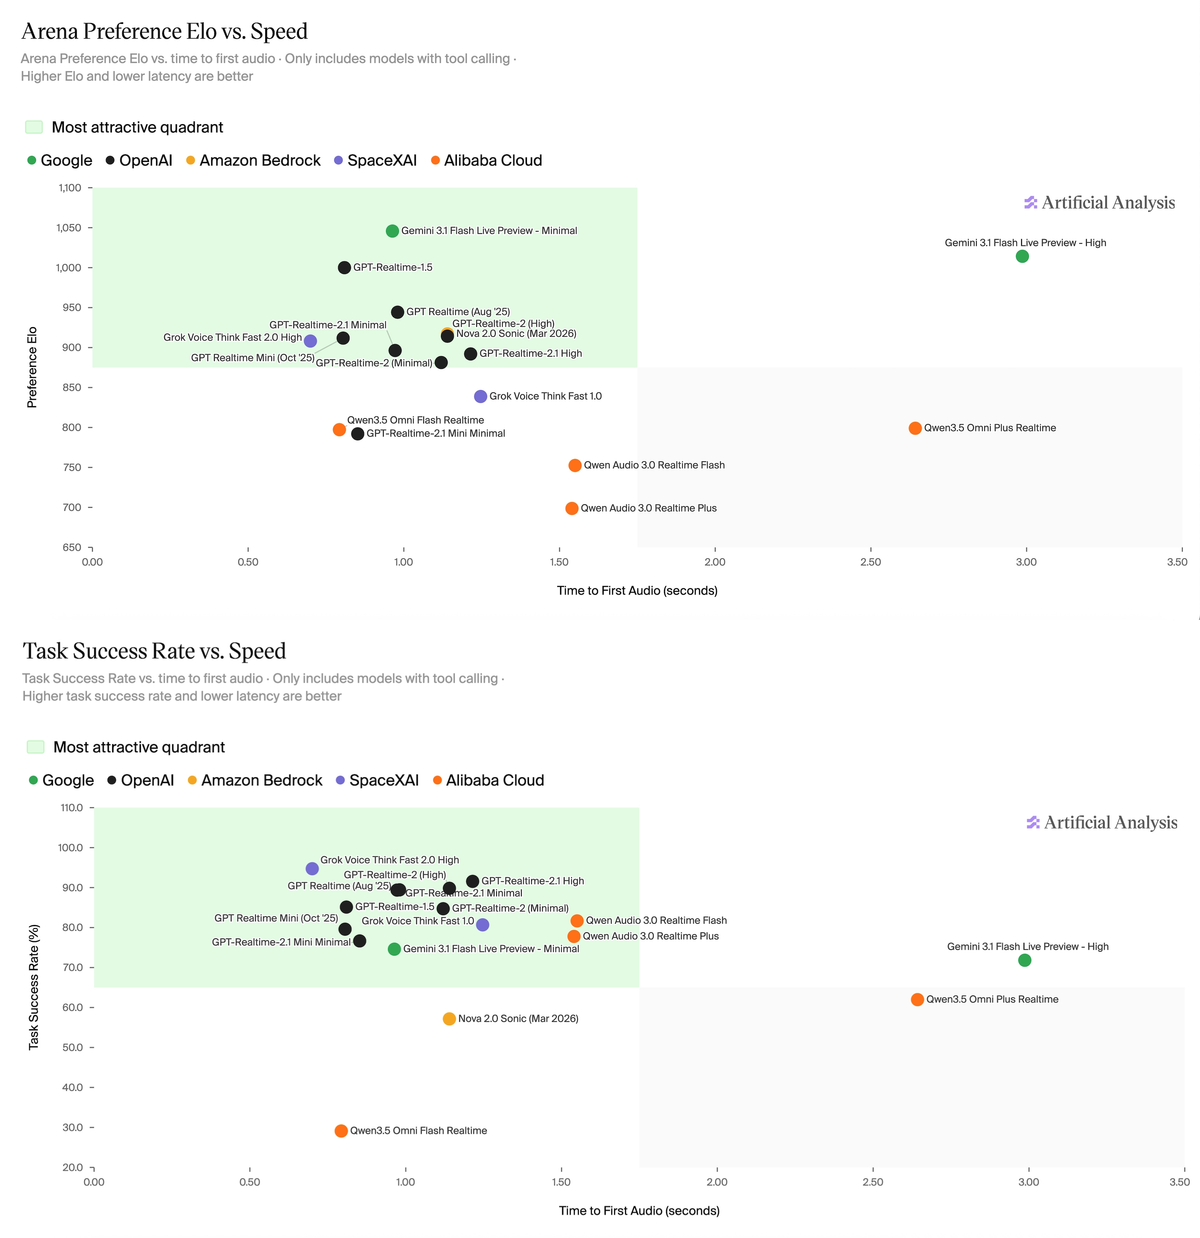
Overall Preference Elo generally increases as Time to First Audio (TTFA) decreases, suggesting that responsiveness contributes to a preferred conversational experience. Gemini 3.1 Flash Live Preview - Minimal leads overall preference at 1,046 Elo with a 0.96 second TTFA, compared with GPT-Realtime-2 (High) at 914 Elo and 1.14 seconds, and Qwen Audio 3.0 Realtime Plus at 699 Elo and 1.54 seconds.
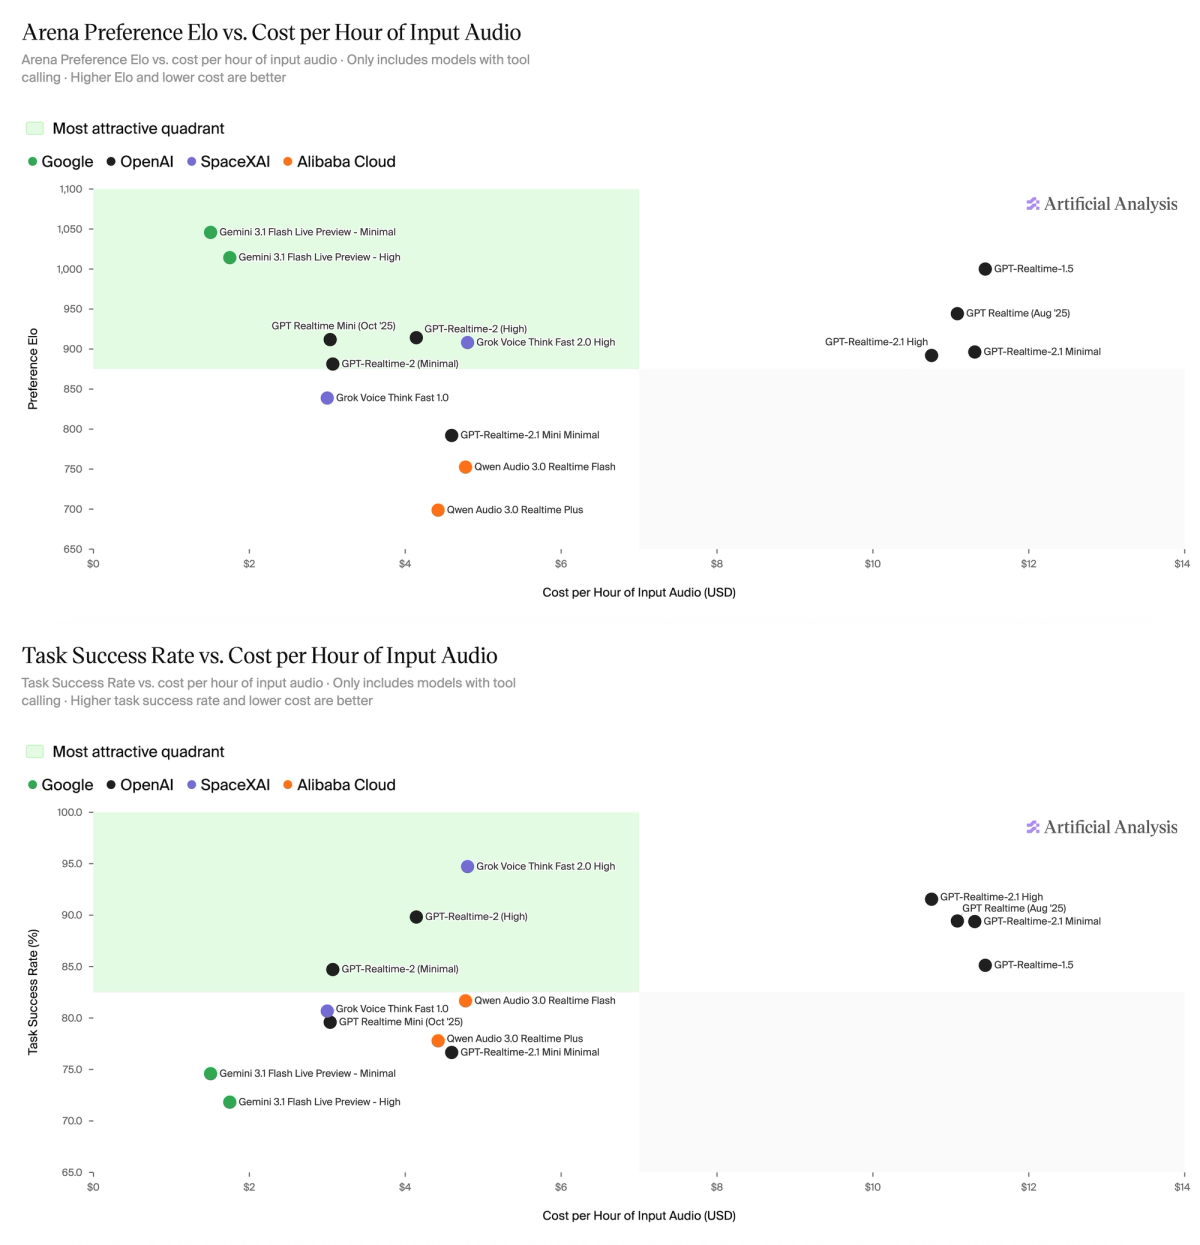
Models achieve strong conversational preference and task success at materially different price points. Gemini 3.1 Flash Live Preview - Minimal leads overall preference at 1,046 Elo with a cost of $1.50 per hour of input audio and a 74.6% Task Success Rate, while Grok Voice Think Fast 2.0 High leads Task Success Rate at 94.7% at $4.80 per hour. GPT-Realtime-2.1 High follows on task success at 91.5% and costs $10.75 per hour.
Compare Speech to Speech models across all benchmarks: https://artificialanalysis.ai/speech-to-speech
Speech Agent Arena leaderboard: https://artificialanalysis.ai/speech-to-speech/arena
Benchmark overview and example conversations: https://artificialanalysis.ai/speech-to-speech/arena/overview
Speech to Speech benchmarking methodology: https://artificialanalysis.ai/methodology/speech-to-speech-benchmarking
Read the latest
Kimi K3.1 Pro launches at 4th on the Intelligence Index and will lead open weights models
Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index and will lead open weights models
October 23, 2026
Announcing AA-PersonalityBench: measuring how AI models communicate
AA-PersonalityBench measures the personality and communication style of AI models. A panel of LLM judges compares answers pairwise on 30 personality traits, which roll up into 8 personality indexes, alongside 21 communication characteristics measured directly from every response.
October 19, 2026
HealthBench and HealthBench Professional: Evaluating models in realistic health conversations
We’re launching leaderboards for HealthBench and HealthBench Professional, two benchmarks evaluating how AI models respond in realistic health conversations
October 19, 2026