May 26, 2026
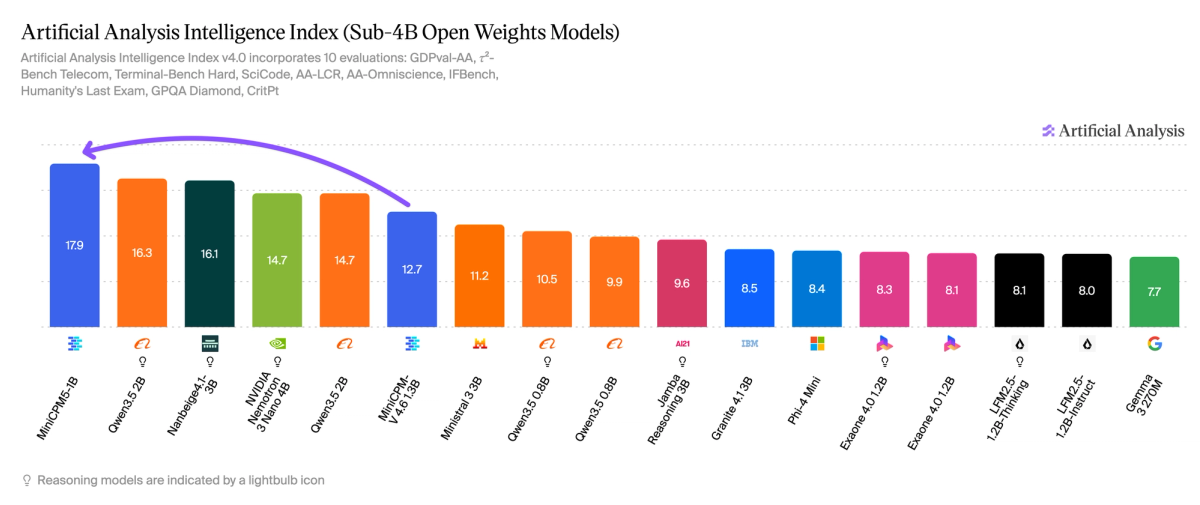
OpenBMB has released MiniCPM5-1B (Non-reasoning), the leading 1B open-weights model, scoring 17.9 on the Artificial Analysis Intelligence Index
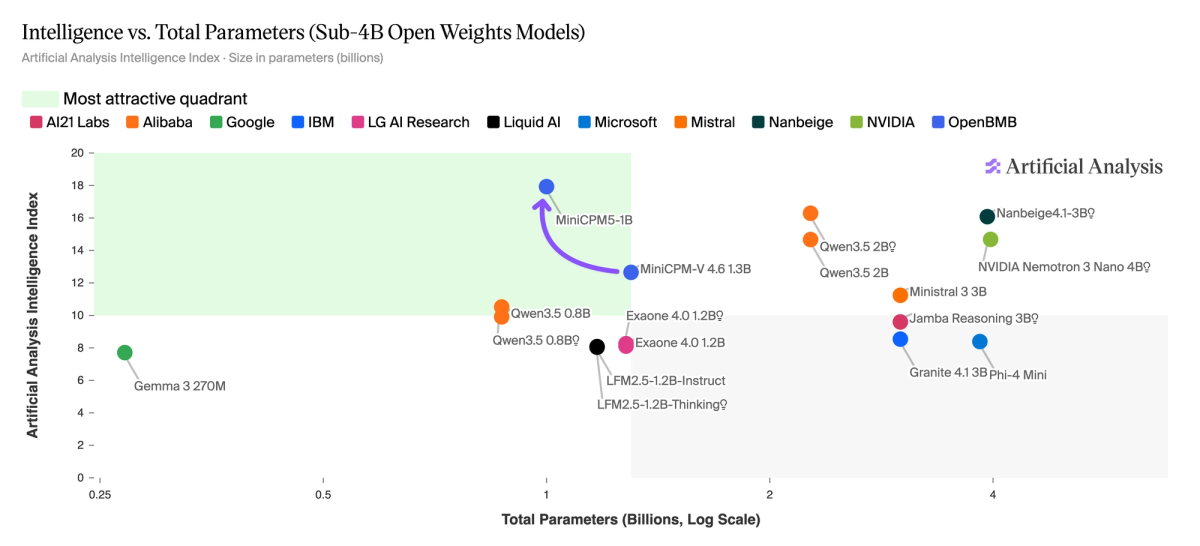
See model pageOpenBMB is a China-based lab jointly founded in 2022 by Tsinghua University's NLP Lab and ModelBest Inc. This release extends the open weights Pareto frontier for Intelligence vs. Parameters at the sub-2B scale. It sits almost 2 points ahead of the best-performing 2B open weights model, Alibaba's Qwen3.5 2B (Reasoning, 16.3), and 7 points ahead of Qwen3.5 0.8B (Reasoning, 10.5).
Unlike the recently released MiniCPM-V 4.6 1.3B Instruct, MiniCPM5-1B (Non-reasoning) does not support native multimodal input, and is text input and output only.
Key results:
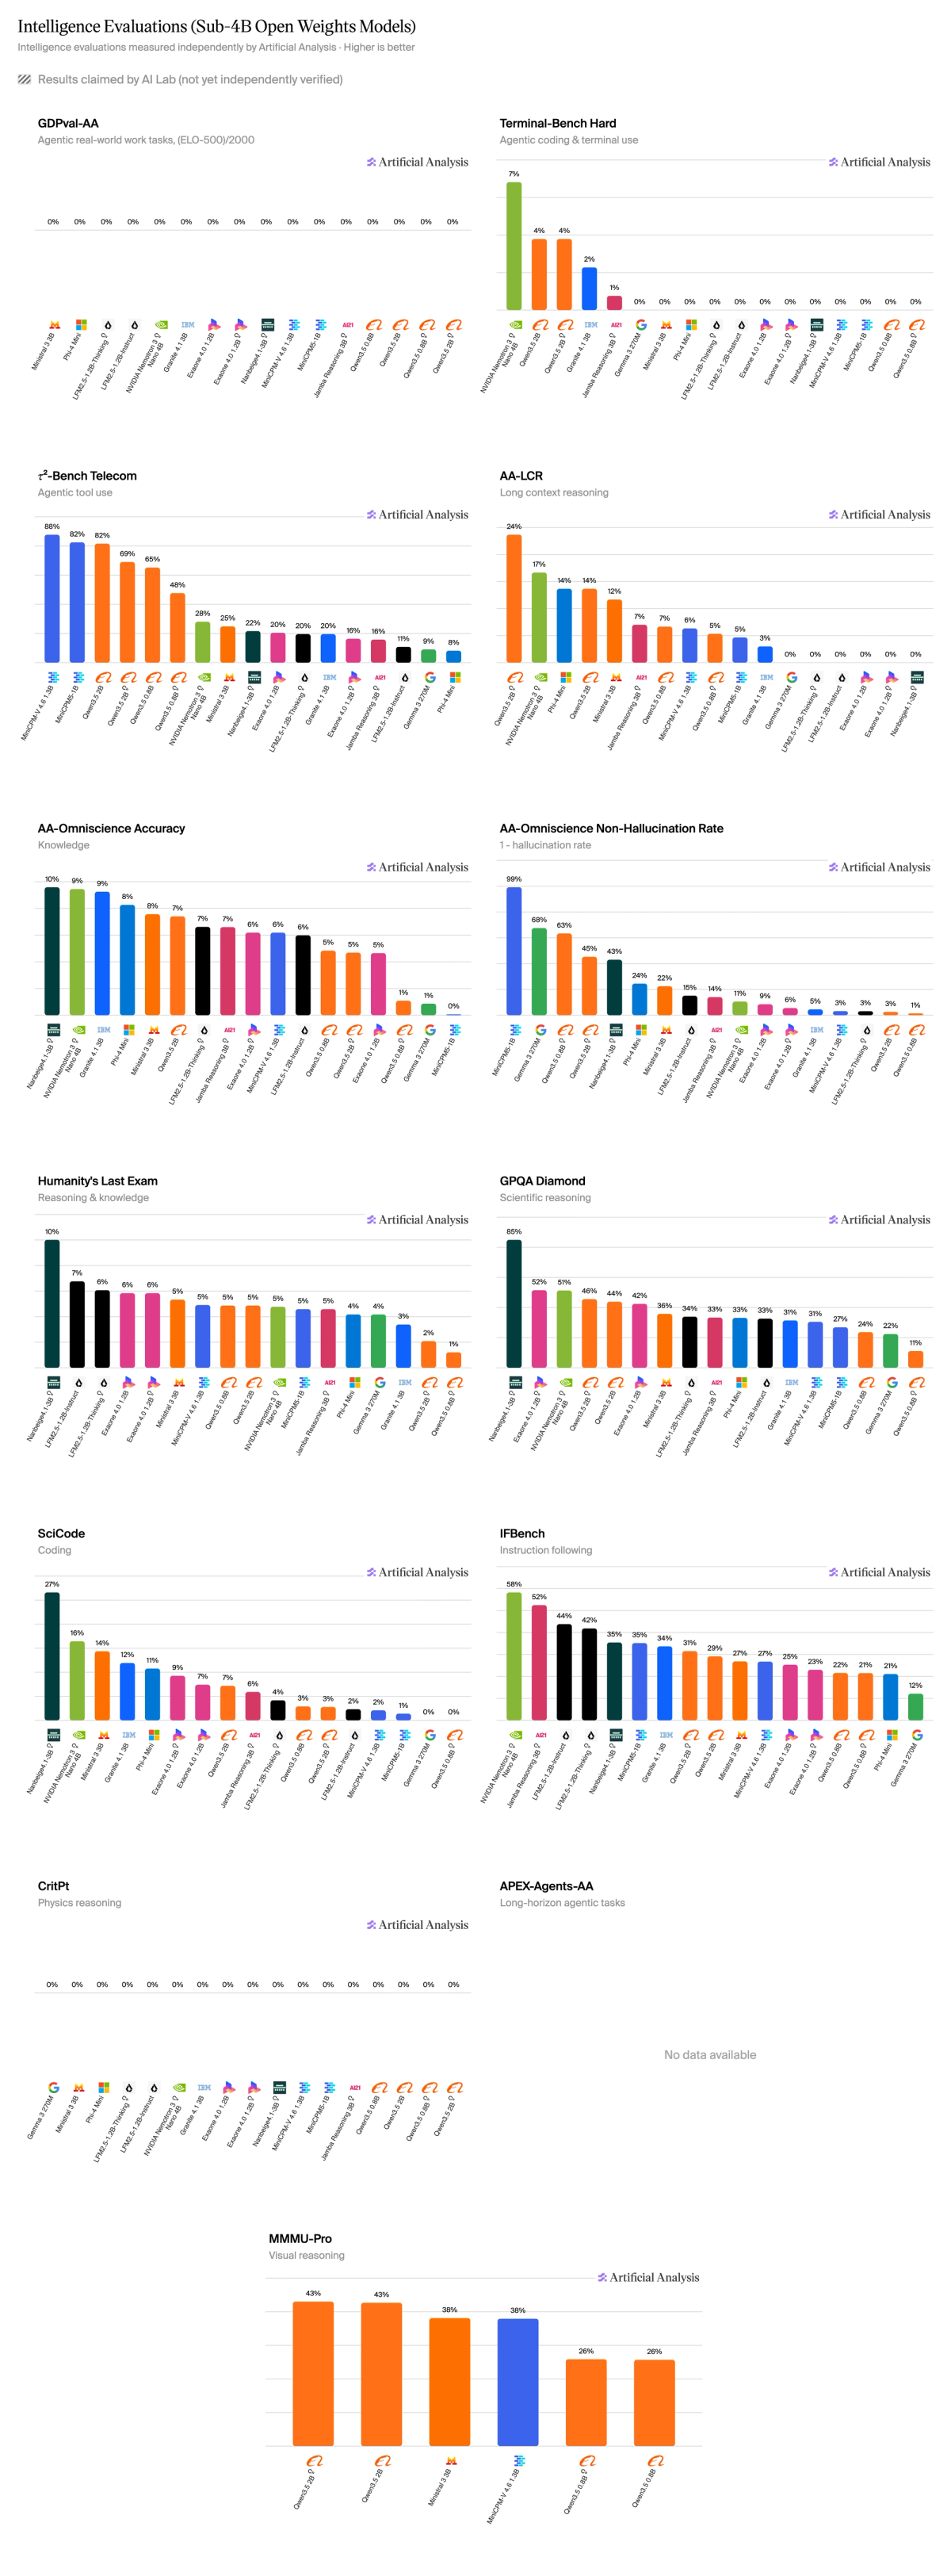
➤ MiniCPM5-1B scores 17.9 on the Artificial Analysis Intelligence Index, the highest of any open weights model at 1B parameters or below by 7.4 points. The next-most-intelligent open weights model at this scale is Qwen3.5 0.8B (Reasoning, 10.5). No other open weights model under 2B parameters has exceeded 15 on the Intelligence Index; its predecessor MiniCPM-V 4.6 1.3B sits at 12.7.
➤ MiniCPM5-1B extends the open weights Pareto frontier on both Intelligence vs. Total Parameters and Intelligence vs. Active Parameters at the sub-2B scale. It surpasses its predecessor MiniCPM-V 4.6 1.3B (12.7) by 5.3 points at ~23% fewer parameters, and beats Qwen3.5 2B (Reasoning, 16.3) by 1.6 points at less than half the parameter count.
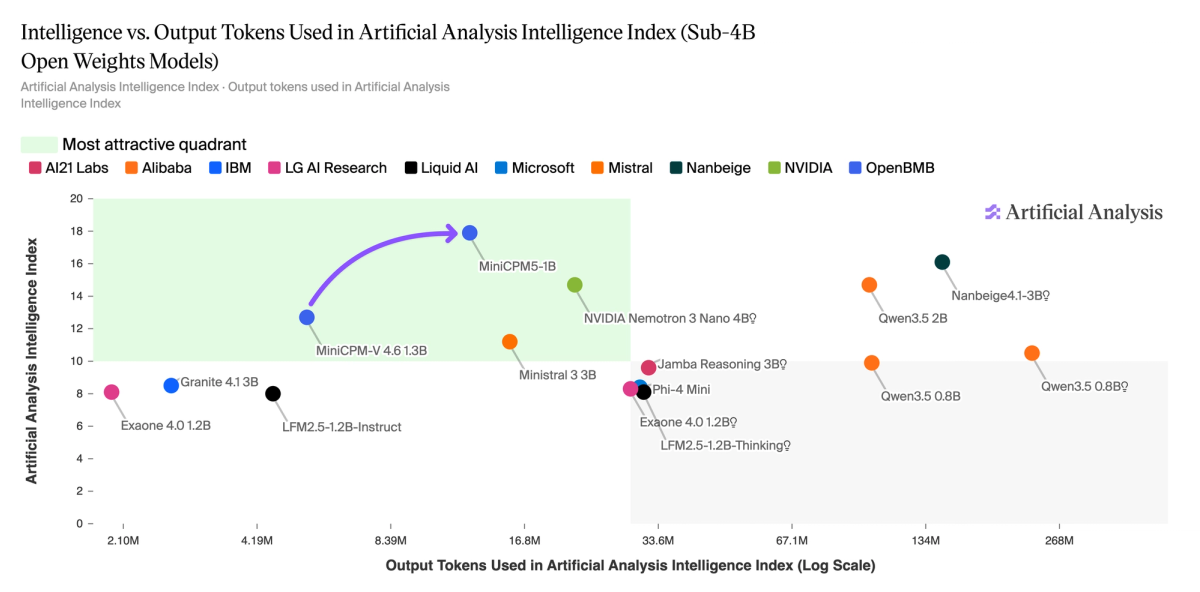
➤ MiniCPM5-1B is more token-efficient than the larger reasoning peers it surpasses, but uses more output tokens than its (also non-reasoning) predecessor MiniCPM-V 4.6 1.3B. It used 12.6M output tokens to run the Intelligence Index, ~31x fewer than Qwen3.5 2B (Reasoning, 389M) and ~8x fewer than Qwen3.5 2B (Non-reasoning, 100M), but ~2.3x more than MiniCPM-V 4.6 1.3B's 5.4M.
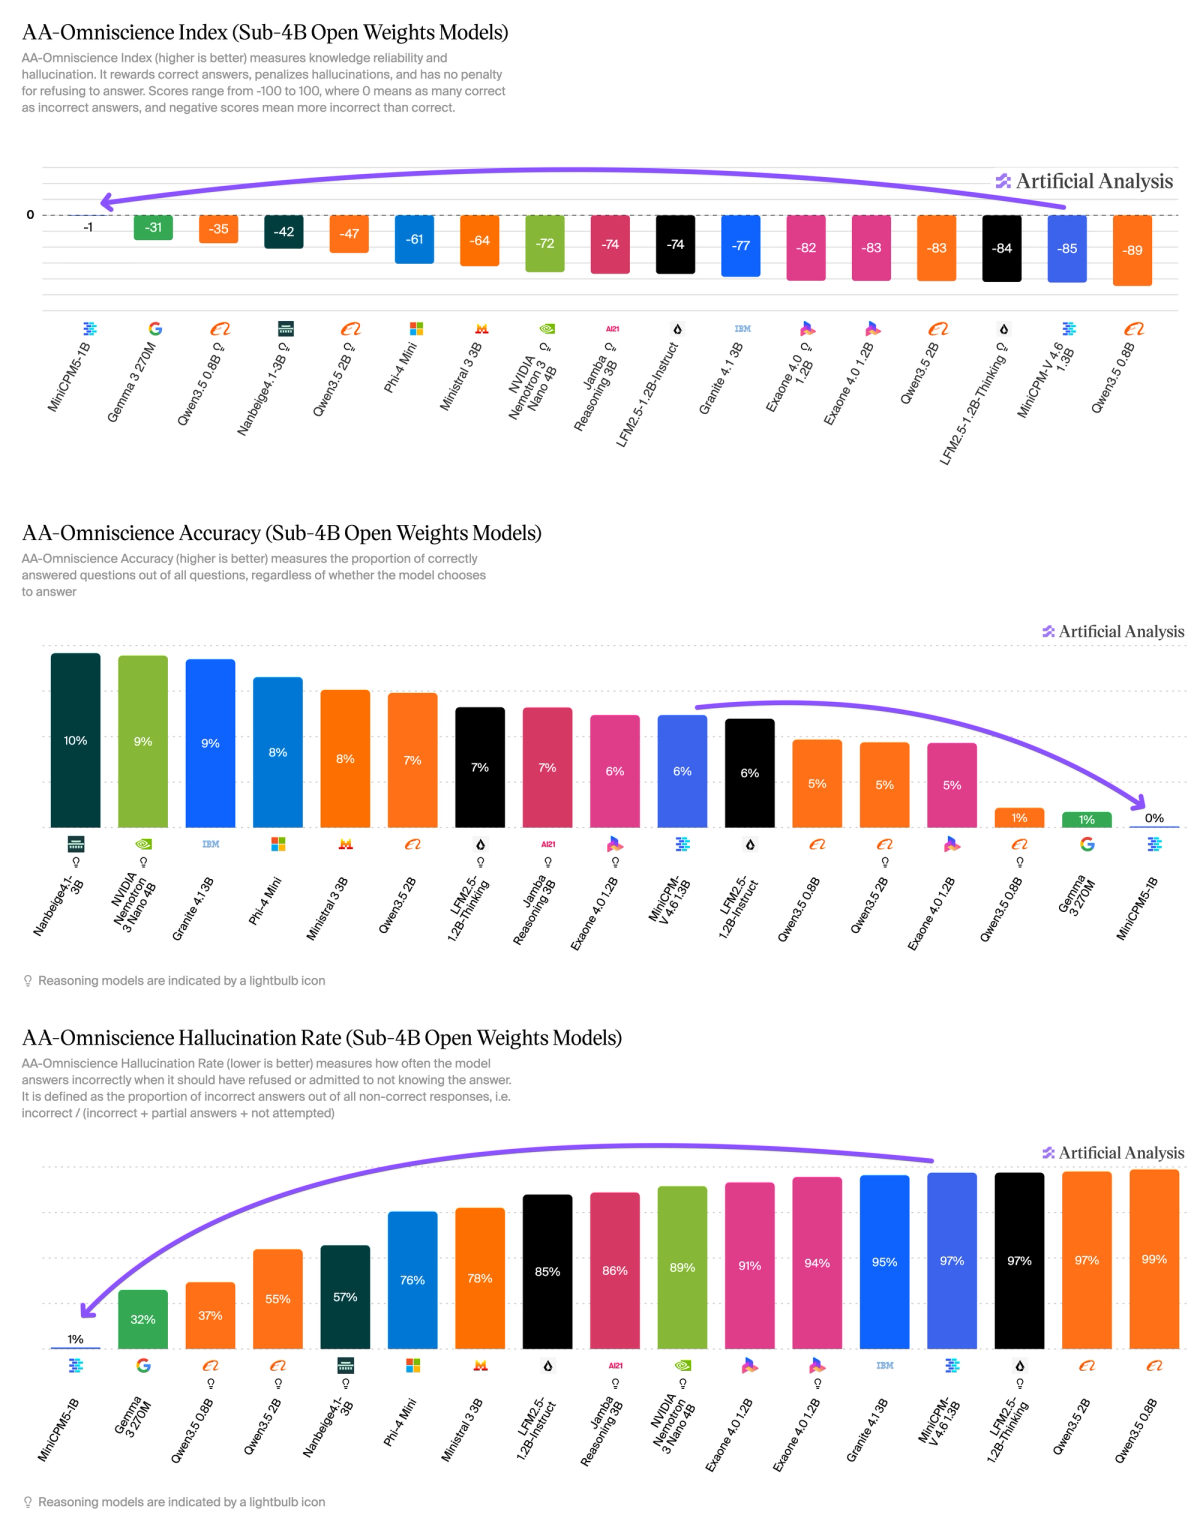
➤ AA-Omniscience score of -1 is the highest in its size class, earned by abstaining rather than hallucinating. MiniCPM5-1B declines to answer the vast majority of AA-Omniscience questions, avoiding the hallucination penalty that pulls sub-2B peers down to the -70 to -89 range (Qwen3.5 0.8B Non-reasoning at -89, MiniCPM-V 4.6 1.3B at -85, Exaone 4.0 1.2B Non-reasoning at -83). Choosing to abstain rather than guess is the more honest posture, and AA-Omniscience credits it positively.
Additional model details:
➤ Size: 1B total parameters (dense)
➤ Context window: 128K
➤ Modality: Text input and output only
➤ Precision: BF16
➤ License: Apache 2.0
➤ Providers: No confirmed providers upon release
MiniCPM5-1B extends the open weights Pareto frontier for Intelligence vs. Parameters at the sub-2B scale, scoring 17.9 with just 1B parameters, a 5-point increase in intelligence with an approximately 23% decrease in parameter count compared to OpenBMB's previous MiniCPM-V 4.6 1.3B.
MiniCPM5-1B uses up to 31x fewer output tokens than the larger reasoning peers it surpasses on the Intelligence Index. It used 12.6M output tokens to run the Intelligence Index, ~31x fewer than Qwen3.5 2B (Reasoning, 389M) and ~8x fewer than Qwen3.5 2B (Non-reasoning, 100M), though ~2.3x more than its predecessor MiniCPM-V 4.6 1.3B's 5.4M.
MiniCPM5-1B scores -1 on AA-Omniscience, the highest in its size class, earned by abstaining rather than hallucinating. Sub-2B peers typically attempt a large proportion of questions and hallucinate at high rates, resulting in low AA-Omniscience scores; MiniCPM5-1B declines the majority of questions, an honest posture that AA-Omniscience credits positively.
The full Artificial Analysis Intelligence Index per-evaluation breakdown:
Read the latest

Artificial Analysis Decision Index v1.0
The Artificial Analysis Decision Index benchmarks decision models, a new category of models that answer structured decisions in a single call with a probability for each option. Version 1.0 combines four evaluations across classification, tool calling, knowledge, hallucination, and reasoning.
October 13, 2026

Announcing AA-3D: a benchmark for AI models building interactive 3D experiences
AA-3D is a new benchmark of how well AI models build interactive 3D experiences. Each model turns a written brief into a working three.js scene in an offline sandbox, and our recruited panel compares the scenes in blind pairwise votes.
October 12, 2026
Announcing FrontierCode on Artificial Analysis: can AI models write code maintainers would merge?
Cognition's FrontierCode 1.1 tests whether AI models make code changes that maintainers of real open source repositories would merge. Leading models still fail more than 40% of the time.
October 12, 2026