September 14, 2026
Announcing Artificial Analysis Capability Indices v1.1
We are updating the Capability Indices v1.1 with stronger domain tuning, combining slices of core Intelligence Index v4.3 evaluations alongside specialized evaluations.
The Capability Indices map tasks from O*NET occupations to the benchmarks that represent them, weighting each benchmark by how often its capability appears across tasks. Capability Indices v1.1 incorporates updates to Intelligence Index v4.2 and v4.3, slicing by domain when available.
Changelog
| Index | Added | Deleted |
|---|---|---|
| Finance & Accounting | Agentic Tool Use (AutomationBench-AA, Finance) Agentic Knowledge Work (AA-Briefcase) Long-Context (GDP.pdf) | Agentic Customer Interaction (𝜏³-Banking) |
| Strategy & Ops | Agentic Tool Use (AutomationBench-AA, Operations) Agentic Knowledge Work (AA-Briefcase) Long-Context (GDP.pdf) | Agentic Customer Interaction (𝜏³-Banking) |
| Legal | Agentic Tool Use (AutomationBench-AA, Operations and Support) Agentic Knowledge Work (AA-Briefcase) Long-Context (GDP.pdf) | Agentic Customer Interaction (𝜏³-Banking) |
| Healthcare & Medical | Agentic Tool Use (AutomationBench-AA, Operations and Support) Long-Context Reasoning (MLCR-AA) Agentic Knowledge Work (AA-Briefcase) | Agentic Customer Interaction (𝜏³-Banking) |
| Engineering | Agentic Terminal Use (Terminal-Bench v4.0) Agentic Knowledge Work (AA-Briefcase) | Agentic Terminal Use (Terminal-Bench v2.1) Reasoning (GPQA Diamond) |
| Economics | Agentic Knowledge Work (AA-Briefcase) | - |
Changes by Index
Finance & Accounting
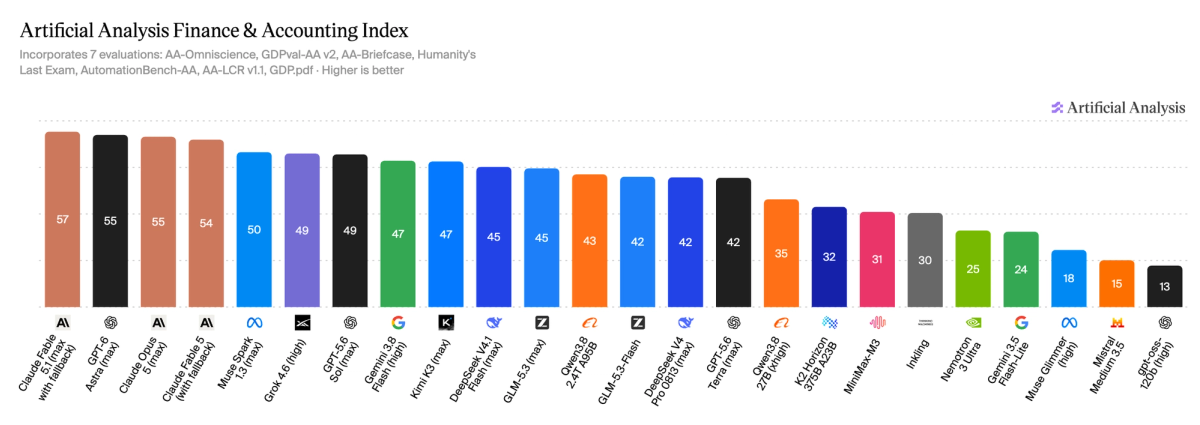
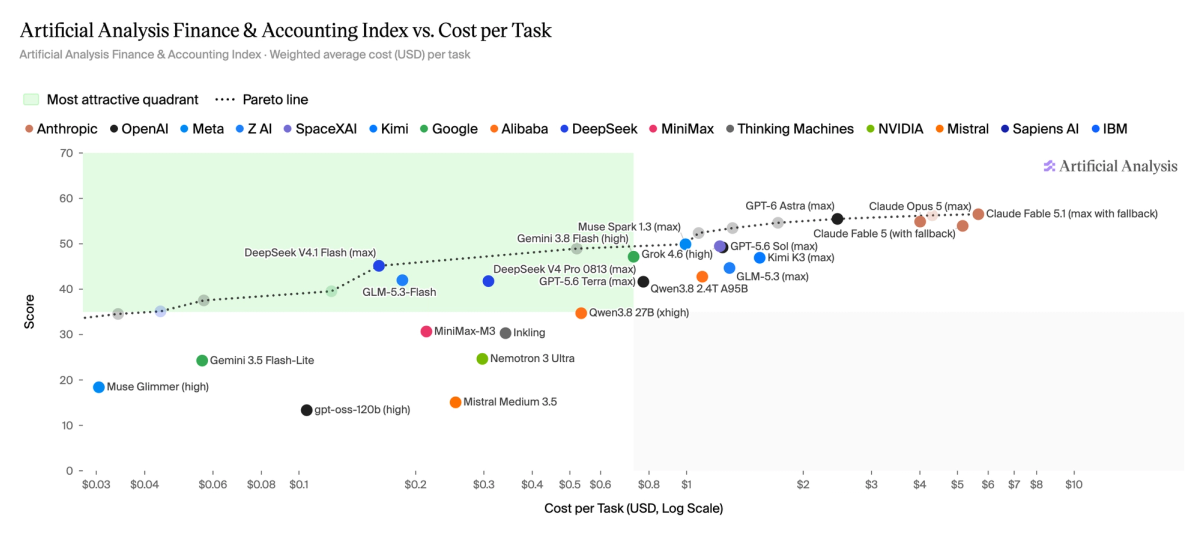
Agentic Tool Use added, sourced from the Finance slice of AutomationBench-AA. Agentic Customer Interaction removed. AA-Briefcase added alongside GDPval-AA v2 in Agentic Knowledge Work, and GDP.pdf added alongside LCR in Long-Context.
| Capability | Evaluations | v1.0 | v1.1 |
|---|---|---|---|
| Business Knowledge | AA-Omniscience | 30% | 30% |
| Agentic Knowledge Work | GDPval-AA v2, AA-Briefcase | 30% | 30% |
| Reasoning | HLE | 20% | 20% |
| Agentic Tool Use | AutomationBench-AA | 0% | 10% |
| Long-Context | LCR, GDP.pdf | 5% | 5% |
| Non-Hallucination | AA-Omniscience | 5% | 5% |
Strategy & Ops
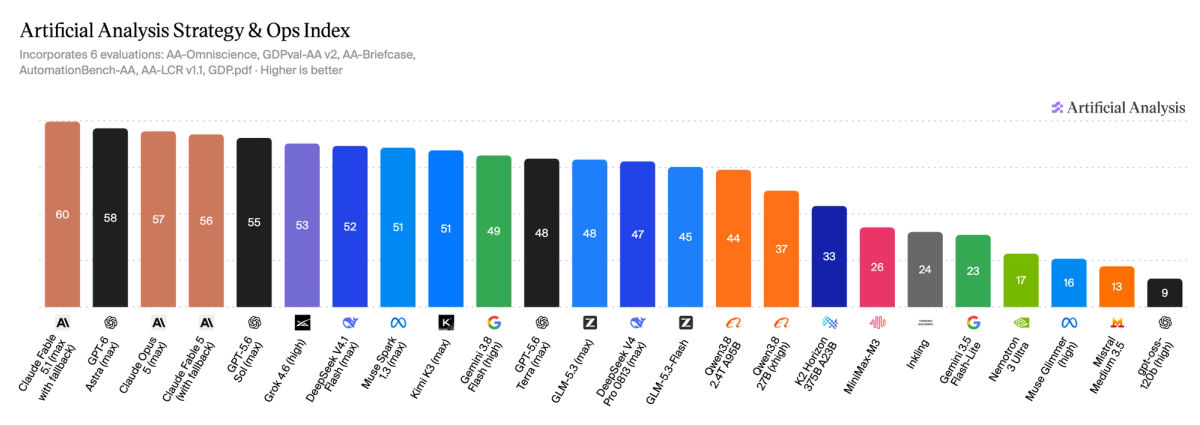
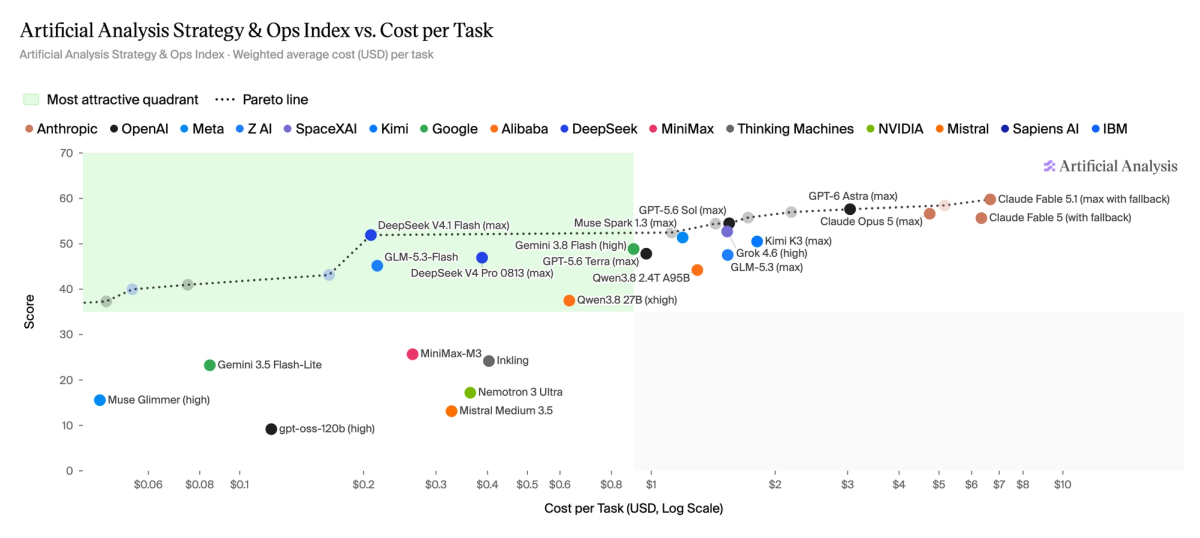
Agentic Tool Use added, sourced from the Operations slice of AutomationBench-AA to reflect the importance of tool use in day-to-day operational tasks. Agentic Customer Interaction removed. AA-Briefcase added alongside GDPval-AA v2 in Agentic Knowledge Work, and GDP.pdf added alongside LCR in Long-Context.
| Capability | Evaluations | v1.0 | v1.1 |
|---|---|---|---|
| Agentic Knowledge Work | GDPval-AA v2, AA-Briefcase | 35% | 35% |
| Business Knowledge | AA-Omniscience | 30% | 30% |
| Agentic Tool Use | AutomationBench-AA | 0% | 30% |
| Long-Context | LCR, GDP.pdf | 5% | 5% |
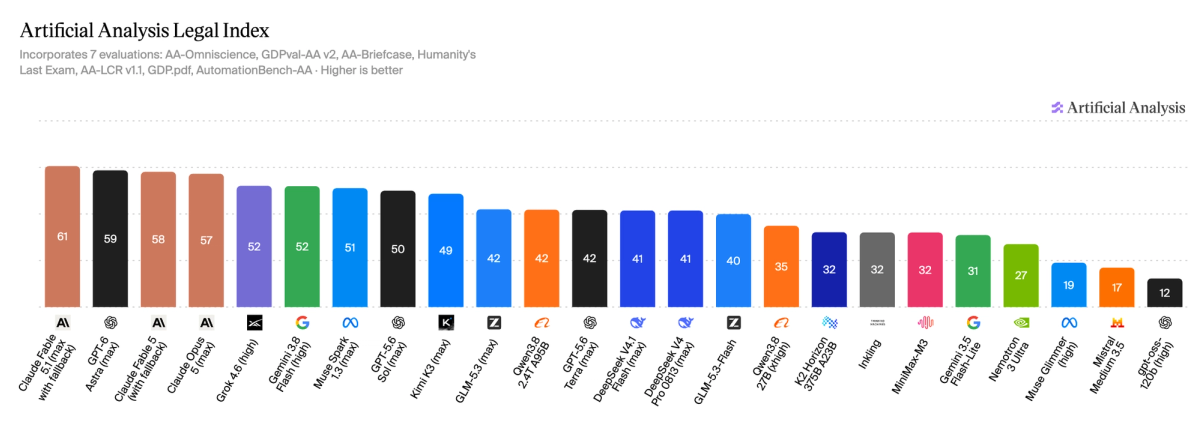
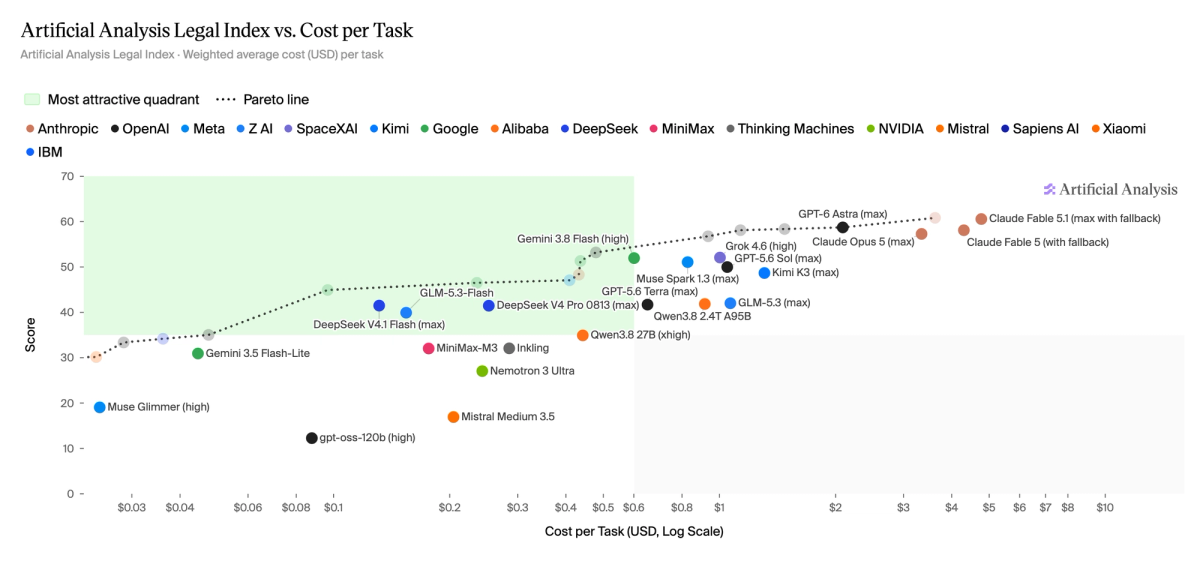
Legal
Agentic Tool Use added, sourced from the Operations and Support slices of AutomationBench-AA to reflect the role of tool use in legal workflows. Agentic Customer Interaction removed. AA-Briefcase added alongside GDPval-AA v2 in Agentic Knowledge Work, and GDP.pdf added alongside LCR in Long-Context.
| Capability | Evaluations | v1.0 | v1.1 |
|---|---|---|---|
| Legal Knowledge | AA-Omniscience | 35% | 35% |
| Agentic Knowledge Work | GDPval-AA v2, AA-Briefcase | 25% | 25% |
| Reasoning | HLE | 15% | 15% |
| Long-Context | LCR, GDP.pdf | 10% | 10% |
| Non-Hallucination | AA-Omniscience | 10% | 10% |
| Agentic Tool Use | AutomationBench-AA | 0% | 5% |
Healthcare & Medical
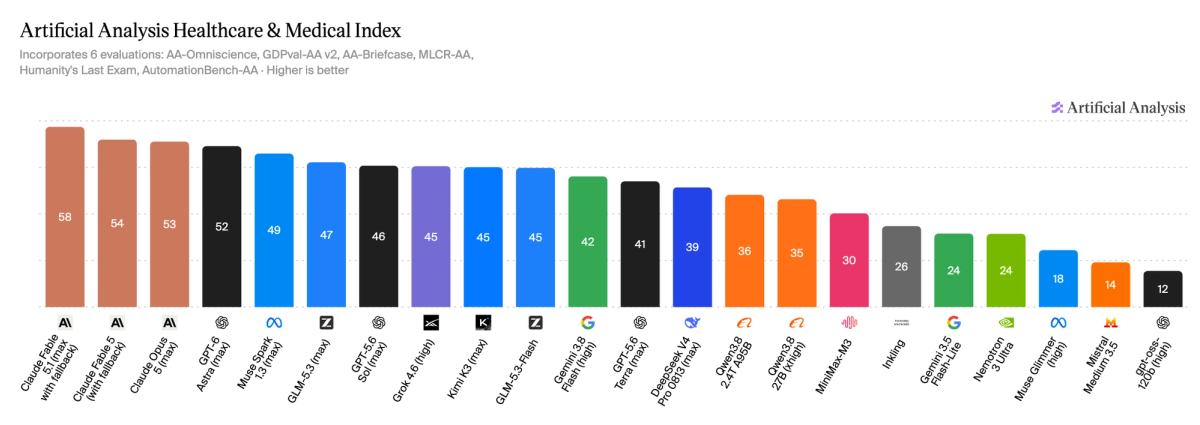
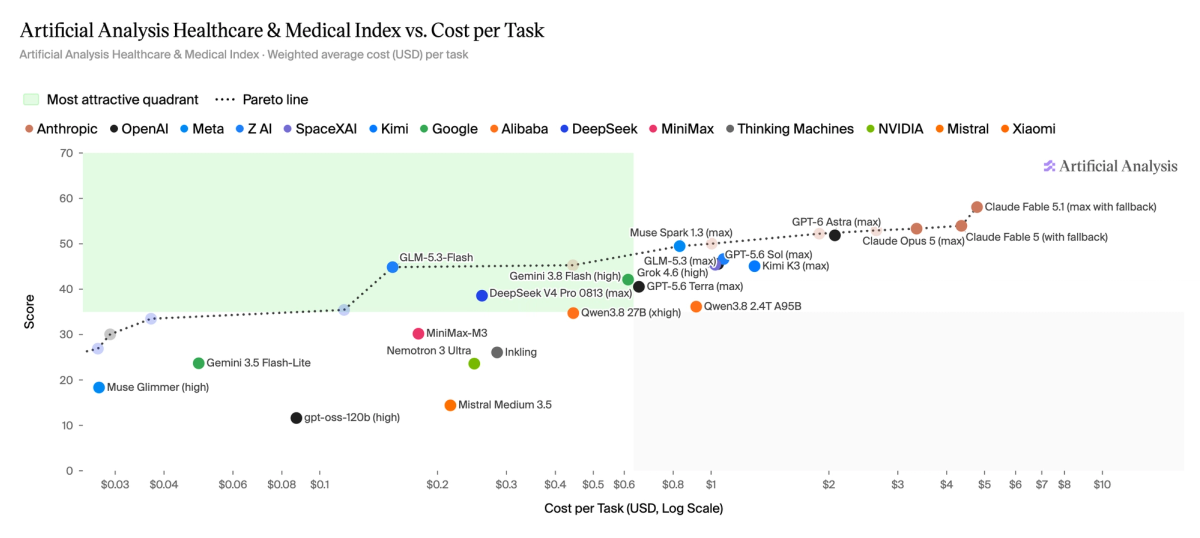
Long-Context Reasoning added, sourced from MLCR-AA. This evaluates reasoning across lengthy clinical records. Agentic Tool Use added, sourced from the Operations and Support slices of AutomationBench-AA to cover operational workflows relevant to healthcare. Agentic Customer Interaction removed. AA-Briefcase added alongside GDPval-AA v2 in Agentic Knowledge Work.
| Capability | Evaluations | v1.0 | v1.1 |
|---|---|---|---|
| Medical & Health Knowledge | AA-Omniscience | 35% | 30% |
| Agentic Knowledge Work | GDPval-AA v2, AA-Briefcase | 25% | 25% |
| Long-Context Reasoning | MLCR-AA | 0% | 15% |
| Non-Hallucination | AA-Omniscience | 15% | 10% |
| Reasoning | HLE | 15% | 10% |
| Agentic Tool Use | AutomationBench-AA | 0% | 10% |
Engineering
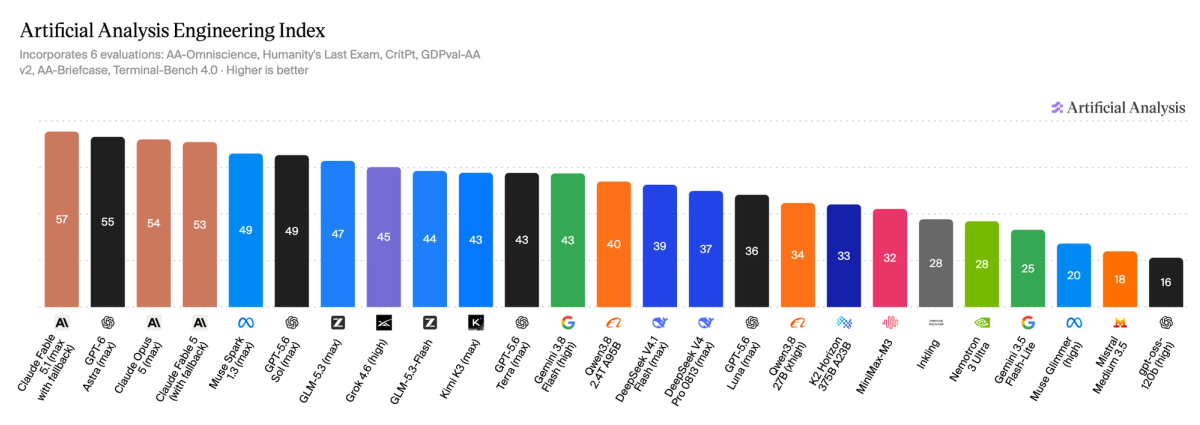
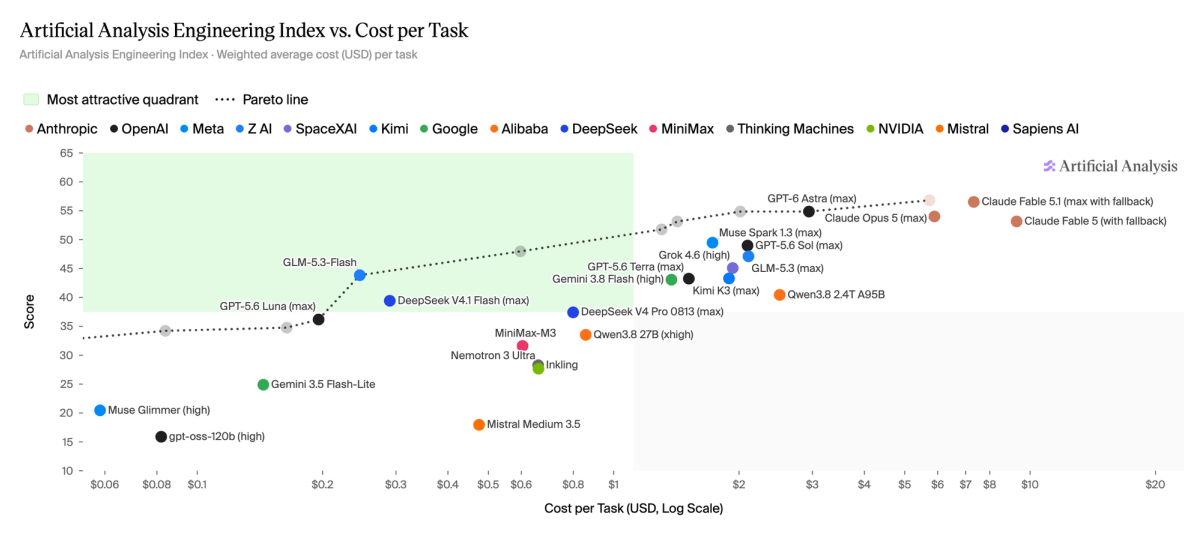
Agentic Terminal Use updated to Terminal-Bench v4.0. GPQA Diamond removed from Reasoning. AA-Briefcase added alongside GDPval-AA v2 in Agentic Knowledge Work.
| Capability | Evaluations | v1.0 | v1.1 |
|---|---|---|---|
| Engineering Knowledge | AA-Omniscience | 35% | 35% |
| Reasoning | HLE, CritPt | 35% | 30% |
| Agentic Knowledge Work | GDPval-AA v2, AA-Briefcase | 25% | 20% |
| Agentic Terminal Use | Terminal-Bench 4.0 | 5% | 15% |
Economics
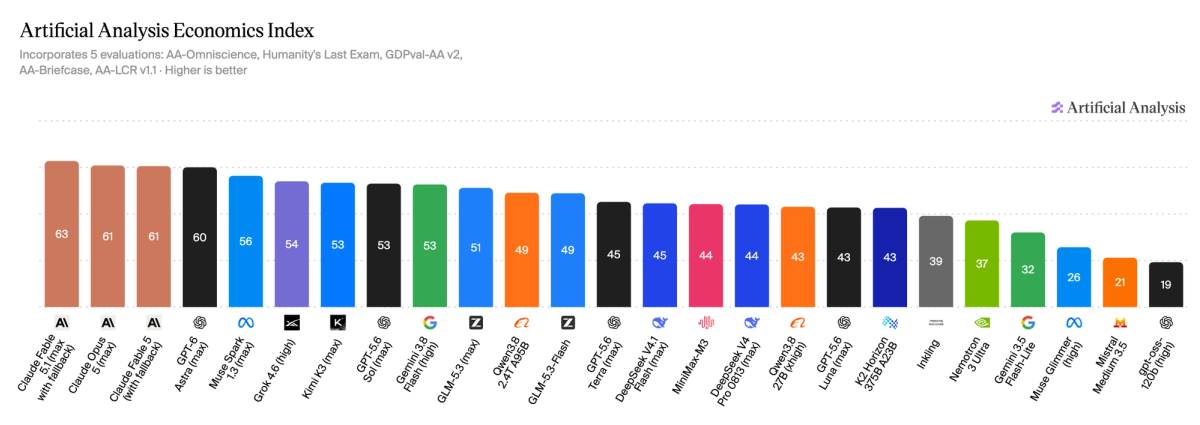
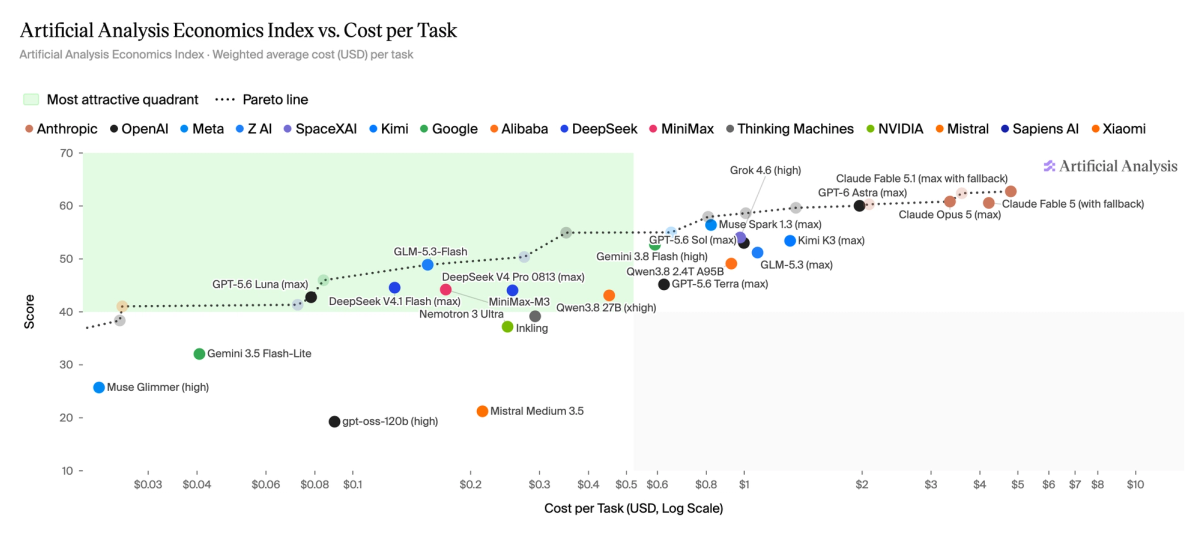
AA-Briefcase added alongside GDPval-AA v2 in Agentic Knowledge Work.
| Capability | Evaluations | v1.0 | v1.1 |
|---|---|---|---|
| Economics Knowledge | AA-Omniscience | 35% | 35% |
| Reasoning | HLE | 35% | 35% |
| Agentic Knowledge Work | GDPval-AA v2, AA-Briefcase | 15% | 25% |
| Long-Context Reasoning | LCR | 15% | 5% |
Full results and methodology
- Finance & Accounting: https://artificialanalysis.ai/models/capabilities/finance-and-accounting
- Strategy & Ops: https://artificialanalysis.ai/models/capabilities/strategy-and-ops
- Legal: https://artificialanalysis.ai/models/capabilities/legal
- Healthcare & Medical: https://artificialanalysis.ai/models/capabilities/healthcare-and-medical
- Engineering: https://artificialanalysis.ai/models/capabilities/engineering
- Economics: https://artificialanalysis.ai/models/capabilities/economics
Explore all Capability Indices: https://artificialanalysis.ai/models/capabilities
Read the methodology: https://artificialanalysis.ai/methodology/capability-indices
Read the latest
Korean AI Lab Upstage releases Solar Mini 4
Korean AI Lab Upstage has released Solar Mini 4 which scores 24 on the Artificial Analysis Intelligence Index, but costs ~5x as much per task as GPT-6 Luna (max) despite similar per-token prices
September 30, 2026
Gemini 4 Argon: Google is back as one of the top three labs in intelligence achieved
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
September 30, 2026
AA-AgentPerf-Local: Benchmarking local AI agents on laptops and workstations
Our open-source tool for testing how fast agentic AI runs on laptops and workstations, with launch results for the DGX Spark, Ryzen AI Halo, MacBook Pro (M5 Pro) and RTX 5090 across four open-weights models
September 29, 2026