August 13, 2026
Gemini 3.7 Flash: On the Intelligence vs. Time per Task Pareto frontier
See model pageGoogle has released Gemini 3.7 Flash, improving 4 points over Gemini 3.6 Flash and reaching the Intelligence vs. Time per Task Pareto frontier
Google DeepMind has released its third new Gemini Flash model in three months. Gemini 3.7 Flash (high) scores 56 on the Artificial Analysis Intelligence Index, just behind GPT-5.6 Terra (max, 57) and Muse Spark 1.2 (xhigh, 57)
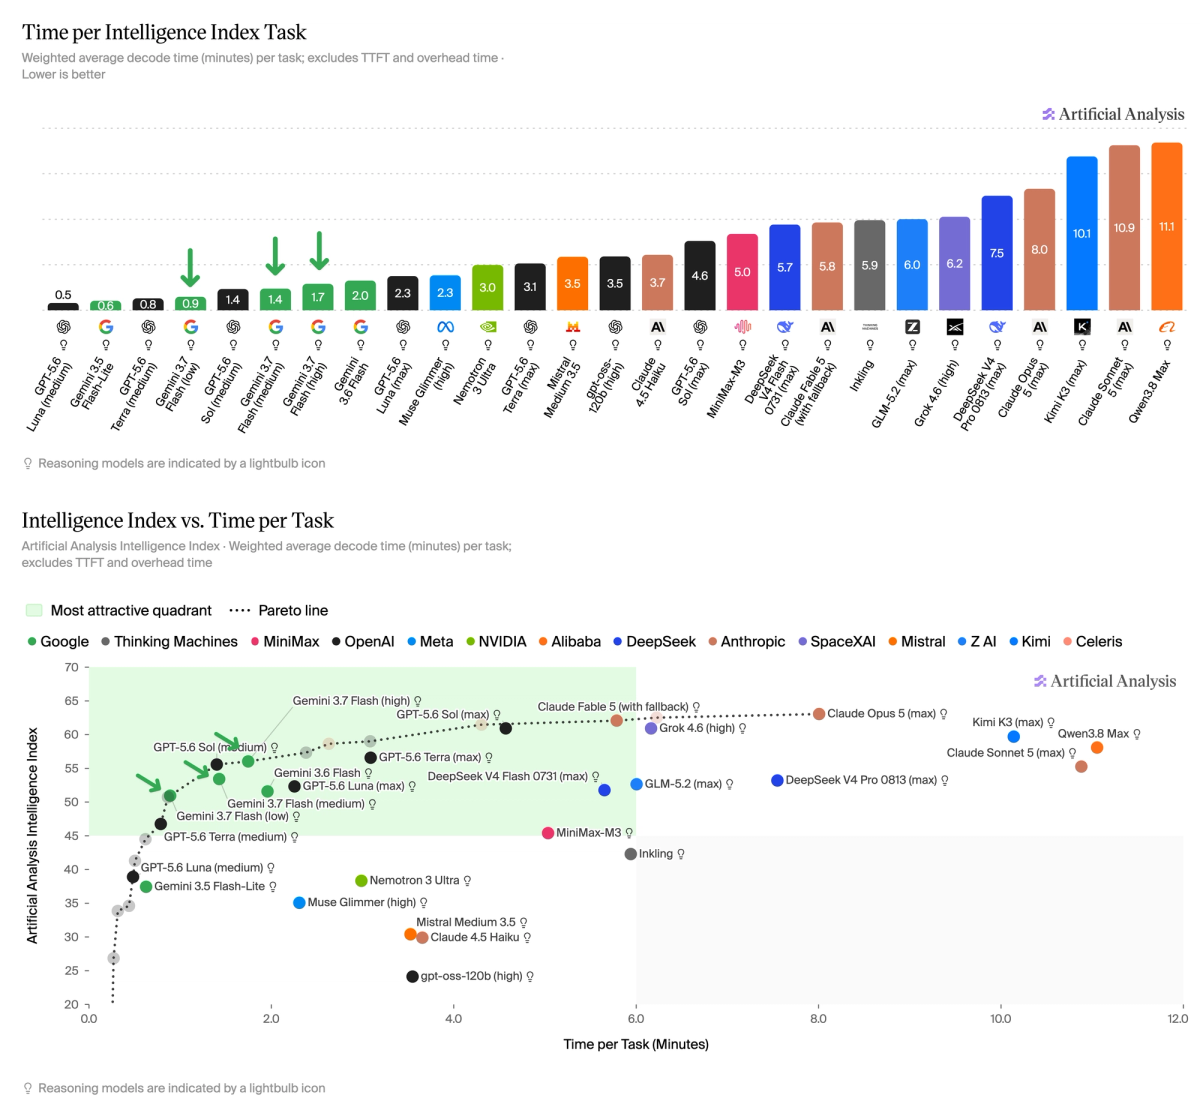
We benchmarked Gemini 3.7 Flash across all three reasoning levels (high, medium, low) ahead of release. With high reasoning, Gemini 3.7 Flash is a 4 point improvement over 3.6 Flash, while achieving an average Time per Task of 1.7, 40% faster than GPT-5.6 Terra (max). This places Gemini 3.7 Flash on the Intelligence vs. Time per Task Pareto frontier, reinforcing Google’s focus on speed across the Gemini Flash family of models
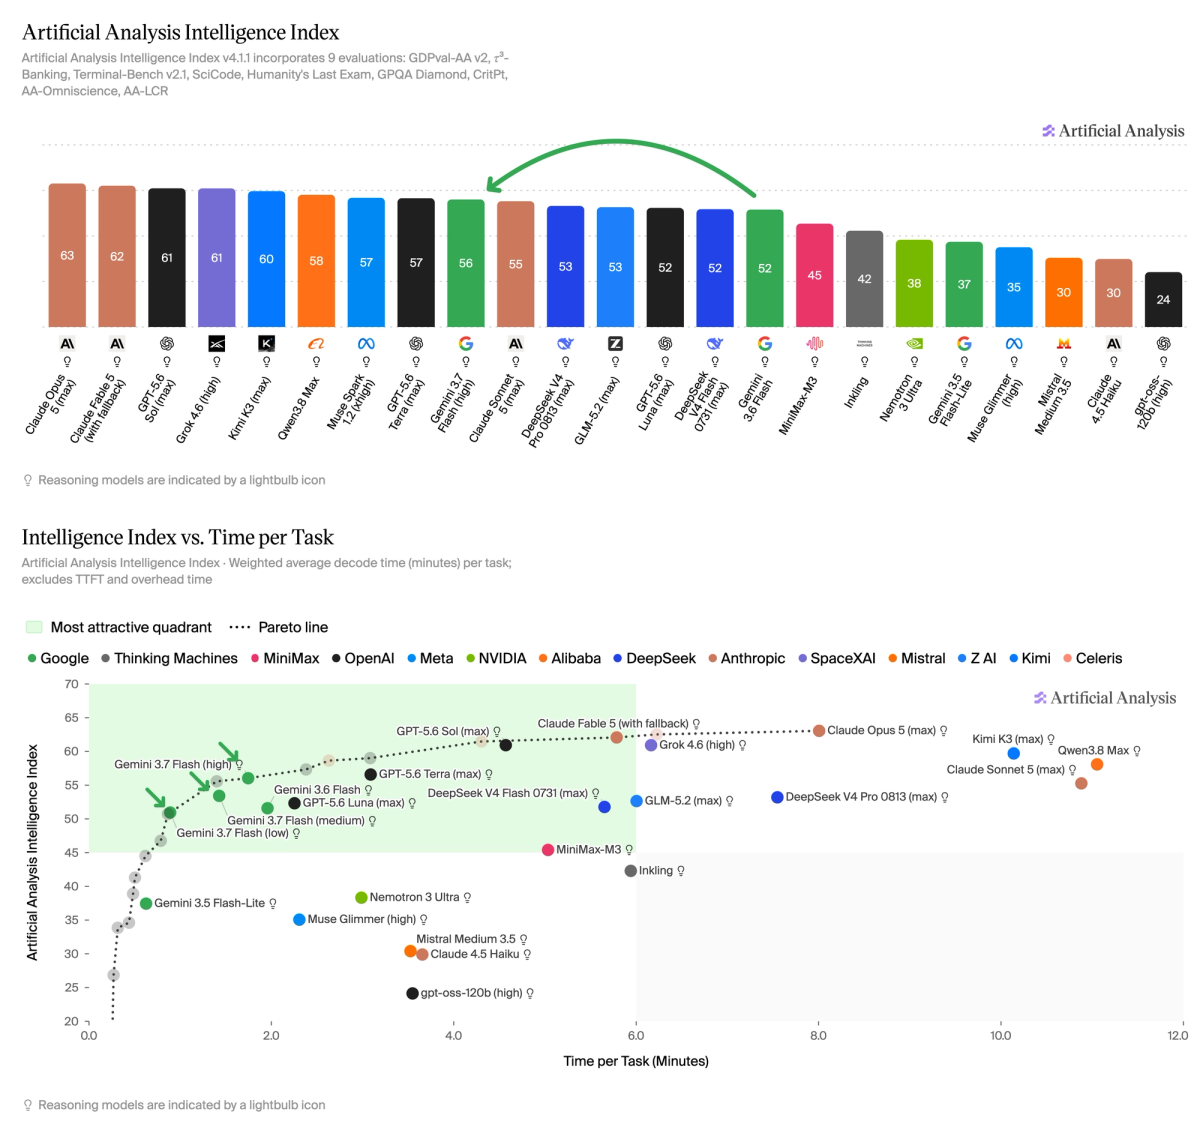
Key benchmarking results across Gemini 3.7 Flash’s three reasoning levels:
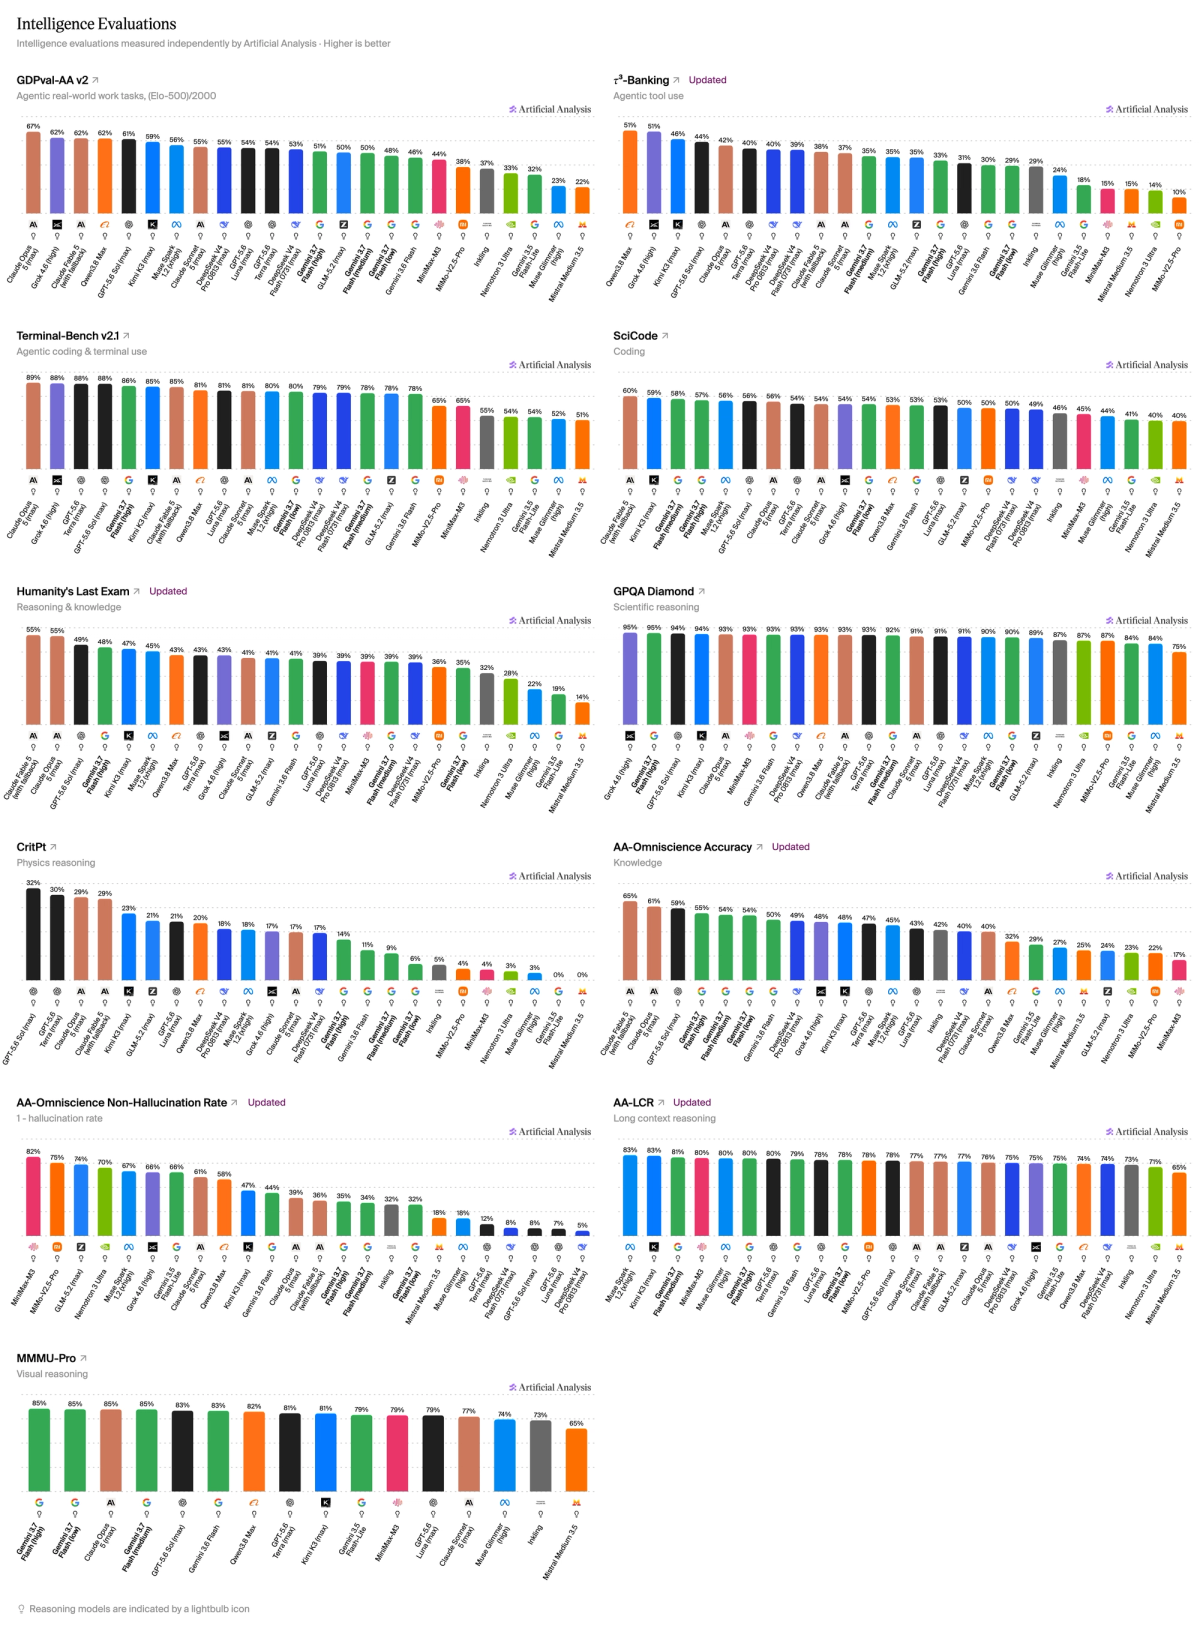
➤ 4 point Intelligence Index improvement: Gemini 3.7 Flash (high) scores 56 on the Artificial Analysis Intelligence Index, up 4 points from Gemini 3.6 Flash. The improvement is driven primarily by gains on agentic evaluations, including Tau3 Banking (+3 points), Terminal-Bench v2.1 (+8 points), and GDPval-AA v2 (+103 Elo). With medium reasoning, Gemini 3.7 Flash scores 53, matching DeepSeek V4 Pro 0813 (max, 53) and GLM-5.2 (max, 53). With low reasoning, it scores 51, just behind DeepSeek V4 Flash 0731 (max, 52)
➤ Pareto frontier on Intelligence vs. Time per Task: Gemini 3.7 Flash produces ~340 output tokens per second, nearly 3x the output speed of GPT-5.6 Terra and GLM-5.2. With high reasoning, this translates to an average Time per Task of 1.7 minutes, placing Gemini 3.7 Flash on the Intelligence vs. Time per Task Pareto frontier
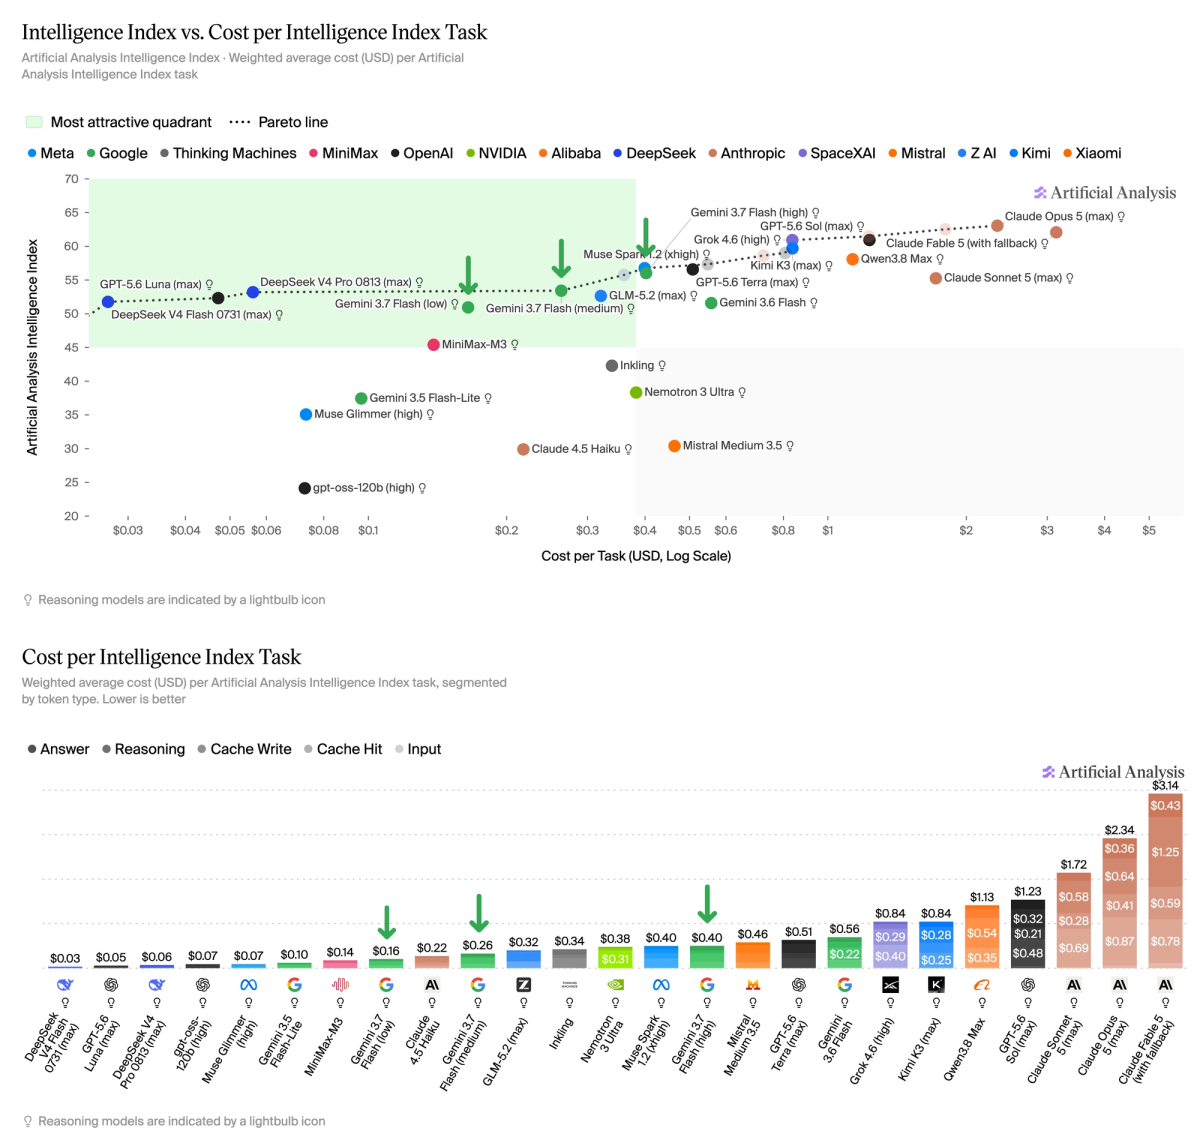
➤ 30% lower Cost per Task than Gemini 3.6 Flash: Gemini 3.7 Flash retains Gemini 3.6 Flash’s standard pricing of $1.50/$7.50 per 1M input/output tokens, however Google is offering discounted pricing through the end of the year at $0.75/$3.75 per 1M tokens. At this discounted price, Gemini 3.7 Flash (high) costs $0.40 per Intelligence Index task, 30% less than Gemini 3.6 Flash and matching Muse Spark 1.2 (xhigh, $0.40). With medium reasoning, Cost per Task falls to $0.26, placing the model on the Intelligence vs. Cost per Task Pareto frontier
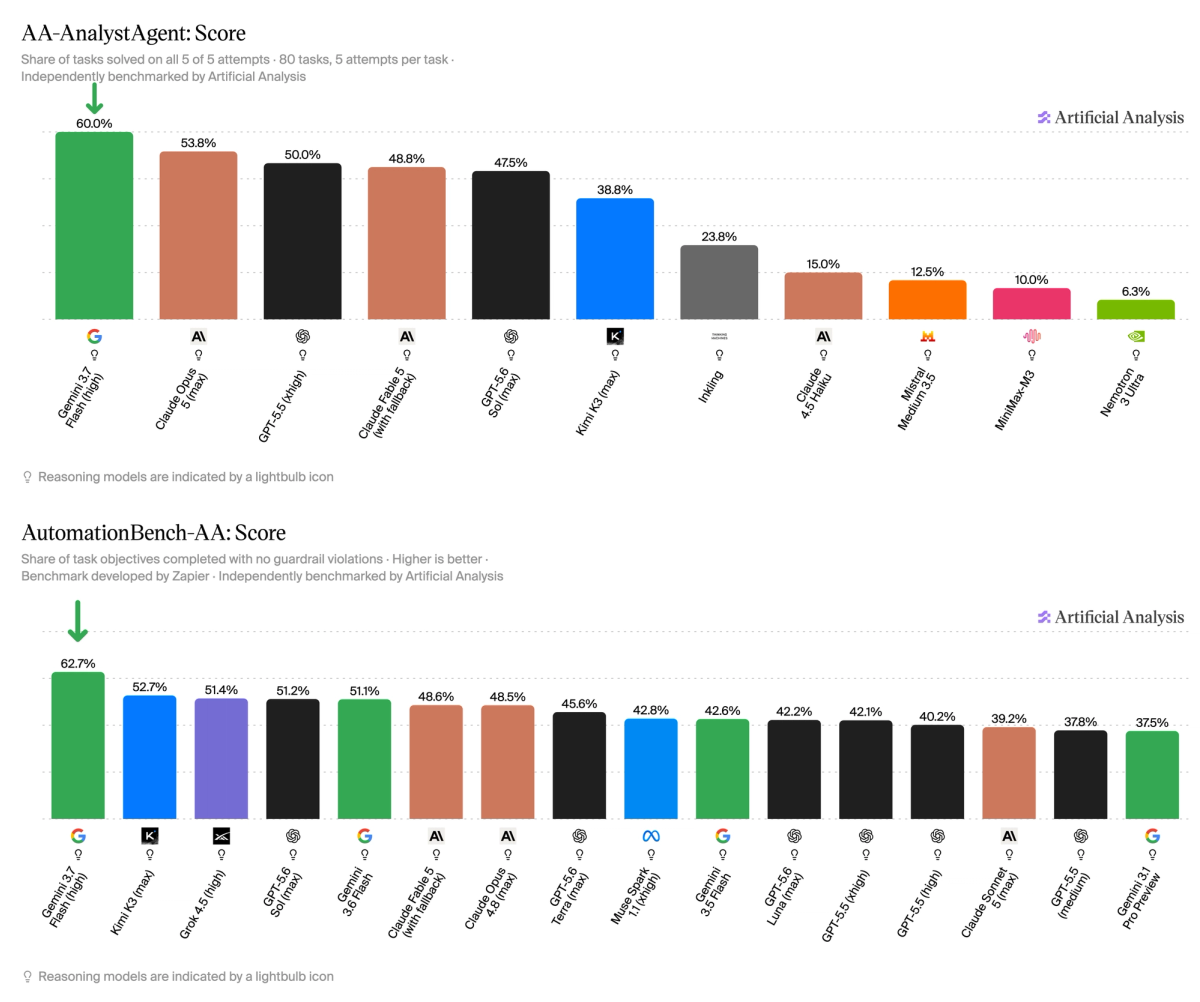
➤ Leading performance on AutomationBench-AA and AA-AnalystAgent: On AA-AnalystAgent, our recently released benchmark measuring models’ ability to answer complex questions about spreadsheets and documents, Gemini 3.7 Flash (high) achieves the highest pass^5 score at 60%, ahead of Claude Opus 5 (max, 54%) and Fable 5 (49%). Gemini 3.7 Flash also leads AutomationBench-AA, our benchmark of agentic capabilities in simulated SaaS environments, with a score of 62.7%, ahead of Kimi K3 (max, 53%) and GPT-5.6 Sol (max, 51.2%)
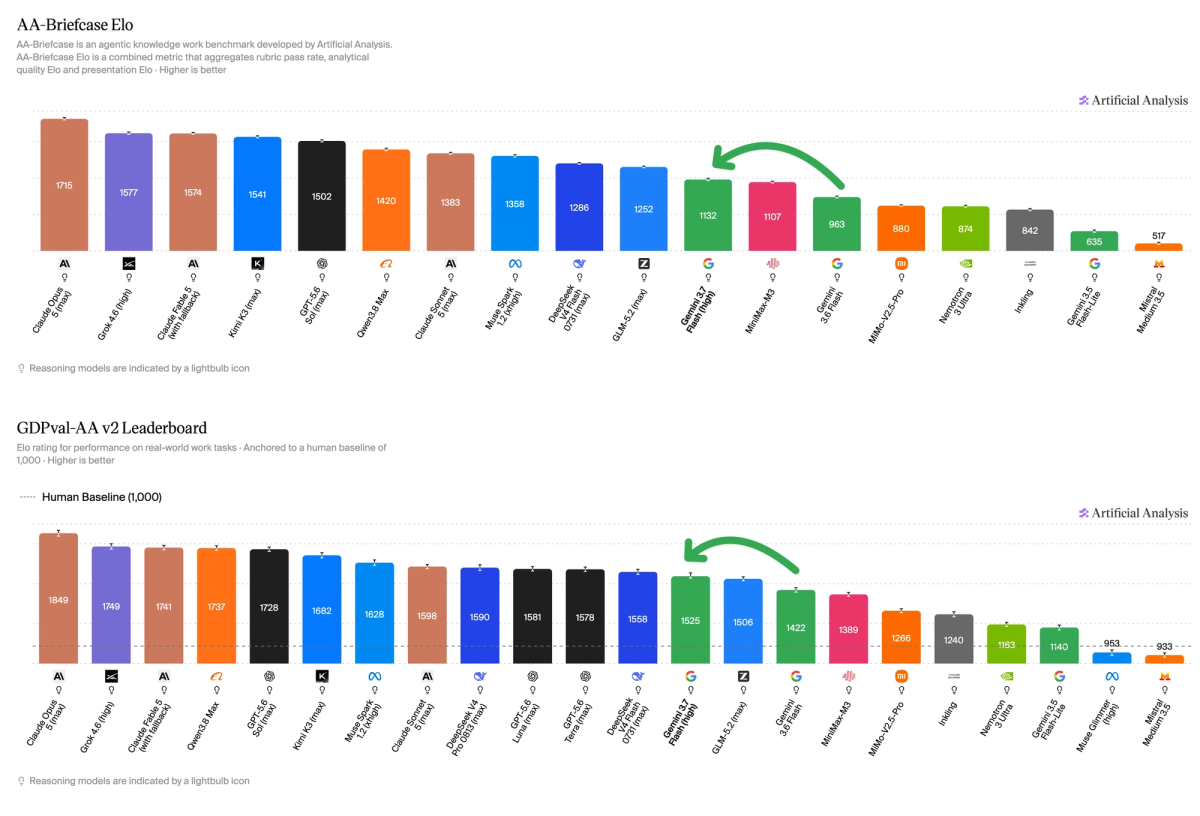
➤ Agentic knowledge work improvements: Gemini 3.7 Flash shows improvement across agentic benchmarks compared to Gemini 3.6 Flash. In AA-Briefcase, our proprietary agentic knowledge work evaluation, Gemini 3.7 Flash (high) achieves a 1132 Elo, a +169 improvement from its predecessor, putting it just above Minimax-M3. Similarly, Gemini 3.7 Flash (high) improves by 103 points on GDPval-AA v2, scoring 1525, on par with GLM 5.2 (max, 1506) and DeepSeek V4 Flash 0731 (max, 1558)
Key model details:
➤ Context Window: 1M tokens, unchanged from Gemini 3.6 Flash
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $1.50/$7.50 per 1M input/output tokens at standard pricing. Google is offering discounted pricing of $0.75/$3.75 per 1M tokens through the end of the year. Cached input tokens retain the same 90% discount
For further analysis, see https://artificialanalysis.ai/models/gemini-3-7-flash
Read the latest
Reflection has released Beam, their first model launch
Reflection’s first model, Beam, scores 30 on the Artificial Analysis Intelligence Index, placing it #2 among US open weights models
October 16, 2026
First AA-AgentPerf results for NVIDIA Vera Rubin NVL72
NVIDIA Vera Rubin NVL72 serves up to ~5.7x the total throughput per megawatt of GB300 NVL72 on AA-AgentPerf, with first results on DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
October 15, 2026
First AA-AgentPerf-Local results for an NVIDIA RTX Spark N1X laptop
An NVIDIA RTX Spark N1X laptop completes our local agent workload on Qwen3.8 27B in 18.7 minutes.
October 15, 2026