October 16, 2026
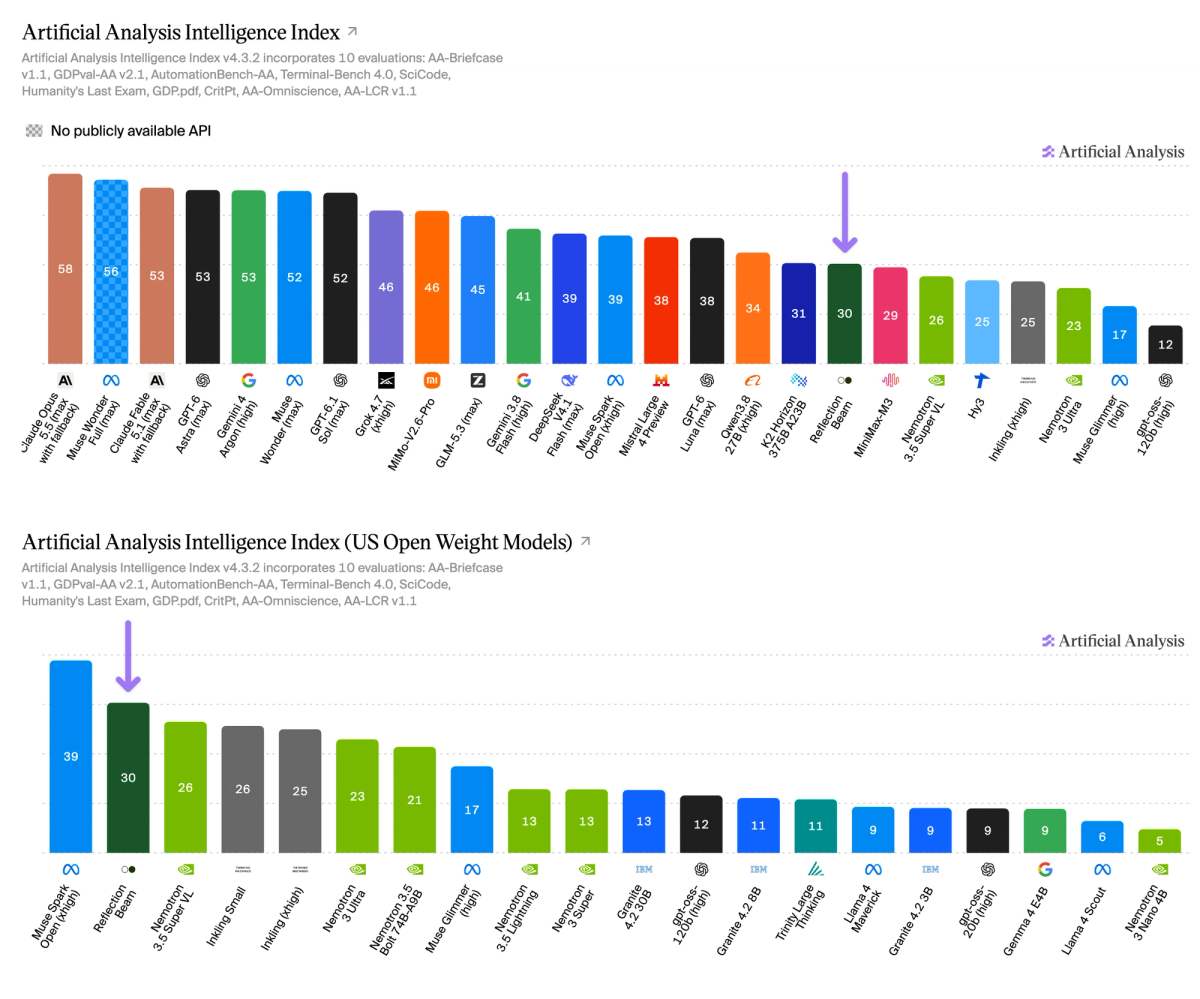
Reflection’s first model, Beam, scores 30 on the Artificial Analysis Intelligence Index, placing it #2 among US open weights models
See model page See model pageBeam is an open weights model with 501B total and 23B active parameters
Key takeaways:
➤ Second among US open weights models: Beam scores 30, behind only Meta's Muse Spark Open (39) and ahead of yesterday’s NVIDIA Nemotron 3.5 Super VL (26) release. Outside China, only Muse Spark Open and the UAE's K2 Horizon (31) score higher
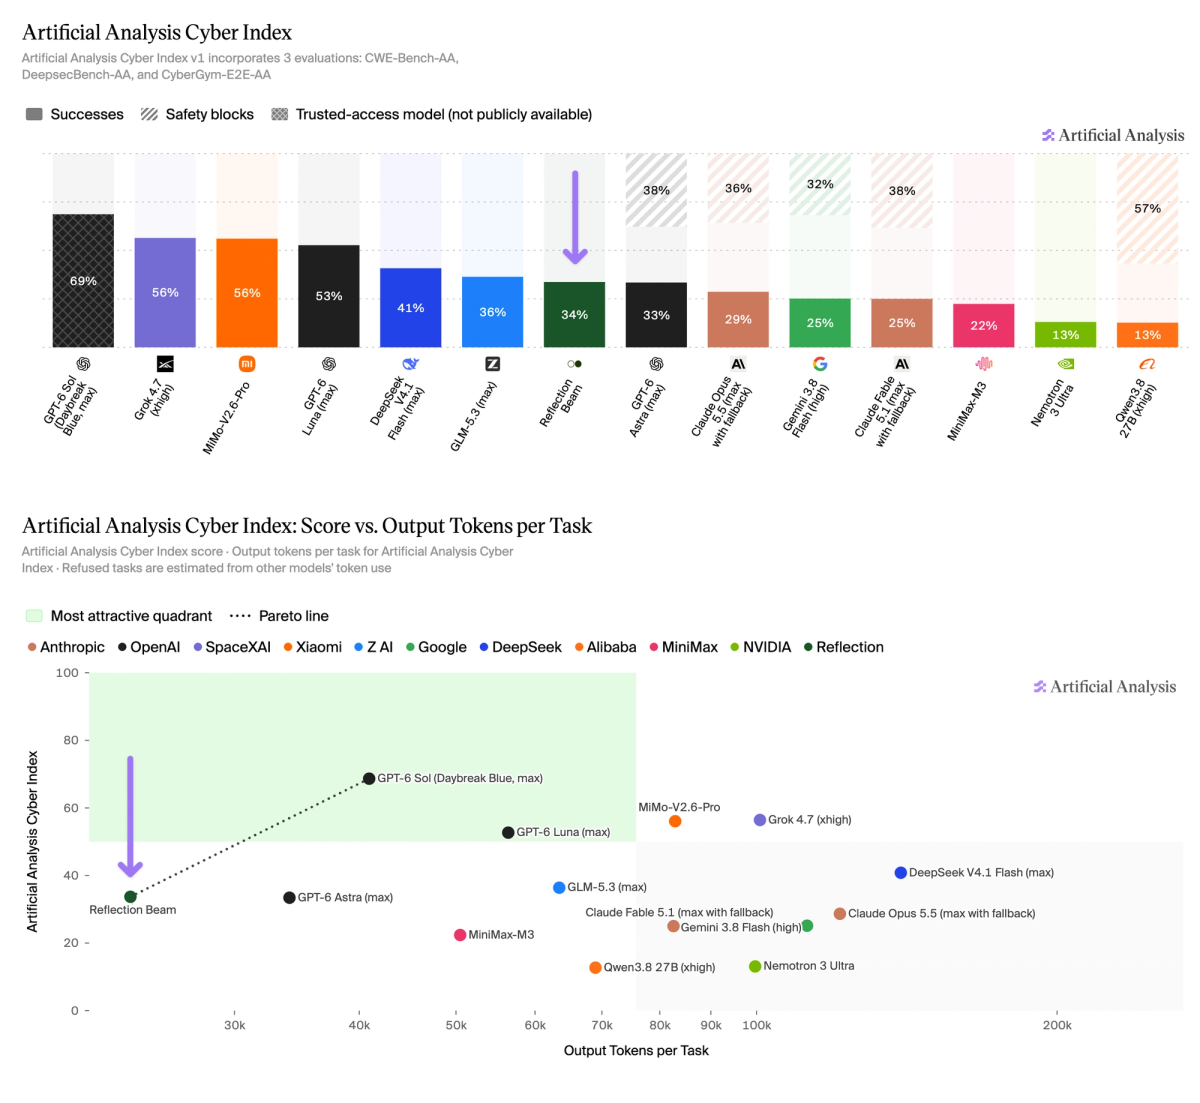
➤ Token efficient for its intelligence: Beam uses ~26k output tokens per Intelligence Index task compared to K2 Horizon, one point ahead, which uses twice as many (~52k). Proprietary models still set the frontier, with GPT-6 Astra (max) scoring 53 on the same budget (~27k)
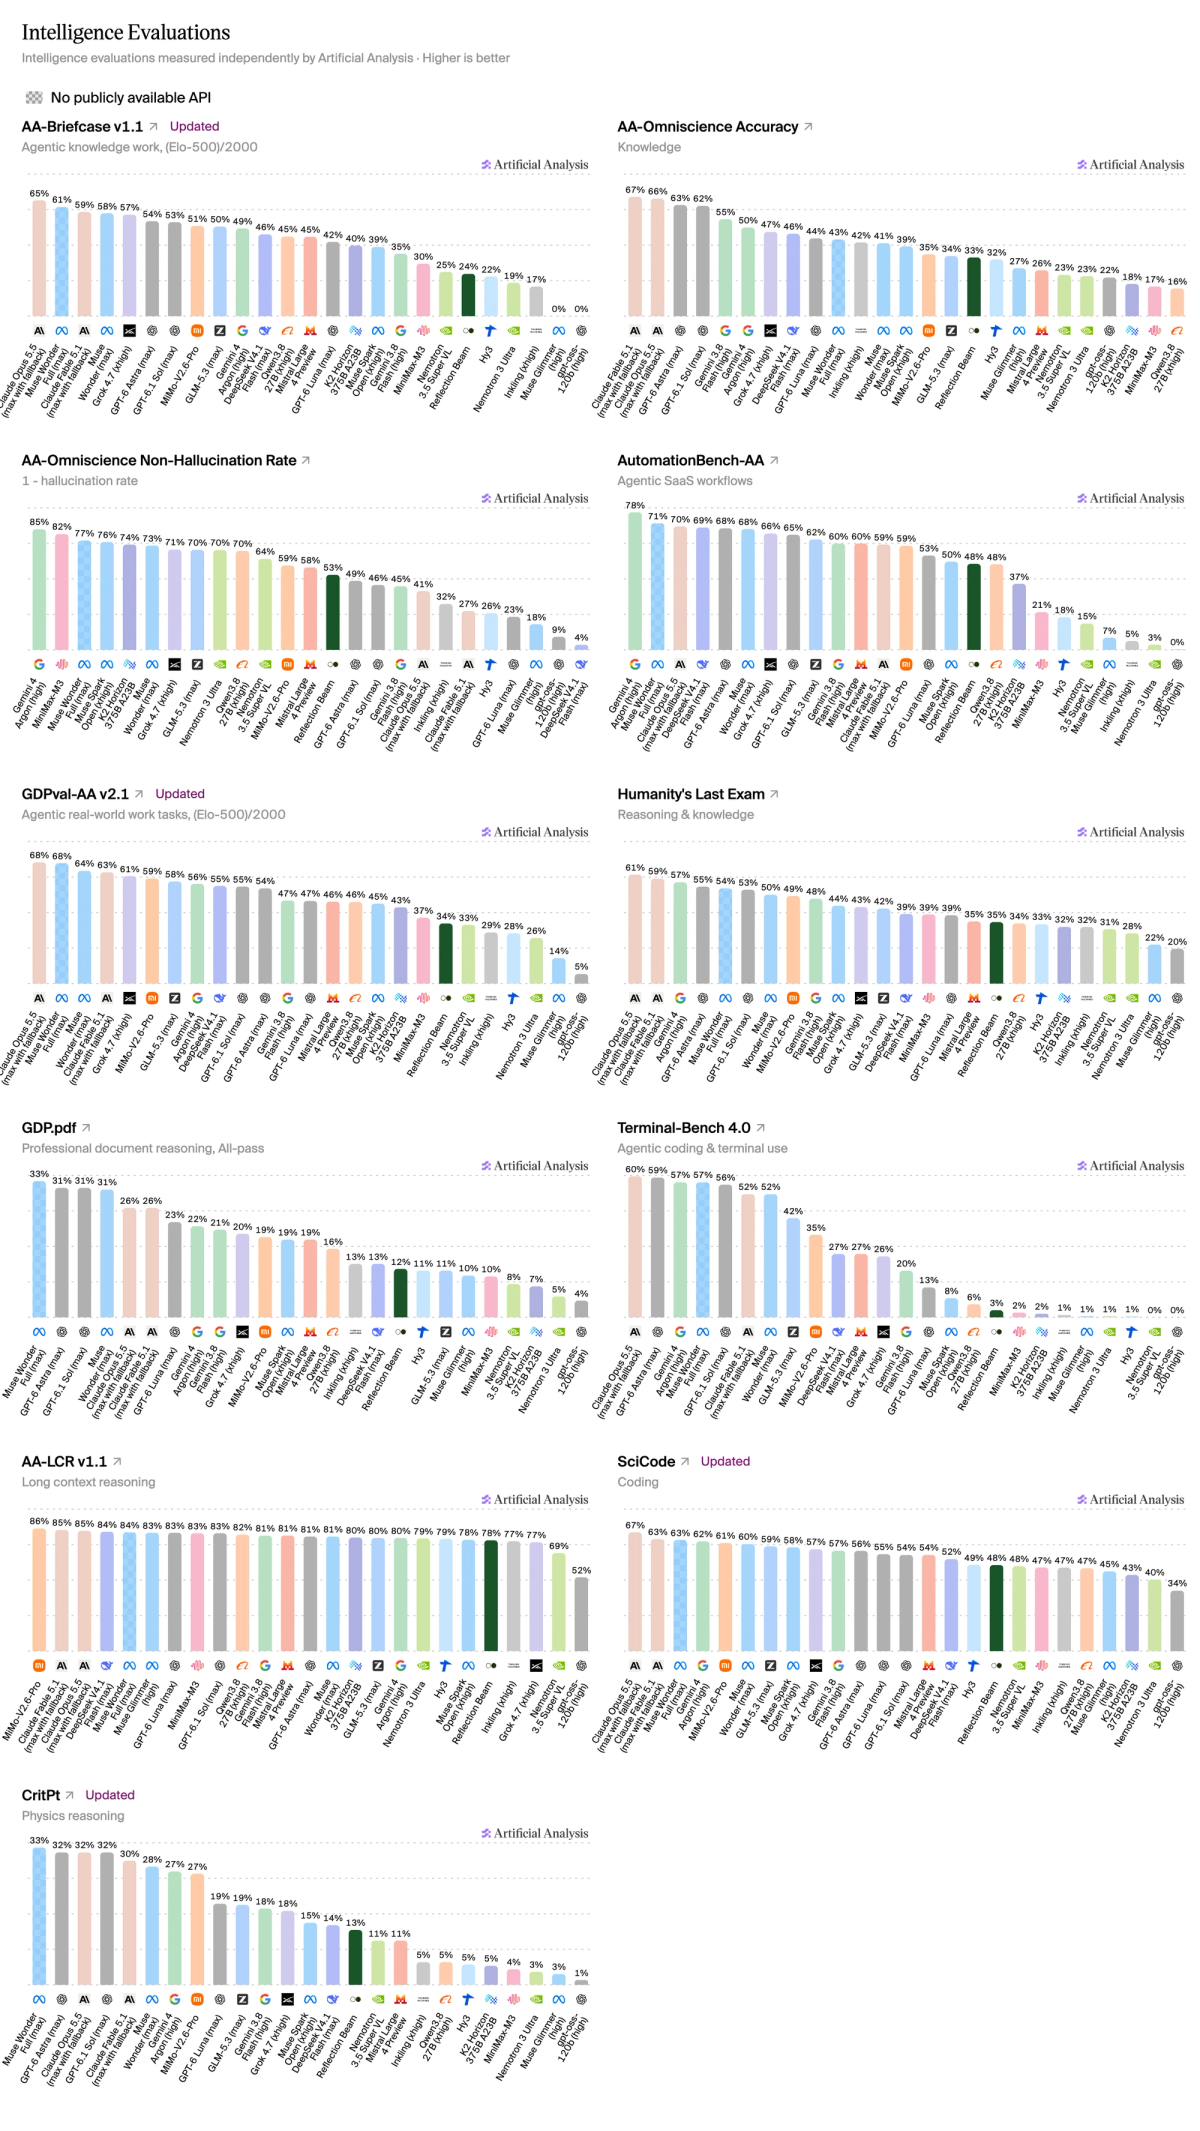
➤ Strong on agentic workflows, weaker in the terminal: Beam scores 48.5% on AutomationBench-AA, 11 percentage points ahead of K2 Horizon (37.2%) and level with Qwen3.8 27B (48.2%). Terminal-Bench 4.0 is a weak point, where Beam scores 3.0%, behind Qwen3.8 27B (5.6%) and Muse Spark Open (8.1%)
➤ Knows more, guesses more: On AA-Omniscience it answers 33% of questions correctly, well ahead of K2 Horizon (18%) and Qwen3.8 27B (16%). But its hallucination rate is 47%, against 26% for K2 Horizon and 30% for Qwen3.8 27B, giving Beam a net index score of 1.5, ahead of both peers (−3.0 and −10.0)
Other model details
- Context window: 1M tokens
- Modalities: Text
- Parameters: 501B / 23B
Compared to open weights peers
Beam scores highly against US open weights models, trailing Meta's Muse Spark Open (39) and ahead of NVIDIA's Nemotron 3.5 Super VL (26), all released this week. Among all open weights models it ranks tenth, one point behind K2 Horizon (31)
Cyber capabilities
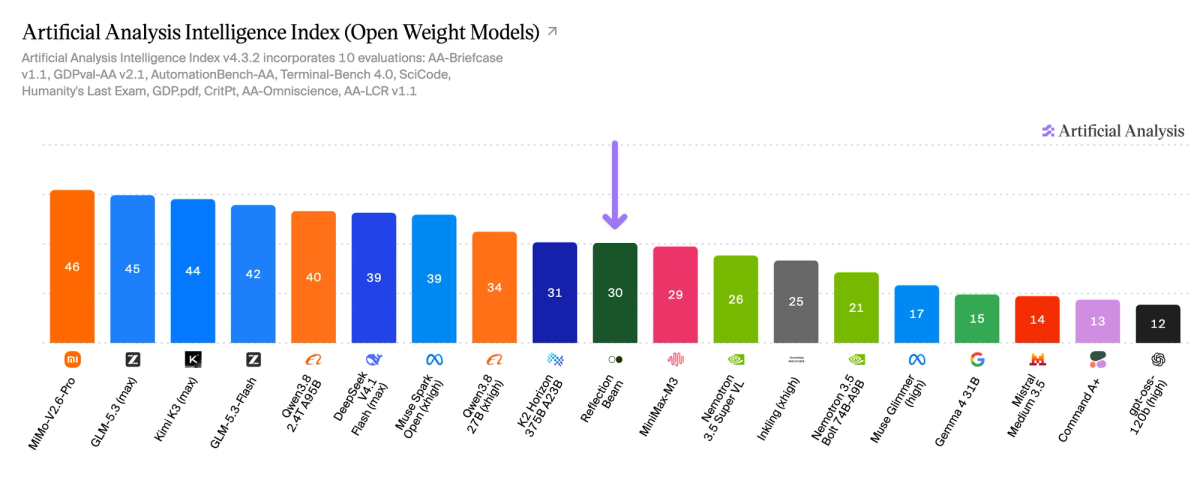
Beam completes 34% of tasks on the Artificial Analysis Cyber Index, making it the leading US open weights model that we’ve tested
Driven by its token efficiency, it also sits on the Cyber Index vs. Output Tokens per task frontier, alongside GPT-6 Sol (Daybreak Blue)
Highly token efficient
Beam uses ~26k output tokens per Intelligence Index task: ~19k for reasoning and ~7k for answers. Only 26% of its output goes to final answers, the 28th-lowest share of 219 models tested on Intelligence Index v4.3
Coding skills
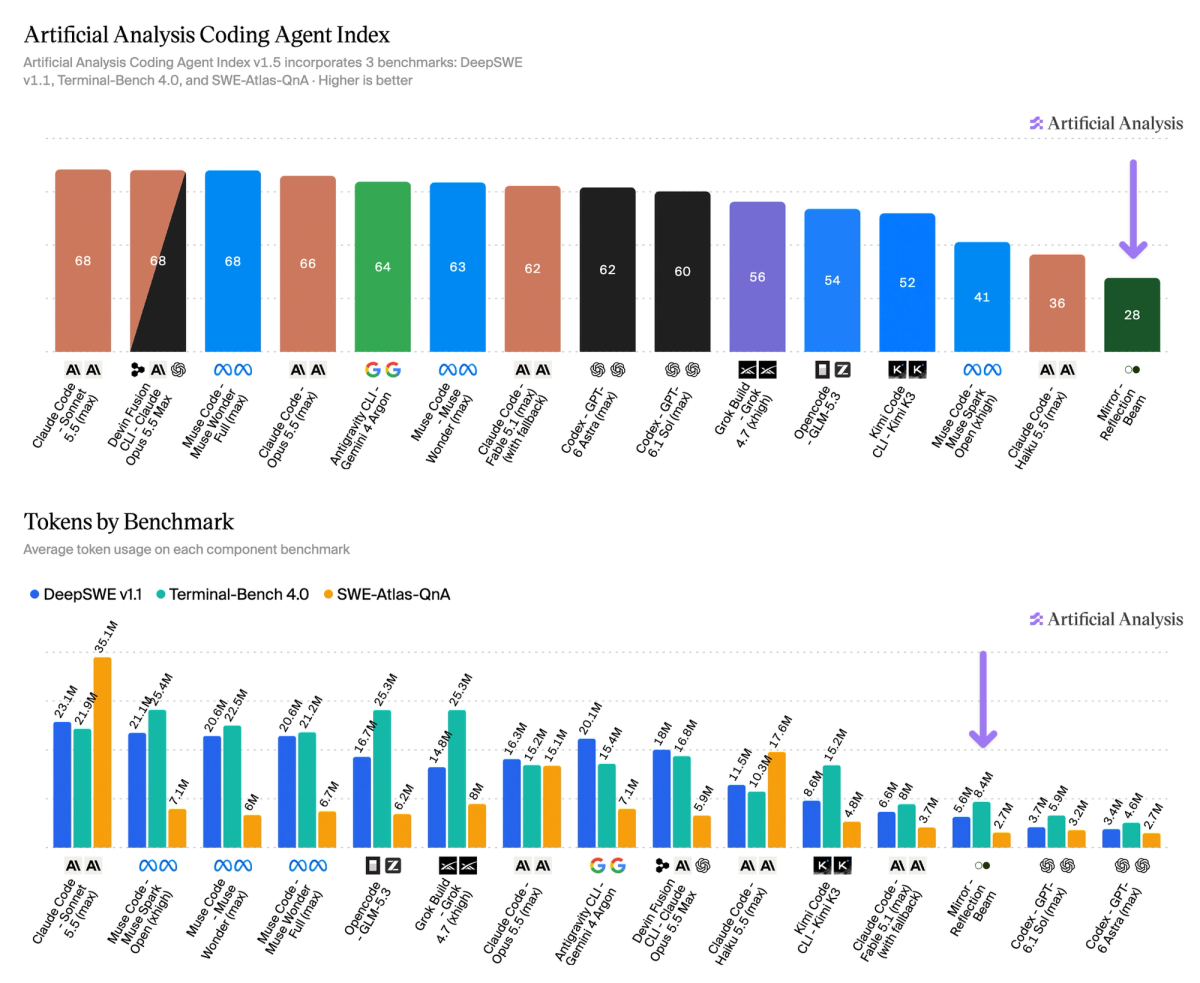
Running in Mirror, Reflection's open-source CLI harness, Beam scores 28 on the Artificial Analysis Coding Agent Index. It sits 15 points behind the next setup, Claude Code with Qwen3.8 Max (43), and 40 behind the leaders (68). It is, however, frugal: only Codex with GPT-6 Astra and Codex with GPT-6.1 Sol use fewer tokens
Intelligence Index Components
Across the ten evaluations in the Intelligence Index, Beam stands out on AutomationBench-AA (48.5%) and CritPt (13.1%), where it more than doubles K2 Horizon (4.6%) and Qwen3.8 27B (5.4%). Its weakest results are on Terminal-Bench 4.0 (3.0%) and AA-Briefcase (976 Elo)
Full details on Beam's Artificial Analysis page https://artificialanalysis.ai/models/reflection-beam
Read the latest
First AA-AgentPerf results for NVIDIA Vera Rubin NVL72
NVIDIA Vera Rubin NVL72 serves up to ~5.7x the total throughput per megawatt of GB300 NVL72 on AA-AgentPerf, with first results on DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
October 15, 2026
First AA-AgentPerf-Local results for an NVIDIA RTX Spark N1X laptop
An NVIDIA RTX Spark N1X laptop completes our local agent workload on Qwen3.8 27B in 18.7 minutes.
October 15, 2026
NVIDIA Releases Nemotron 3.5 Super VL and Nemotron 3.5 Bolt 74B A9B
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
October 15, 2026