June 3, 2026
Fun-Realtime-TTS: New Text to Speech model topping Artificial Analysis leaderboard
Alibaba's Fun-Realtime-TTS takes the #1 spot on the Artificial Analysis Speech Arena Leaderboard, surpassing Google's Gemini 3.1 Flash TTS and Inworld's Realtime TTS-2 Research Preview
Competition at the top of the TTS Arena is tighter than ever, with just 24 Elo points separating the top five models. Fun-Realtime-TTS takes the top spot with the highest Elo score on the leaderboard.
Alibaba's previous Fun-Realtime-TTS-Preview reached #7 on the leaderboard, making this Alibaba's first #1 model in the Artificial Analysis Speech Arena. Fun-Realtime-TTS is available via Alibaba Cloud with API access for developers.
Key takeaways:
➤ Quality: Fun-Realtime-TTS has an Elo score of 1,219 (+16/-16) based on 962 arena appearances, placing it ahead of Gemini 3.1 Flash TTS at 1,214, Inworld Realtime TTS-2 Research Preview at 1,209, and Cartesia Sonic 3.5 at 1,203
➤ Pricing: Fun-Realtime-TTS is priced at $27.59/1M characters, positioning it between Gemini 3.1 Flash TTS at $18.3/1M characters and Inworld Realtime TTS 1.5 Max at $35/1M characters, while remaining below Sonic 3.5 at $39/1M characters.
➤ Features: Fun-Realtime-TTS supports real-time speech generation with voice cloning, voice design, multilingual output, and support for regional accents and dialects.
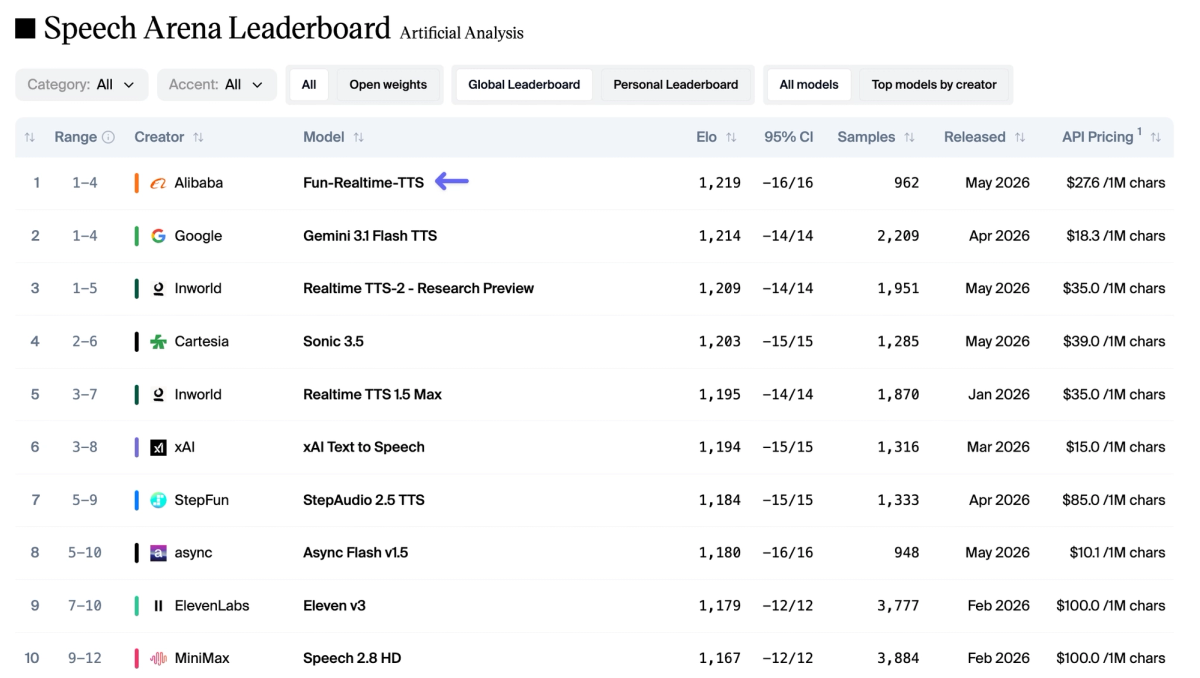
Fun-Realtime-TTS achieves the highest Elo score on the Speech Arena Leaderboard while remaining competitively priced at $27.6/1M characters, below several other frontier TTS models including Sonic 3.5 and Inworld Realtime TTS-2 Research Preview.

See the top models on the Artificial Analysis Speech leaderboard: https://artificialanalysis.ai/text-to-speech/leaderboard
Vote for models in the Speech Arena: https://artificialanalysis.ai/text-to-speech/arena
Explore sample clips from Fun-Realtime-TTS in the Speech Explorer: https://artificialanalysis.ai/text-to-speech/speech-explorer
Read the latest

Artificial Analysis Decision Index v1.0
The Artificial Analysis Decision Index benchmarks decision models, a new category of models that answer structured decisions in a single call with a probability for each option. Version 1.0 combines four evaluations across classification, tool calling, knowledge, hallucination, and reasoning.
October 13, 2026

Announcing AA-3D: a benchmark for AI models building interactive 3D experiences
AA-3D is a new benchmark of how well AI models build interactive 3D experiences. Each model turns a written brief into a working three.js scene in an offline sandbox, and our recruited panel compares the scenes in blind pairwise votes.
October 12, 2026
Announcing FrontierCode on Artificial Analysis: can AI models write code maintainers would merge?
Cognition's FrontierCode 1.1 tests whether AI models make code changes that maintainers of real open source repositories would merge. Leading models still fail more than 40% of the time.
October 12, 2026