August 6, 2026
Launching v4.1.1 of the Artificial Analysis Intelligence Index
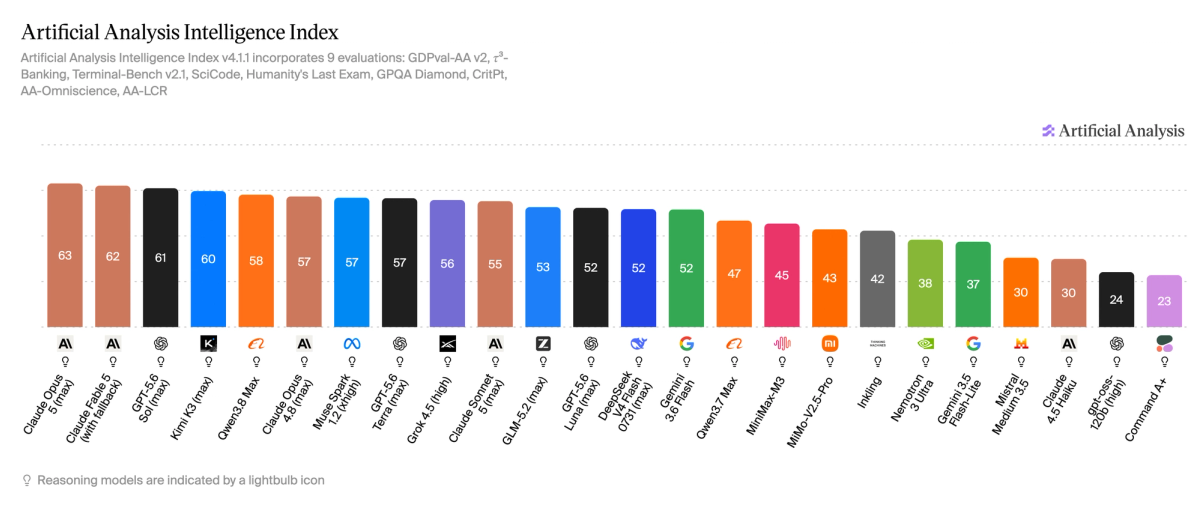
We have updated the Artificial Analysis Intelligence Index to v4.1.1 - this patch release upgrades our grader models, and brings the latest 𝜏³-Banking version to Artificial Analysis
To keep the Artificial Analysis Intelligence Index the most useful synthesis metric for developers, we make regular updates to the included evaluations and our independent methodology. Today’s update is a minor one to keep our existing evaluation set as reliable as possible.
Overall model rankings remain largely consistent, with a slight increase in scores due to improved grading robustness across the updated evaluations. Claude Opus 5 remains in the #1 position with an Index of 63.
Key changes:
➤ 𝜏³-Banking now runs v1.0.1 from Sierra, updating to the latest upstream task versions and improved grader pipeline that resolves correctness errors in trajectories that recover from unhappy paths
➤ HLE, AA-LCR and AA-Omniscience are now graded by GPT-5.6 Luna (medium), replacing GPT-4o, Qwen3 235B A22B 2507, and Gemini 3 Flash Preview respectively. These checks are now unified under a more capable modern model, selected for strong agreement with human judgment in our grader validation
➤ The effect on scores is small: most models move by less than a point on the Intelligence Index. The largest increase occurred for Muse Spark 1.2 (xhigh, +2.7 points), and the same models hold the top of the leaderboard
Published scores are now using v4.1.1, so all model results on Artificial Analysis now reflect these changes and use our latest consistent, independent methodology.
Read the latest

Artificial Analysis Decision Index v1.0
The Artificial Analysis Decision Index benchmarks decision models, a new category of models that answer structured decisions in a single call with a probability for each option. Version 1.0 combines four evaluations across classification, tool calling, knowledge, hallucination, and reasoning.
October 13, 2026

Announcing AA-3D: a benchmark for AI models building interactive 3D experiences
AA-3D is a new benchmark of how well AI models build interactive 3D experiences. Each model turns a written brief into a working three.js scene in an offline sandbox, and our recruited panel compares the scenes in blind pairwise votes.
October 12, 2026
Announcing FrontierCode on Artificial Analysis: can AI models write code maintainers would merge?
Cognition's FrontierCode 1.1 tests whether AI models make code changes that maintainers of real open source repositories would merge. Leading models still fail more than 40% of the time.
October 12, 2026