ビジョンモデル:画像入力に対応するLLM
Artificial Analysis Visual Reasoning Indexを使って、画像とテキスト入力に対応するマルチモーダルLLMを比較します。プロバイダー間の性能、料金、遅延を比較し、ビジョンワークロードに最適な画像対応LLMを選べます。詳細は方法論のページをご覧ください。
ハイライト
分析の概要
視覚推論と画像入力料金
Visual reasoning intelligence: MMMU Pro evaluation · Image input price: USD per 1k images at 1MP (1024x1024)
Most attractive quadrant
視覚推論と遅延(画像1枚と1,000言語トークンの入力)
Visual reasoning intelligence: MMMU Pro evaluation · Seconds to first token received
Most attractive quadrant
知能
視覚推論の知能(MMMU Pro評価)
Visual reasoning intelligence: MMMU Pro evaluation
料金
Pricing: Image Input Pricing
Image input price: USD per 1k images at 1MP (1024x1024)
料金:言語入力、画像入力、言語出力
Price (USD per M Tokens) · Image input price: USD per 1k images at 1MP (1024x1024) · Lower is better
遅延と速度
遅延(画像1枚と1,000言語トークンの入力)
Seconds to first token received · Lower is better
遅延のばらつき(画像1枚と1,000言語トークンの入力)
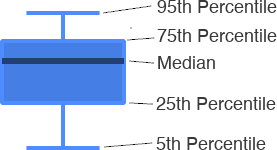
Seconds to first token received · Results by percentile · Lower is better
出力速度(画像1枚と1,000言語トークンの入力)
Output tokens per second · Higher is better