April 23, 2026
OpenAI's GPT-5.5 is the new leading AI model
See model pageOpenAI's GPT-5.5 is the new leading model. GPT-5.5 tops the Artificial Analysis Intelligence Index by 3 points, breaking a three-way tie with Anthropic and Google
OpenAI gave us pre-release access to test all five reasoning effort levels: xhigh, high, medium, low and non-reasoning.
Key takeaways:
➤ OpenAI tops five headline evaluations: GPT-5.5 (xhigh) leads Terminal-Bench Hard, GDPval-AA and our newly hosted APEX-Agents-AA. The model trails only other OpenAI models in CritPt and AA-LCR, and comes second to Gemini 3.1 Pro Preview on three additional evaluations. The largest gains are on AA-Omniscience (+14 pts), our knowledge and hallucination benchmark, and τ²-Bench Telecom (+7 pts), a customer service agent benchmark.
➤ 20% more expensive to run our Index: Per-token pricing has doubled from GPT-5.4 to $5/$30 per 1M input/output tokens. However, a ~40% token use reduction largely absorbs the hike - resulting in a net ~+20% cost to run our Intelligence Index.
➤ Effort a clear ladder for balancing intelligence and cost: GPT-5.5 (medium) scores the same as Claude Opus 4.7 (max) on our Intelligence Index at one quarter of the cost (~$1,200 vs $4,800) - although Gemini 3.1 Pro Preview scores the same at a cost of ~$900. GPT-5.5 (low) approximates Claude Opus 4.7 (Non-reasoning, high) on our Intelligence Index at half the cost to run (~$500 vs ~$1,000).
➤ Number one in GDPval-AA with an Elo of 1785: GPT-5.5 (xhigh) leads Claude Opus 4.7 (max) by ~30 pts and Gemini 3.1 Pro Preview by ~470 pts. GDPval-AA is Artificial Analysis' benchmark that leverages OpenAI's GDPval dataset to evaluate models on real-world economically valuable tasks.
➤ Top AA-Omniscience accuracy, but trailing the frontier on hallucination: Our private AA-Omniscience benchmark rewards factual knowledge across diverse topics, but punishes hallucination. GPT-5.5 (xhigh) has the highest accuracy at 57% - meaning the model can recall facts in the Omniscience corpus more effectively than any other model. However, it has a hallucination rate of 86% - vs Opus 4.7 (max) at 36%, and Gemini 3.1 Pro Preview at 50%. This makes it more likely to answer a question when it does not 'know' the answer. The 14 pt gain in AA-Omniscience from GPT-5.4 (xhigh) was largely driven by knowledge, with a modest improvement in hallucination.
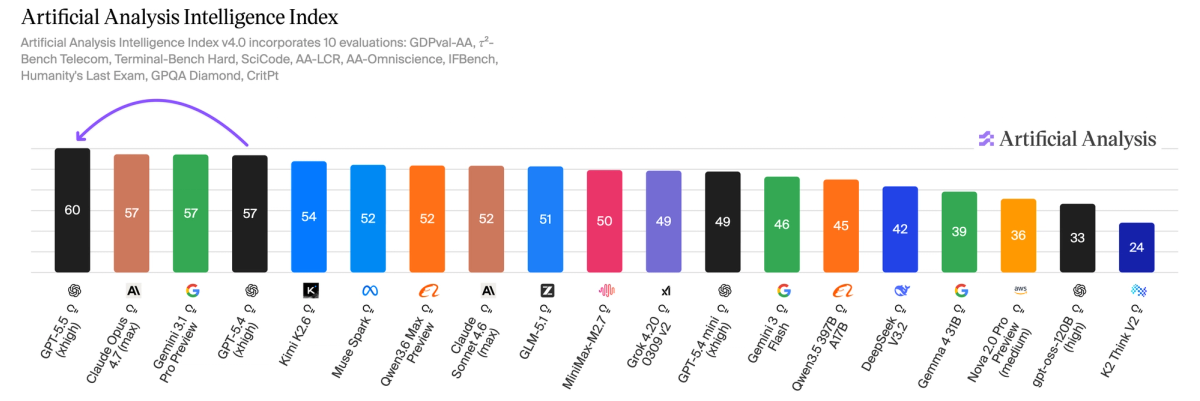 GPT-5.5 tops the Artificial Analysis Intelligence Index by 3 points, breaking a three-way tie with Anthropic and Google
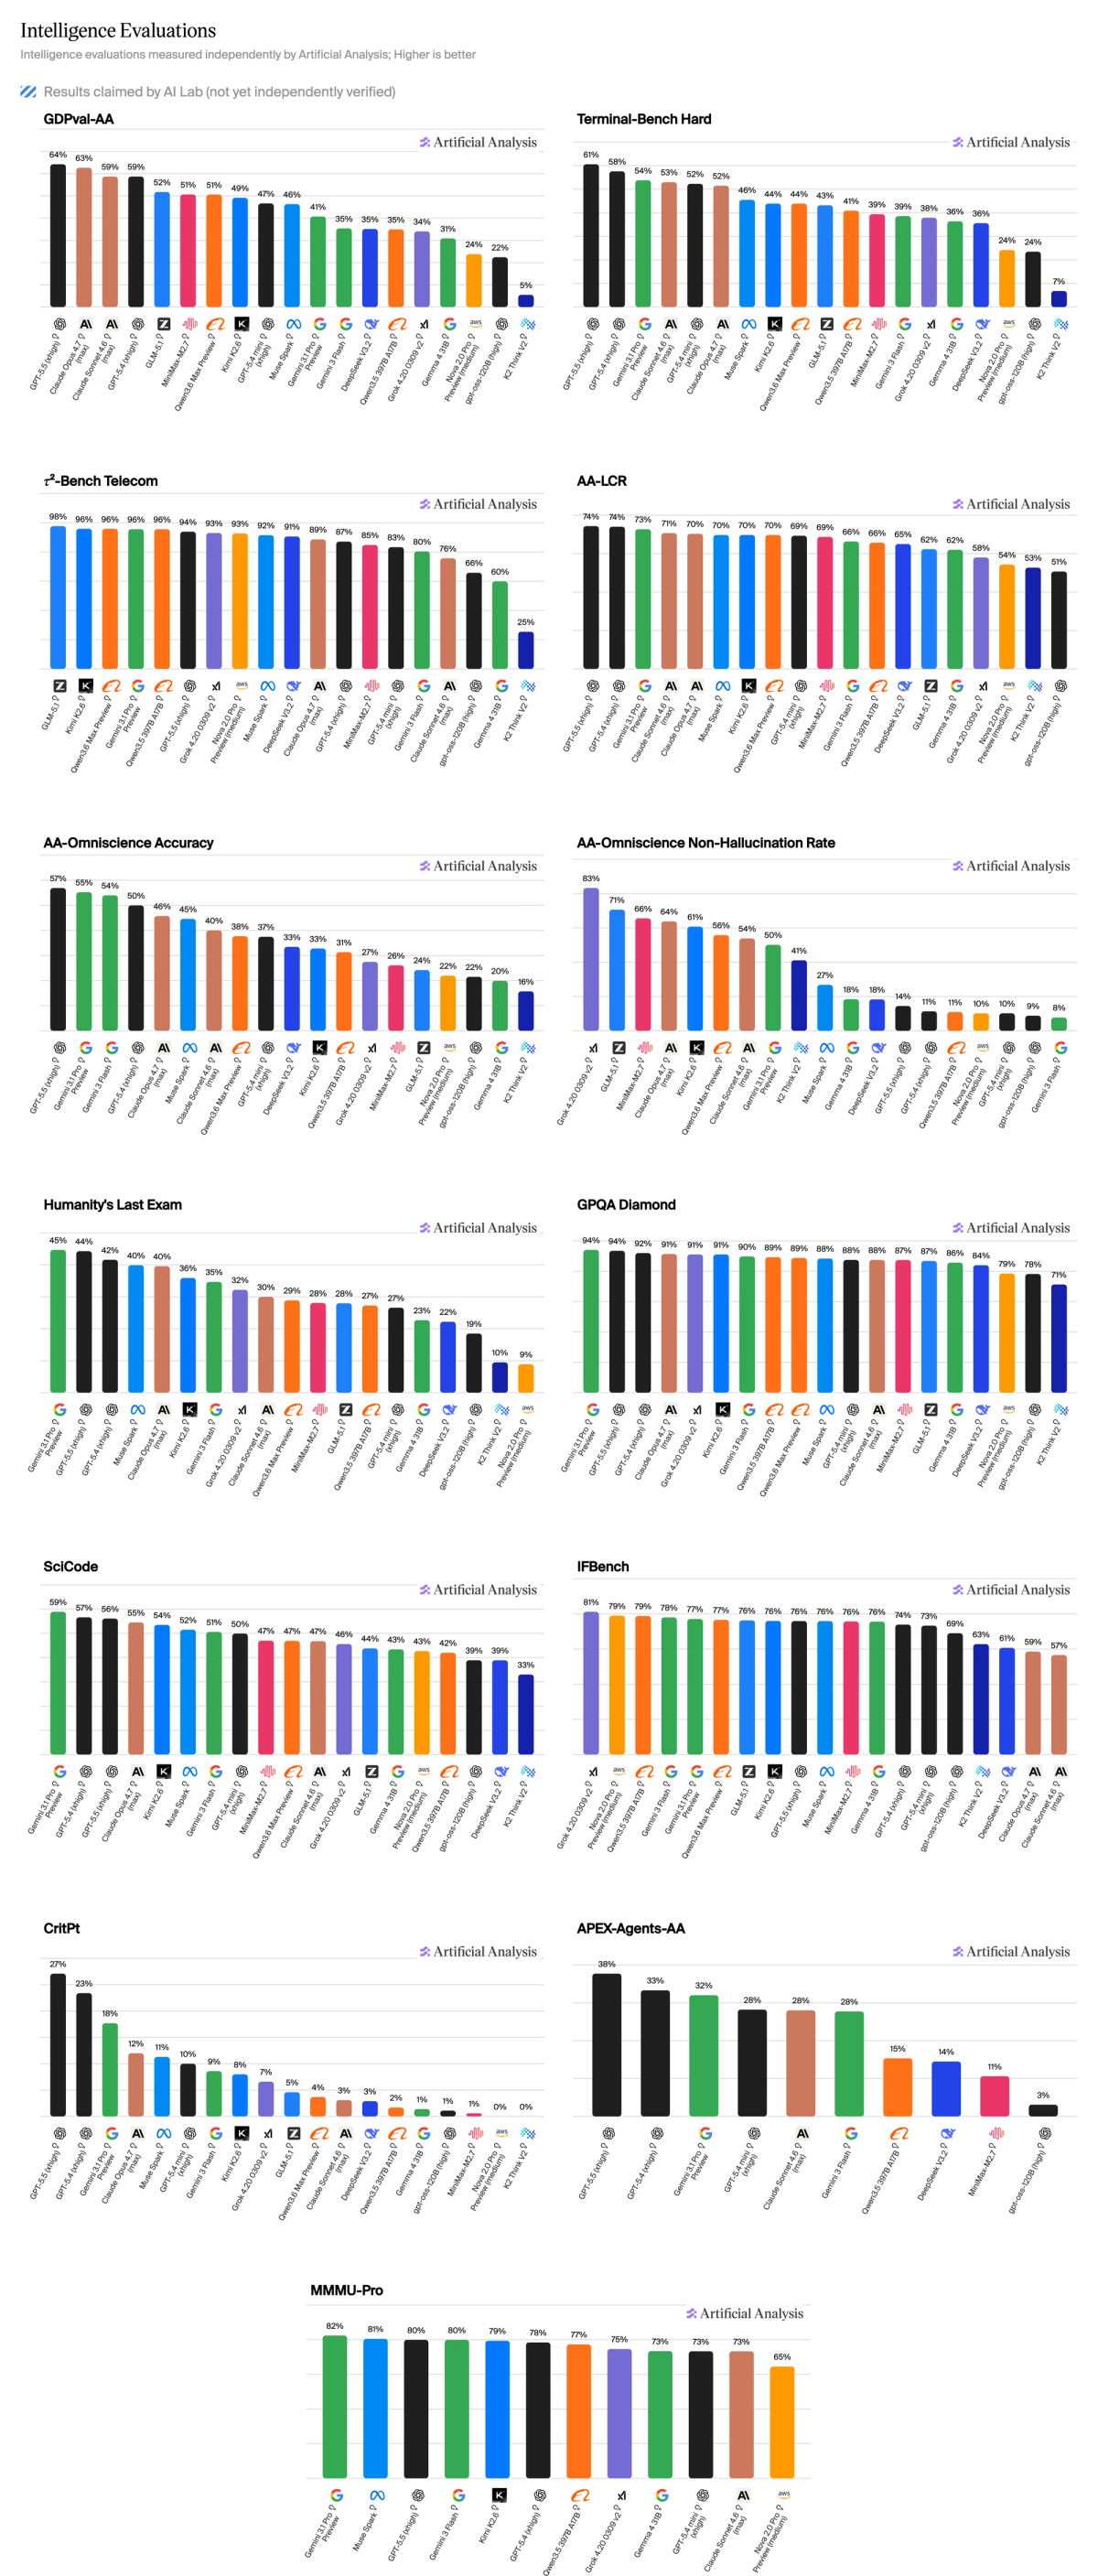 OpenAI leads five of our headline evaluations and places second to Gemini 3.1 Pro Preview on three.
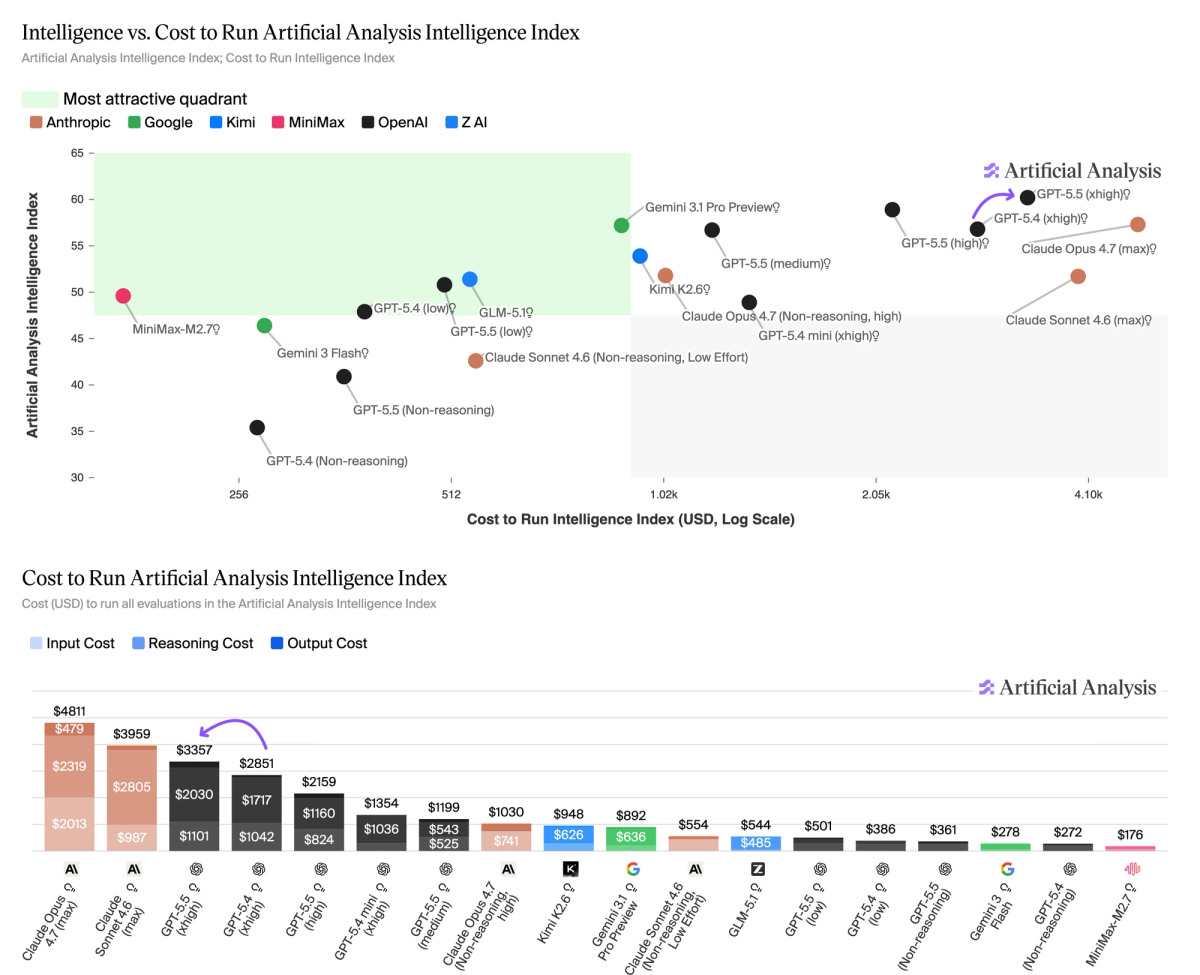 Effort variants provide a clear ladder to balance intelligence and cost. GPT-5.5 (xhigh) is ~20% more expensive to run our Index than its predecessor, but 30% cheaper than Claude Opus 4.7 (max)
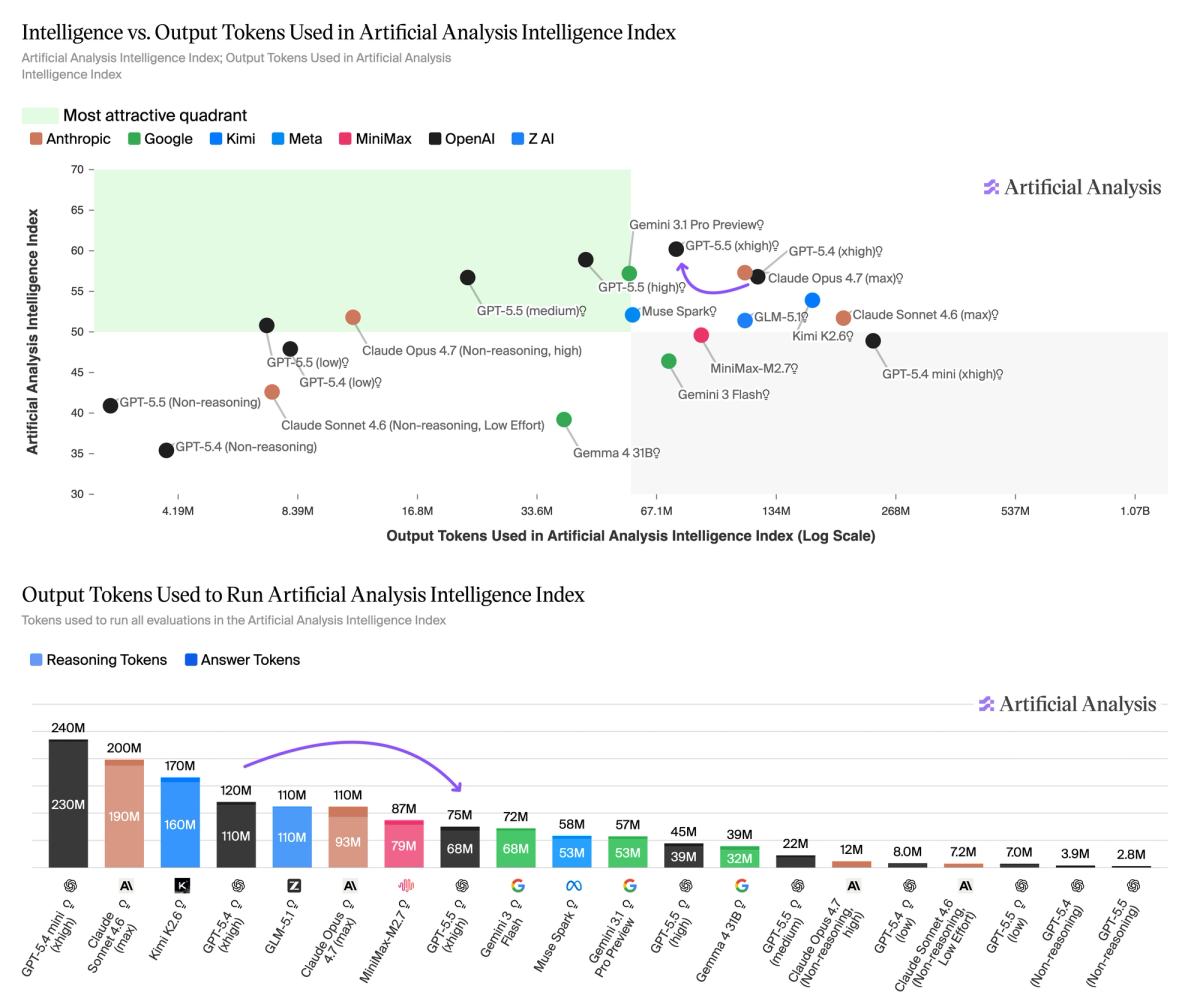 GPT-5.5 (xhigh) uses ~40% fewer output tokens to run our Index than its predecessor
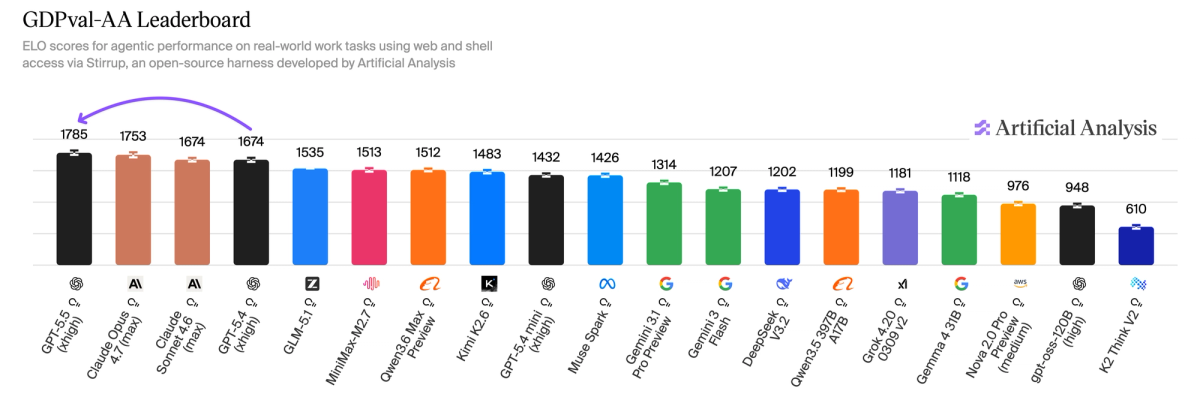 GPT-5.5 (xhigh) leads GDPval-AA with an Elo of 1785
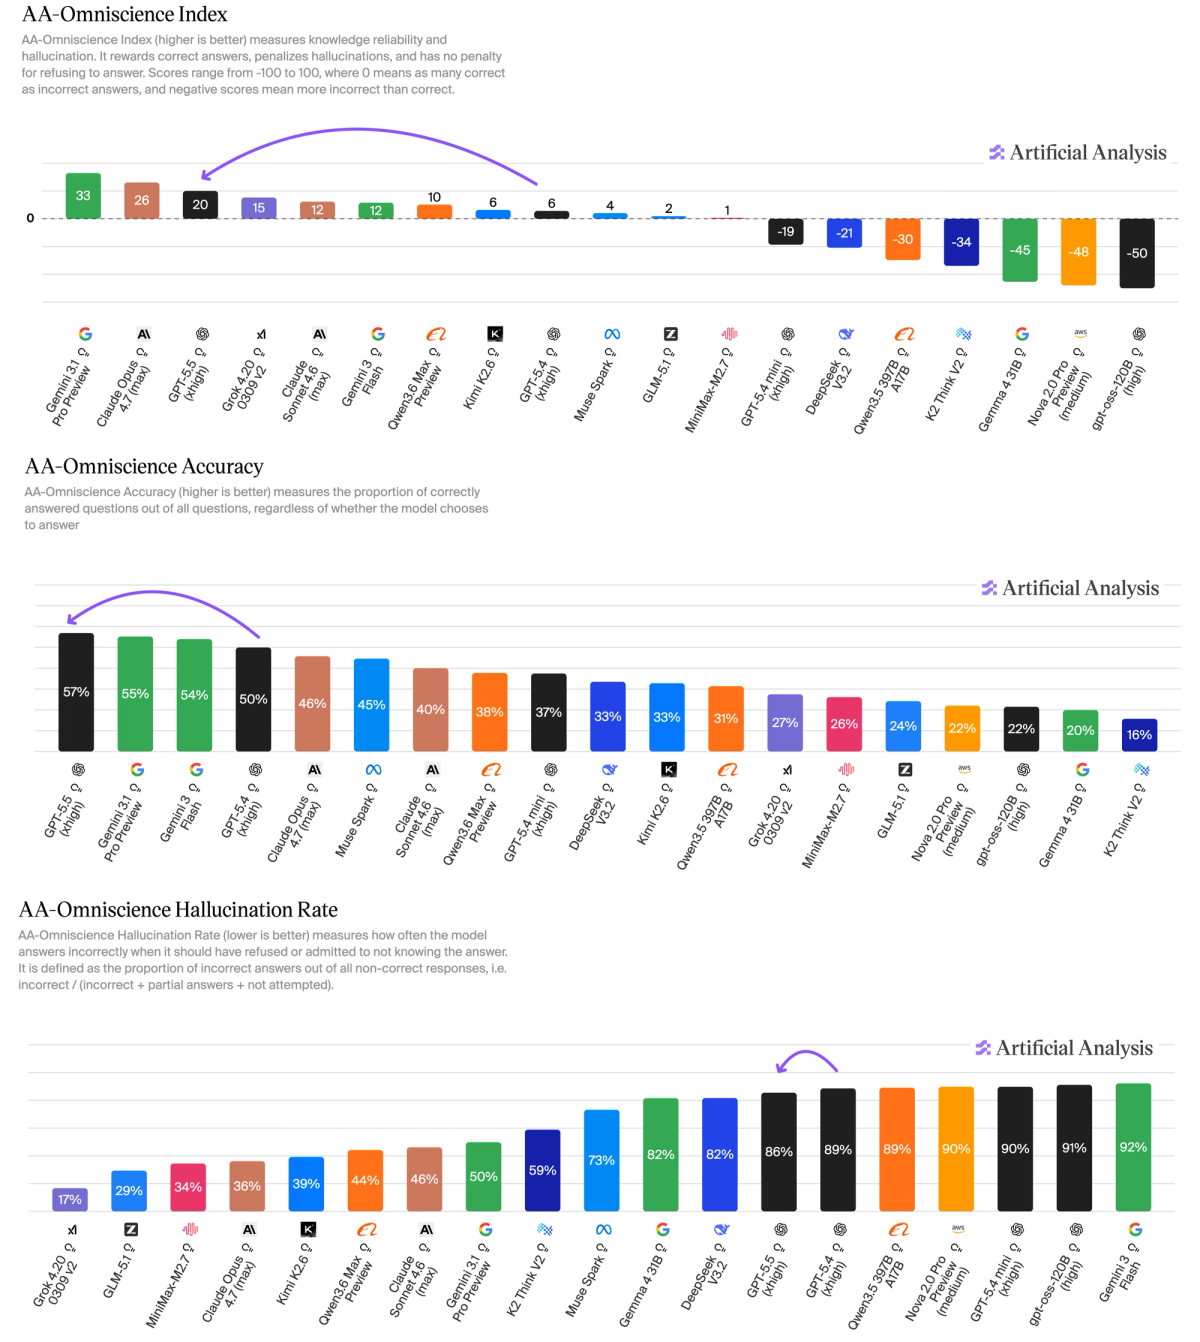 GPT-5.5 (xhigh) records our highest ever AA-Omniscience accuracy score but trails the frontier on hallucination
See Artificial Analysis for further details and benchmarks of GPT-5.5: https://artificialanalysis.ai/models/gpt-5-5
Read the latest
First AA-AgentPerf results for NVIDIA Vera Rubin NVL72
NVIDIA Vera Rubin NVL72 serves up to ~5.7x the total throughput per megawatt of GB300 NVL72 on AA-AgentPerf, with first results on DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
October 15, 2026
First AA-AgentPerf-Local results for an NVIDIA RTX Spark N1X laptop
An NVIDIA RTX Spark N1X laptop completes our local agent workload on Qwen3.8 27B in 18.7 minutes.
October 15, 2026
NVIDIA Releases Nemotron 3.5 Super VL and Nemotron 3.5 Bolt 74B A9B
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
October 15, 2026