June 9, 2026
Cohere just released North Mini Code, a small 30B parameter (3B active) open weights coding model that scores 27.6 on the Artificial Analysis Intelligence Index
See model pageLess than a month since Cohere‘s last model release, Command A+, has launched another open weights model that is optimized for coding, and much smaller at 30B total parameters and 3B active parameters.
Key Takeaways:
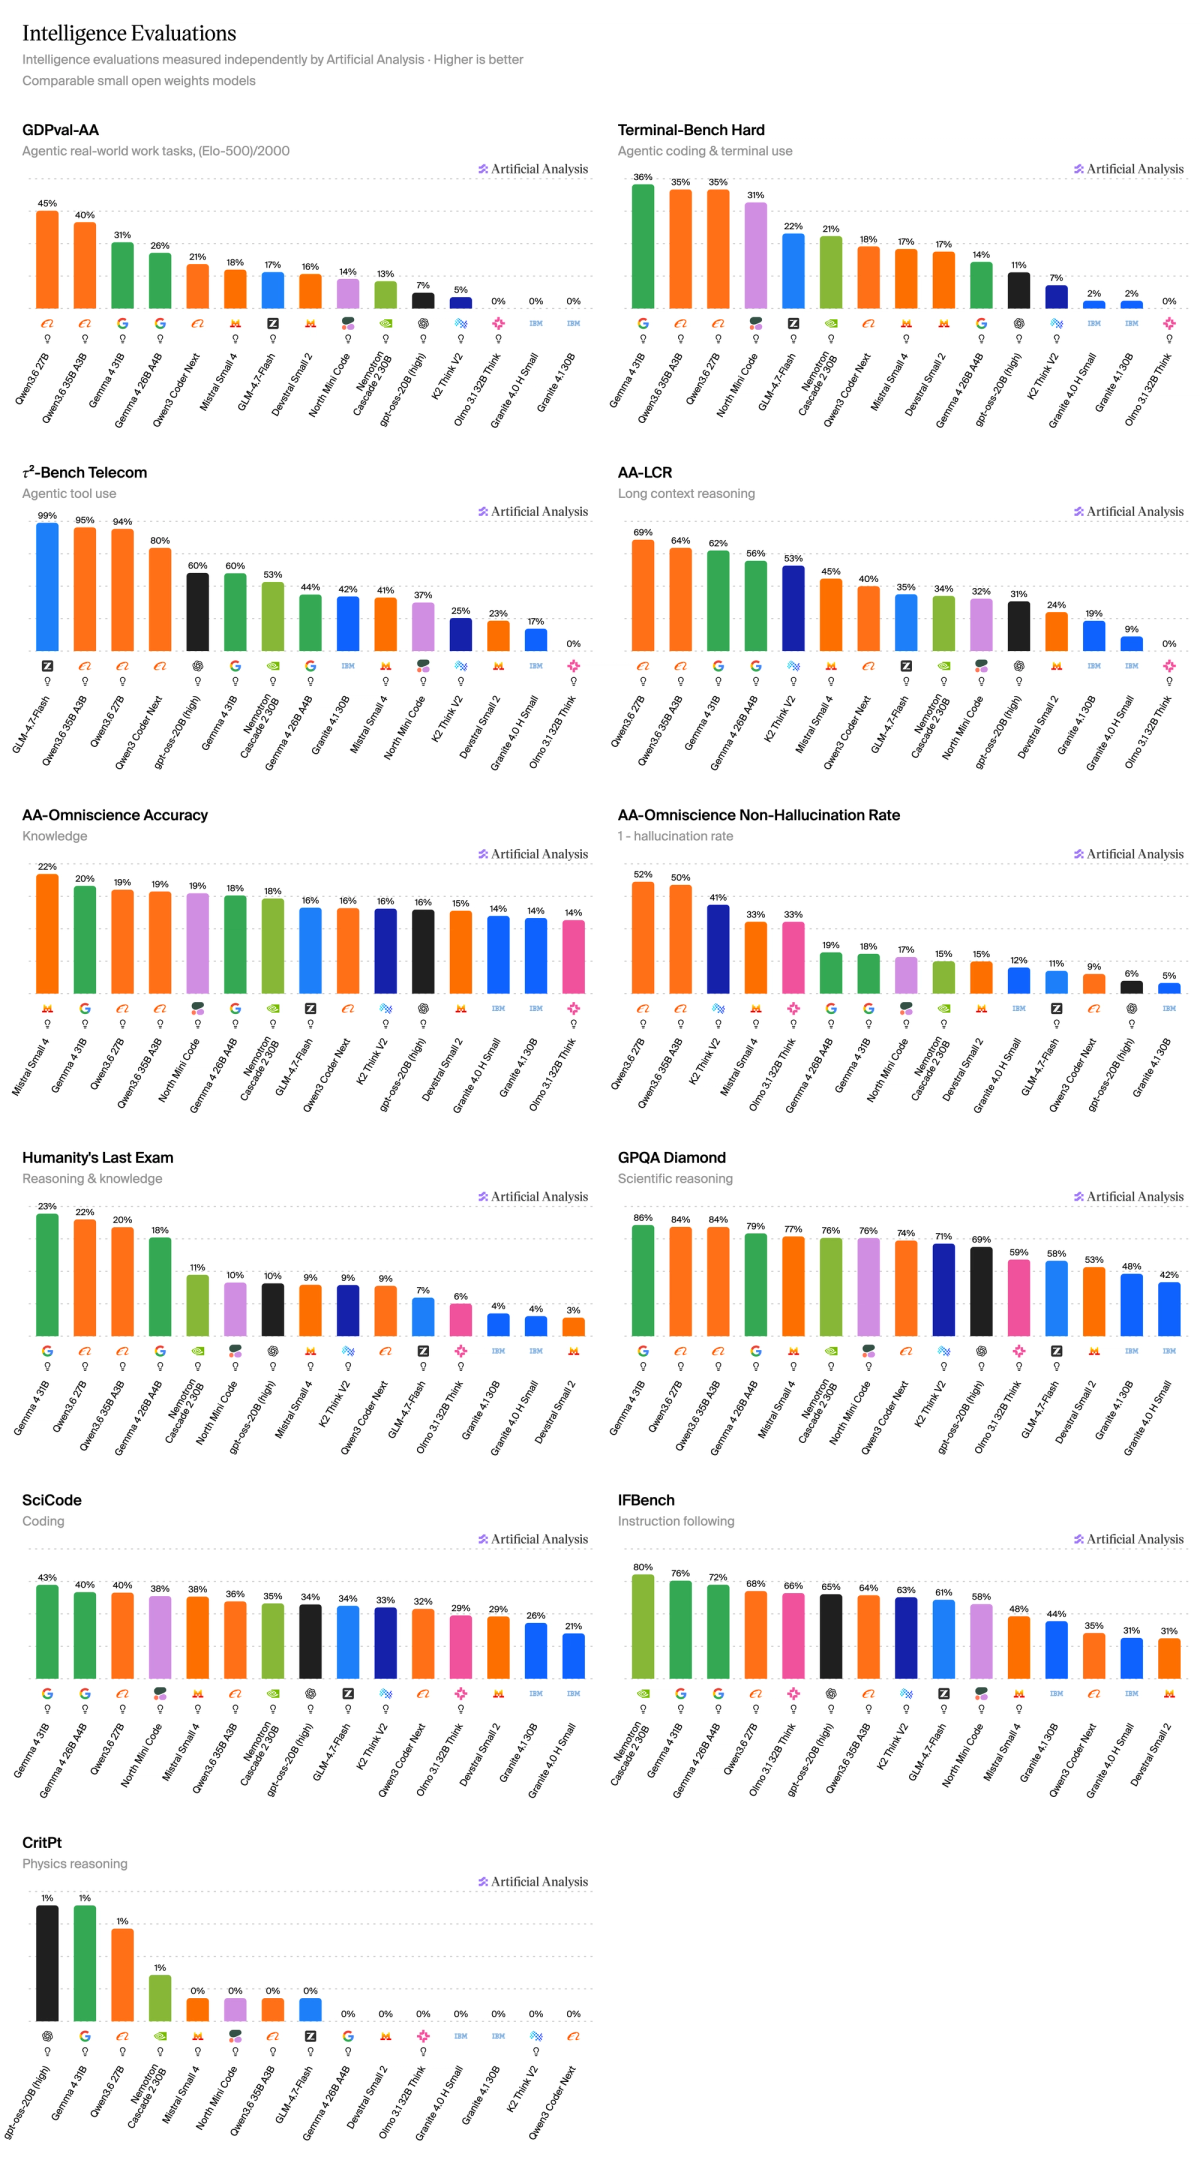
➤ Achieves 27.6 on the Artificial Analysis Intelligence Index, above gpt-oss-20B (high) at 24.5 and just below Mistral Small 4 (119B parameters, 6.5B active) at 27.8
➤ Scores competitively on the Artificial Analysis Coding Index (weighted average of Terminal-Bench Hard and SciCode) against open weights models in its size class, scoring 33.4, significantly above GLM-4.7-Flash at 25.9, and below Qwen3.6 35B A3B at 35.2. However, it underperforms on non-coding agentic tasks, scoring 14% on GDPval-AA and 37% on 𝜏²-Bench Telecom
➤ On Cohere’s API, North Mini Code is faster than several comparable open weights models of its intelligence and size class (~199 output tokens per second)
➤ North Mini Code is a text-only 30B total parameter and 3B active parameter model, and is open-sourced under the Apache 2.0 license
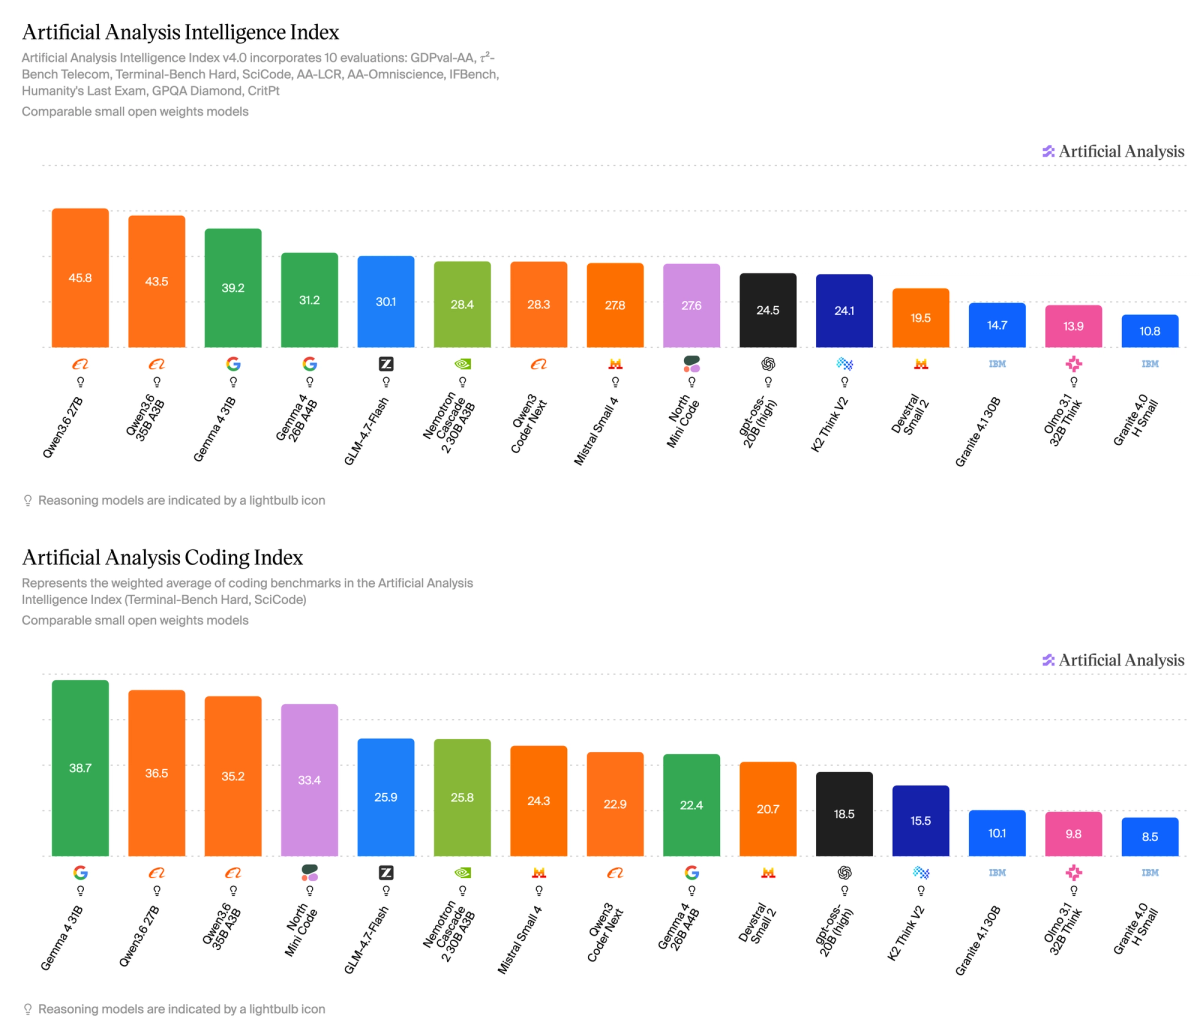
North Mini Code scores 14% on GDPval-AA and 37% on 𝜏²-Bench Telecom, resulting in an overall weighted score of 21.7 on the Artificial Analysis Agentic Index
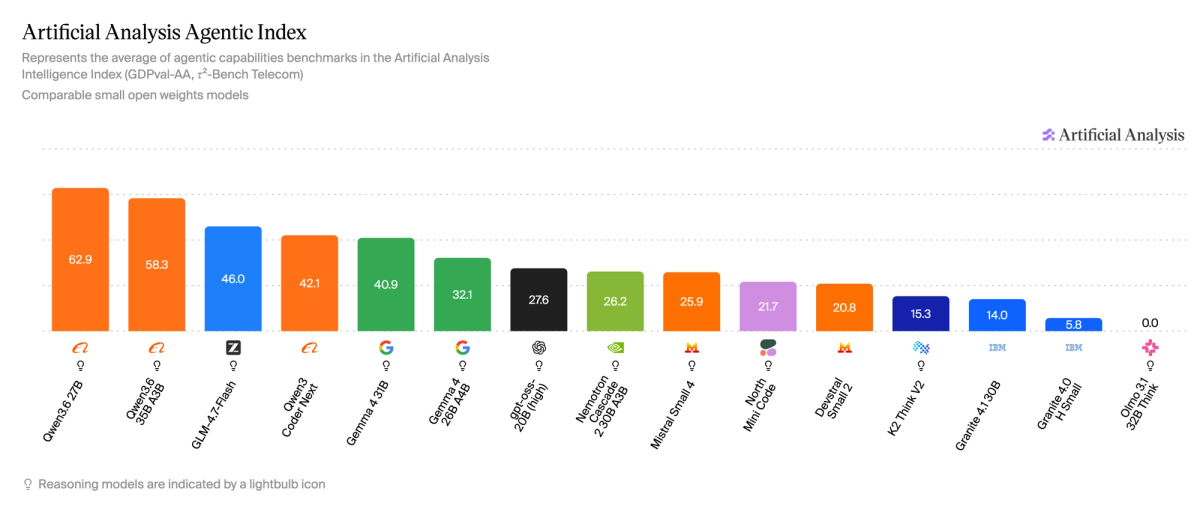
North Mini Code uses more output tokens to complete the Artificial Analysis Intelligence Index evaluations suite than most comparable models of its size and intelligence
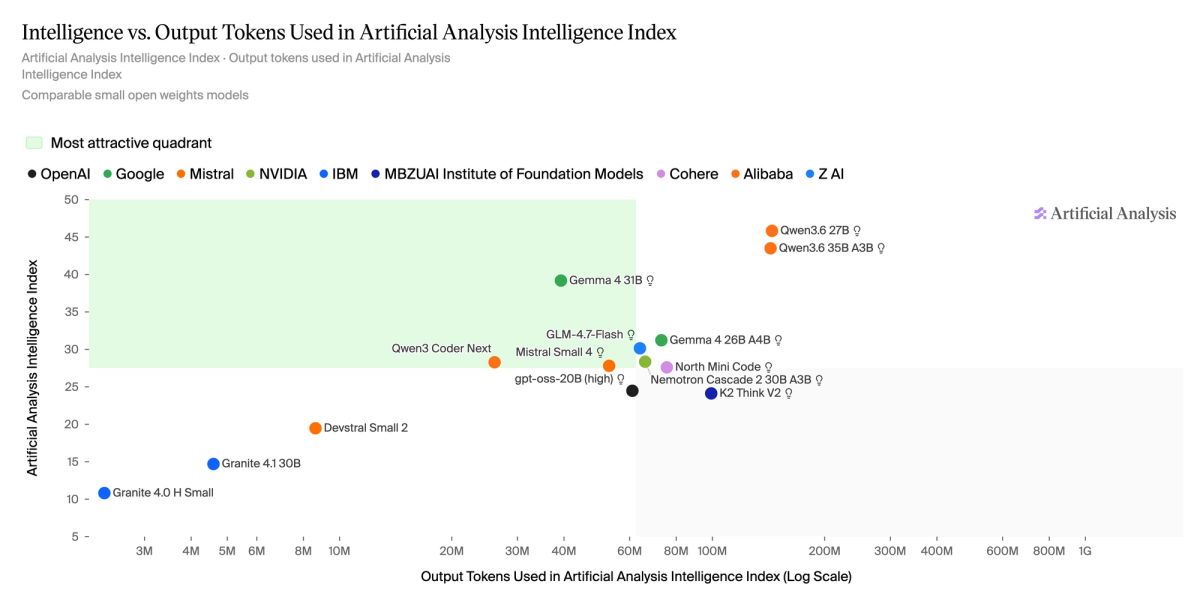
In our pre-release speed testing, North Mini Code performed above several comparable open weights models of its intelligence and size class (~199 output tokens per second)
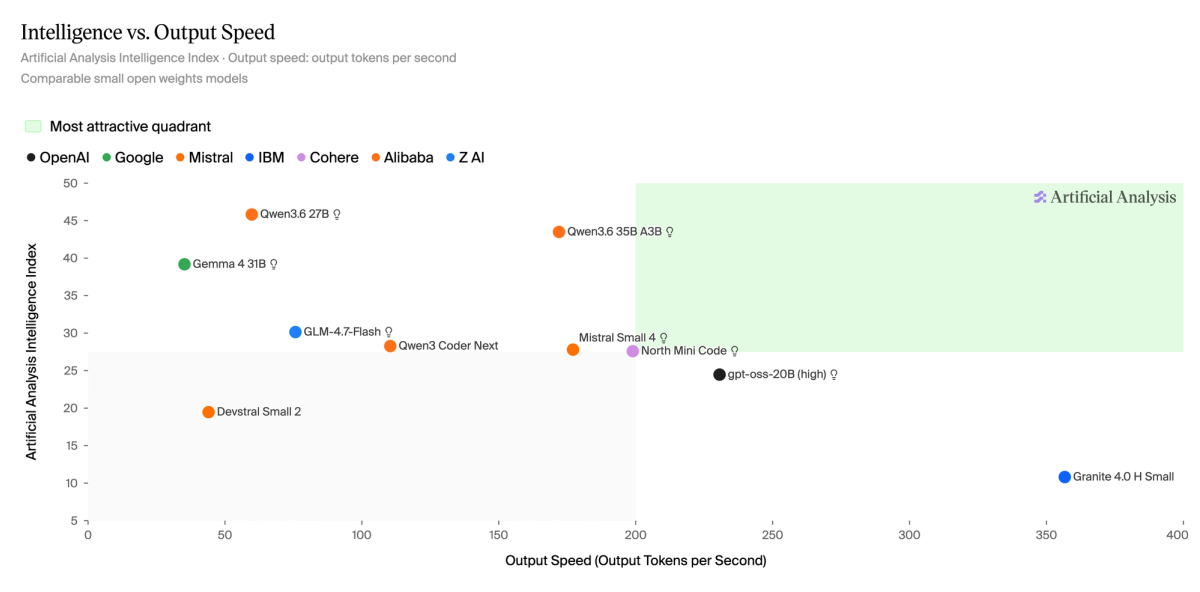
Full intelligence evaluations breakdown below:
See Artificial Analysis for further details and benchmarks: https://artificialanalysis.ai/models/north-mini-code
Read the latest
First AA-AgentPerf results for NVIDIA Vera Rubin NVL72
NVIDIA Vera Rubin NVL72 serves up to ~5.7x the total throughput per megawatt of GB300 NVL72 on AA-AgentPerf, with first results on DeepSeek V4 Pro, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
October 15, 2026
First AA-AgentPerf-Local results for an NVIDIA RTX Spark N1X laptop
An NVIDIA RTX Spark N1X laptop completes our local agent workload on Qwen3.8 27B in 18.7 minutes.
October 15, 2026
NVIDIA Releases Nemotron 3.5 Super VL and Nemotron 3.5 Bolt 74B A9B
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
October 15, 2026