September 2, 2026
Google has released Gemini 3.8 Flash, its fourth Flash model in under four months
See model pageGemini 3.8 Flash scores 59 on the Artificial Analysis Intelligence Index and reaches the Intelligence vs. Cost per Task Pareto frontier
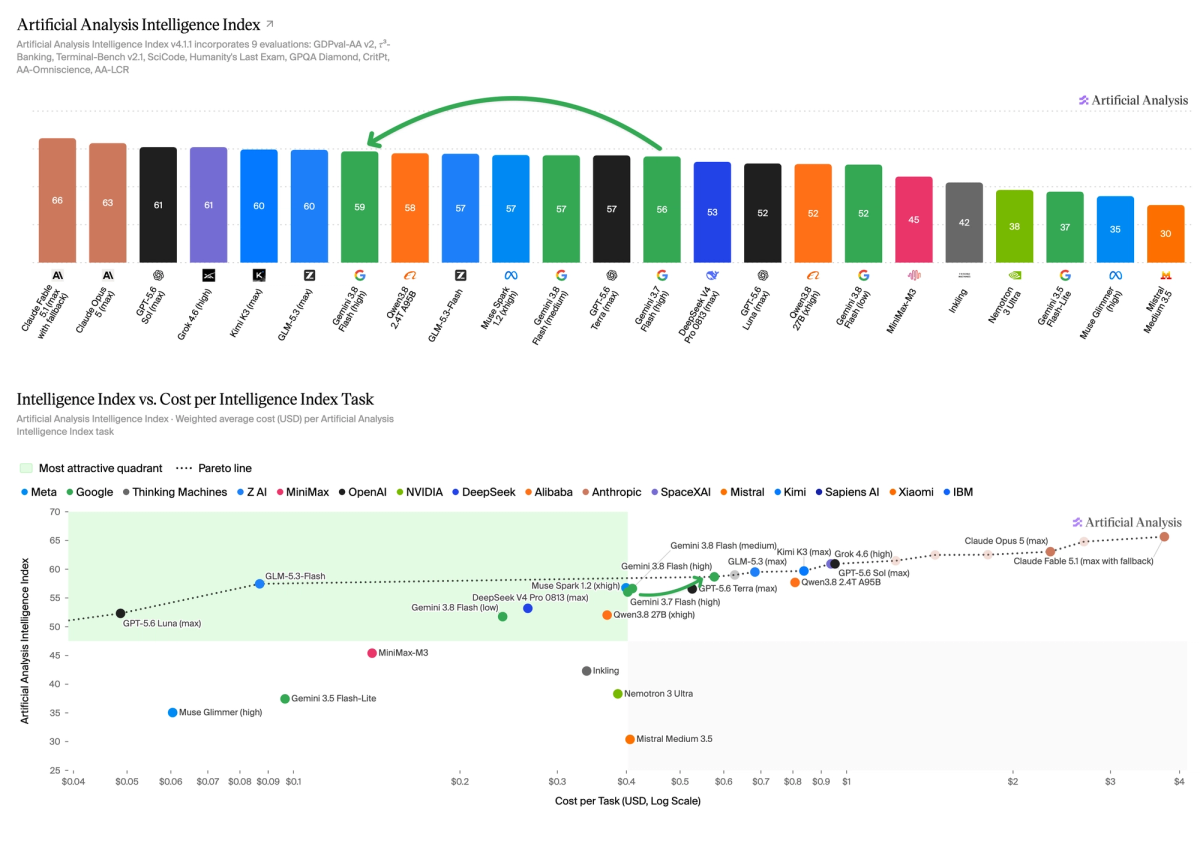
Google DeepMind released Gemini 3.8 Flash today. With high reasoning, it scores 59 on the Artificial Analysis Intelligence Index, up 3 points from Gemini 3.7 Flash and on par with sub-maximum reasoning efforts of GPT-5.6 Sol (xhigh, 59) and Grok 4.6 (medium, 59)
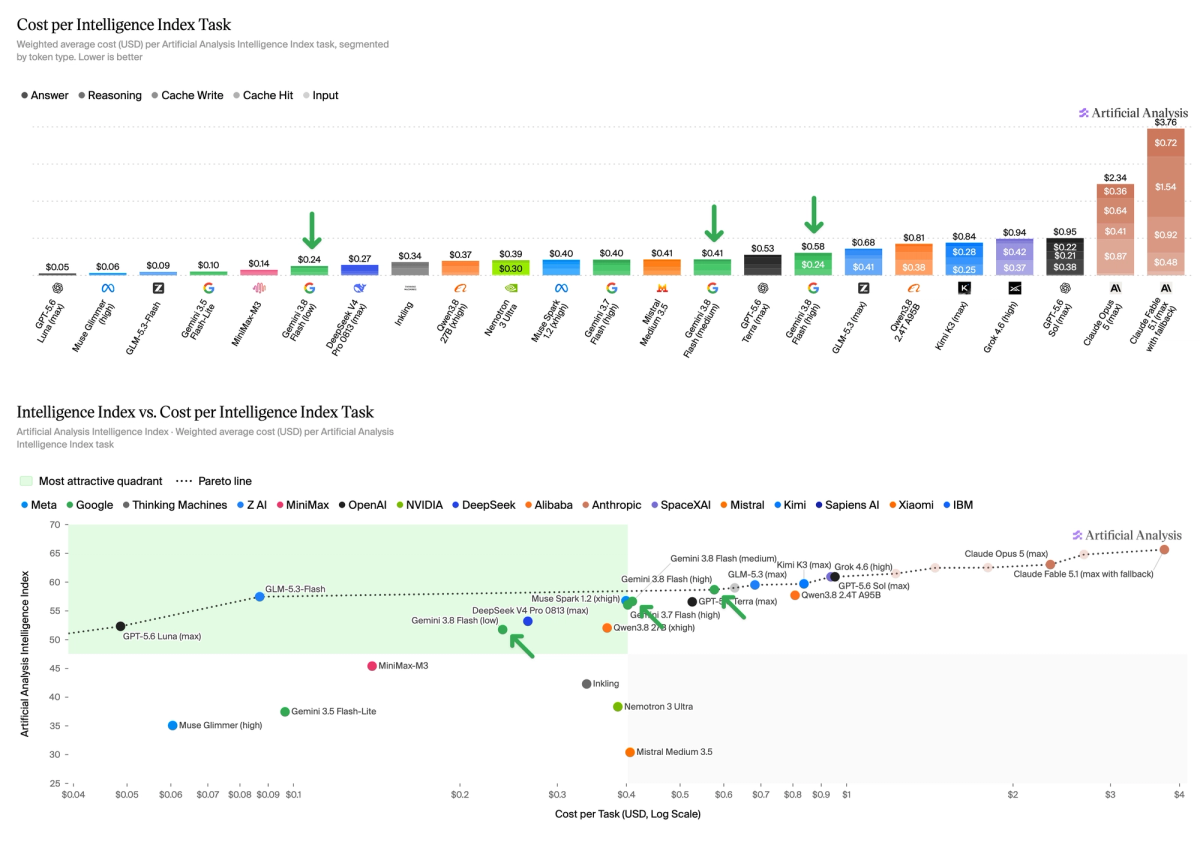
Matching Gemini 3.7 Flash’s discounted pricing until the end of the year ($0.75/$3.75 per million input/output tokens), Gemini 3.8 Flash sits on the Intelligence vs. Cost per Task Pareto frontier at $0.58 per task. This is comparable to GPT-5.6 Terra (max, $0.53), but ~40% higher than its predecessor, driven by a 30% increase in average output tokens per task to 48k and increased turns on agentic evaluations
Key benchmarking results across Gemini 3.8 Flash’s three reasoning levels:
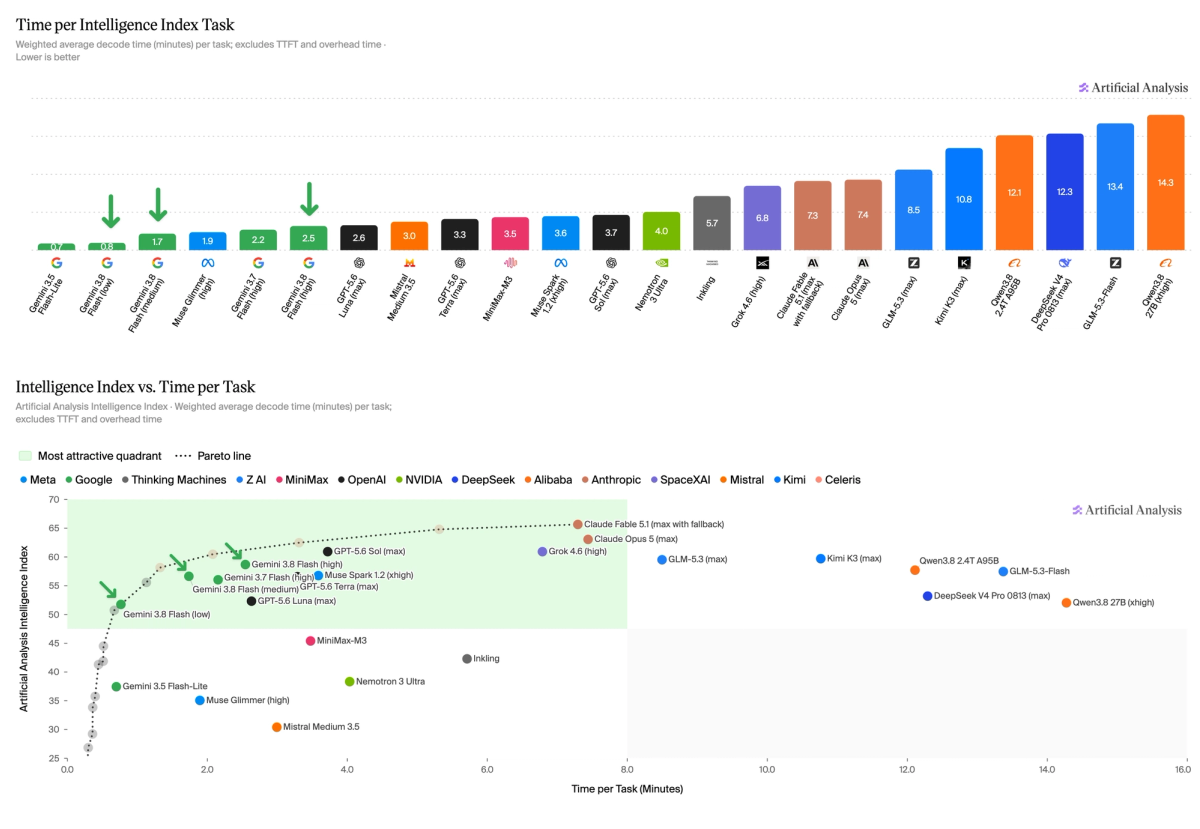
➤ 3 point Intelligence Index improvement: Gemini 3.8 Flash (high) scores 59 on the Artificial Analysis Intelligence Index, up 3 points from Gemini 3.7 Flash (high, 56). With medium reasoning it scores 57, matching GPT-5.6 Terra (max, 57) and Muse Spark 1.2 (xhigh, 57). With low reasoning it scores 52, matching Gemini 3.6 Flash (high, 52), at 30% lower Cost per Task and roughly a third of the Time per Task
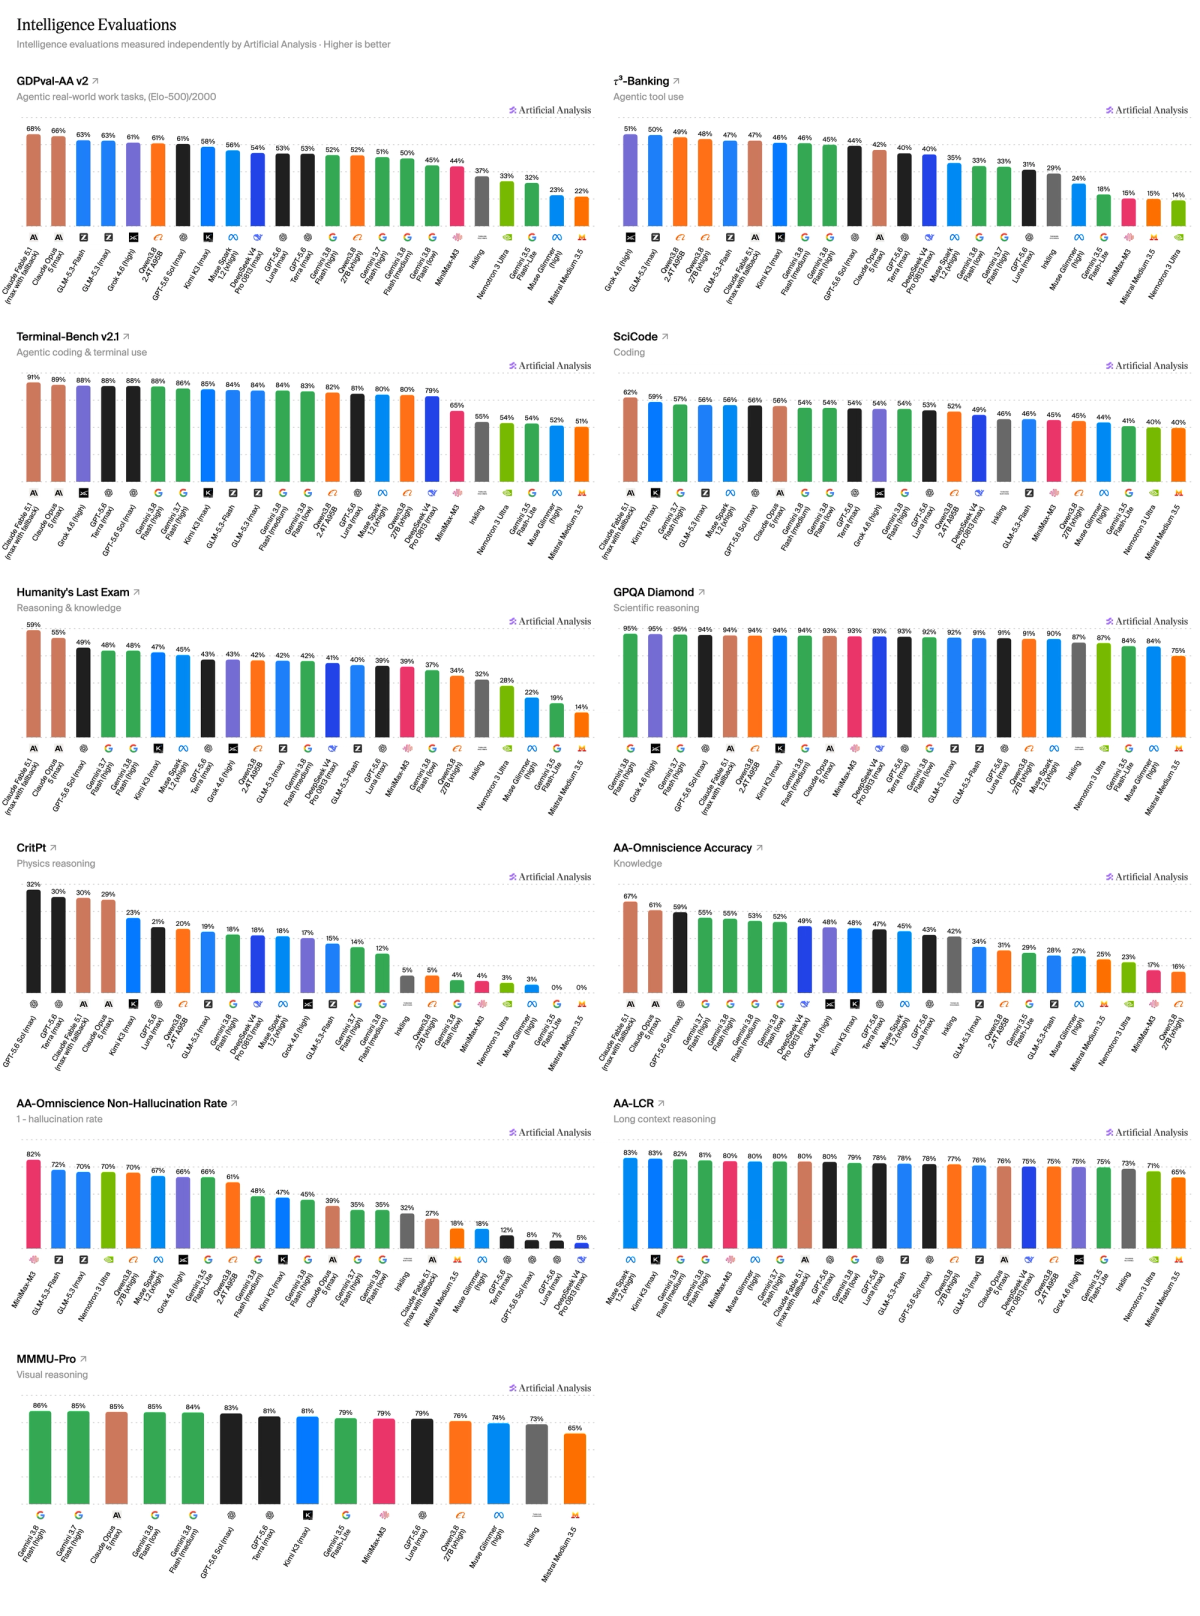
➤ Agentic capability improvements: Gemini 3.8 Flash’s 3 point improvement on the Artificial Analysis Intelligence Index is primarily driven by stronger performance on agentic evaluations such as 𝜏³-Banking (tool use), Terminal-Bench v2.1 (coding) and GDPval-AA v2 (real-world tasks). The largest improvement is on 𝜏³-Banking, where it gains 12 points over Gemini 3.7 Flash to score 45%
➤ Pareto frontier on Intelligence vs. Cost per Task: Gemini 3.8 Flash (high) costs $0.58 per Intelligence Index task, making it the cheapest model at its level of intelligence. This is up ~40% from Gemini 3.7 Flash ($0.40) despite unchanged per-token pricing, driven by a 30% increase in output tokens per task and more turns on agentic evaluations. Cost per Task falls to $0.41 with medium reasoning and $0.24 with low reasoning
➤ Output speeds remain fast, but Time per Task increases: On high reasoning, Gemini 3.8 Flash averages ~300 output tokens per second and a Time per Task of 2.5 minutes, slightly faster than GPT-5.6 Luna (max, 2.6 minutes) and GPT-5.6 Terra (max, 3.3). Compared to Gemini 3.7 Flash, higher token usage increases Time per Task from 2.2 minutes to 2.5 minutes, and puts it behind Claude Fable 5.1 (medium, 2.1 minutes). On low reasoning, Time per Task falls to 0.8 minutes, placing Gemini 3.8 Flash on the Intelligence vs. Time per Task Pareto frontier
Key model details:
➤ Context Window: 1M tokens, unchanged from Gemini 3.7 Flash
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $0.75/$3.75 per 1M input/output tokens through the end of the year, matching Gemini 3.7 Flash’s current discounted pricing. $1.50/$7.50 per 1M input/output tokens at standard pricing. Cached input tokens retain the same 90% discount
Read the latest
Korean AI Lab Upstage releases Solar Mini 4
Korean AI Lab Upstage has released Solar Mini 4 which scores 24 on the Artificial Analysis Intelligence Index, but costs ~5x as much per task as GPT-6 Luna (max) despite similar per-token prices
September 30, 2026
Gemini 4 Argon: Google is back as one of the top three labs in intelligence achieved
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
September 30, 2026
AA-AgentPerf-Local: Benchmarking local AI agents on laptops and workstations
Our open-source tool for testing how fast agentic AI runs on laptops and workstations, with launch results for the DGX Spark, Ryzen AI Halo, MacBook Pro (M5 Pro) and RTX 5090 across four open-weights models
September 29, 2026